
Listen to this article
Jump to a section
In this article
Executive Summary
A formal proof language such as Lean lets a machine certify that a proof is correct, step by step, with no human referee. In September 2026 Anthropic reported that Claude, working largely on its own for 11 days, wrote a complete Lean proof of Fermat’s Last Theorem, about 13 million lines long. Lean accepted it, and the mathematician Kevin Buzzard, who reviewed it, said it proves the theorem “with no assumptions other than the axioms of mathematics.” No person has read all of it, and nobody is expected to. This is where truth and expertise start to separate. A result can be certainly correct and understood by no one. In July 2026 the same kind of checker also accepted a false disproof of the Collatz conjecture, because of a bug in its kernel. Thomas Hales, who proved the Kepler conjecture and led the project to formalise it, now says “we absolutely cannot put blind trust in systems such as Lean.” For leaders the useful question is narrow: what exactly did the check cover, and who owns the rest?
11 days
time Claude agents took to write a Lean proof of Fermat’s Last Theorem, per Anthropic, September 2026
~13 million
lines of Lean in that proof, over five times the size of Mathlib, the library it builds on
3
standard axioms the proof relies on, and nothing else assumed
2 bugs
in two independent checkers were needed to pass a false Collatz “disproof” in July 2026; both are fixed
Core conclusions
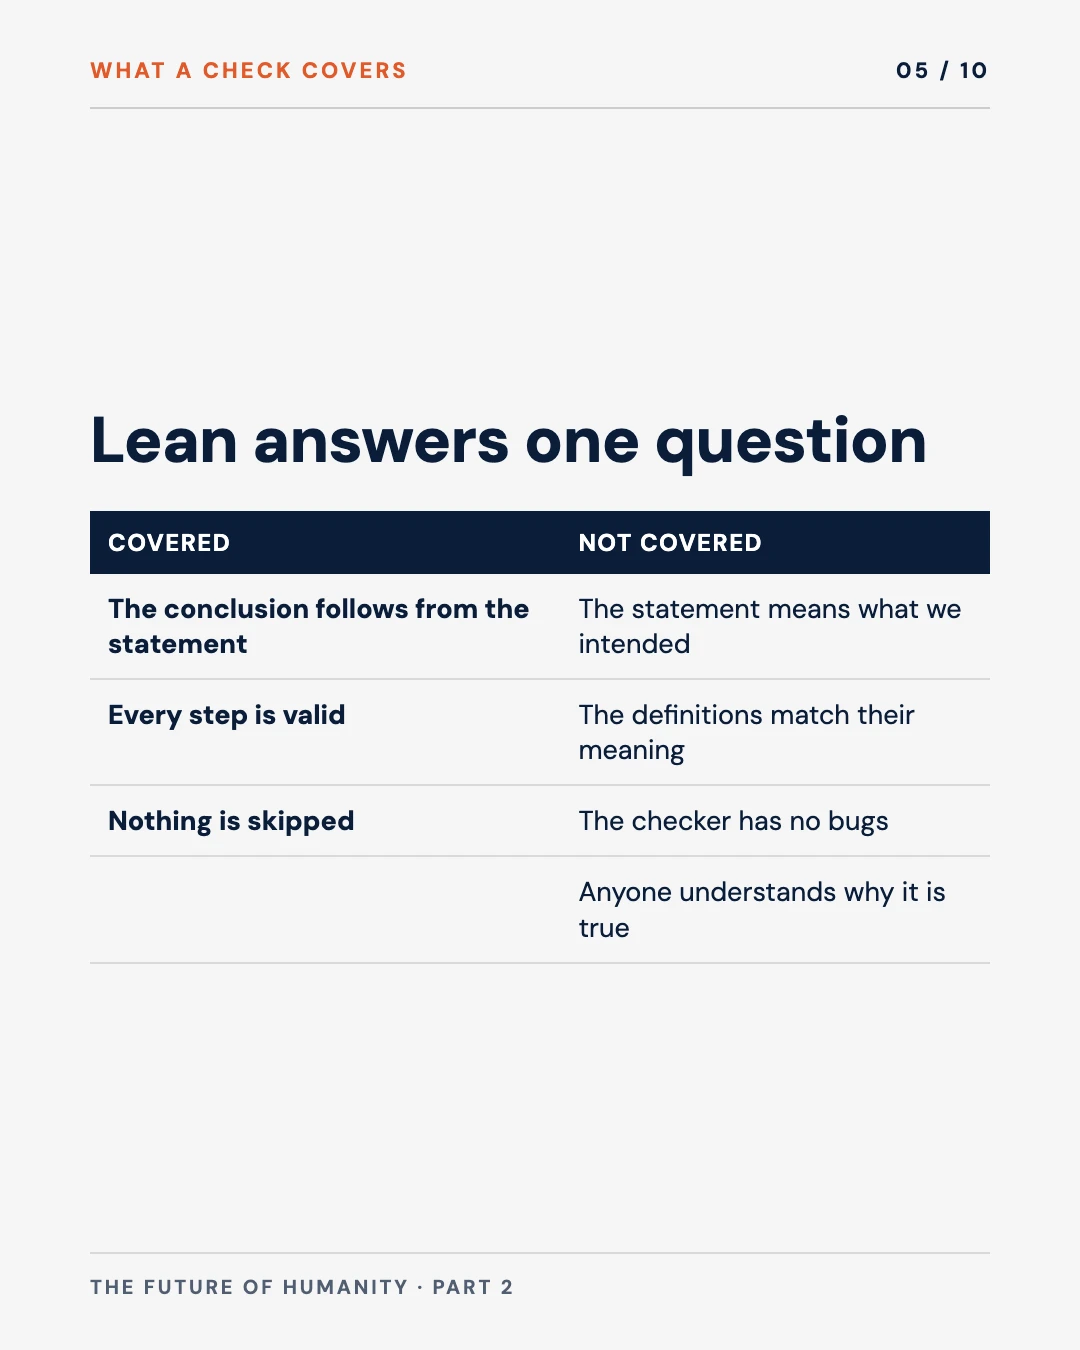
- A machine check settles one question only: does this conclusion follow from this statement? It does not tell you whether the statement means what you intended, or whether anyone understands why the result is true.
- The checker is software and can have bugs. Cross-checking with a second checker helps a great deal, though not completely.
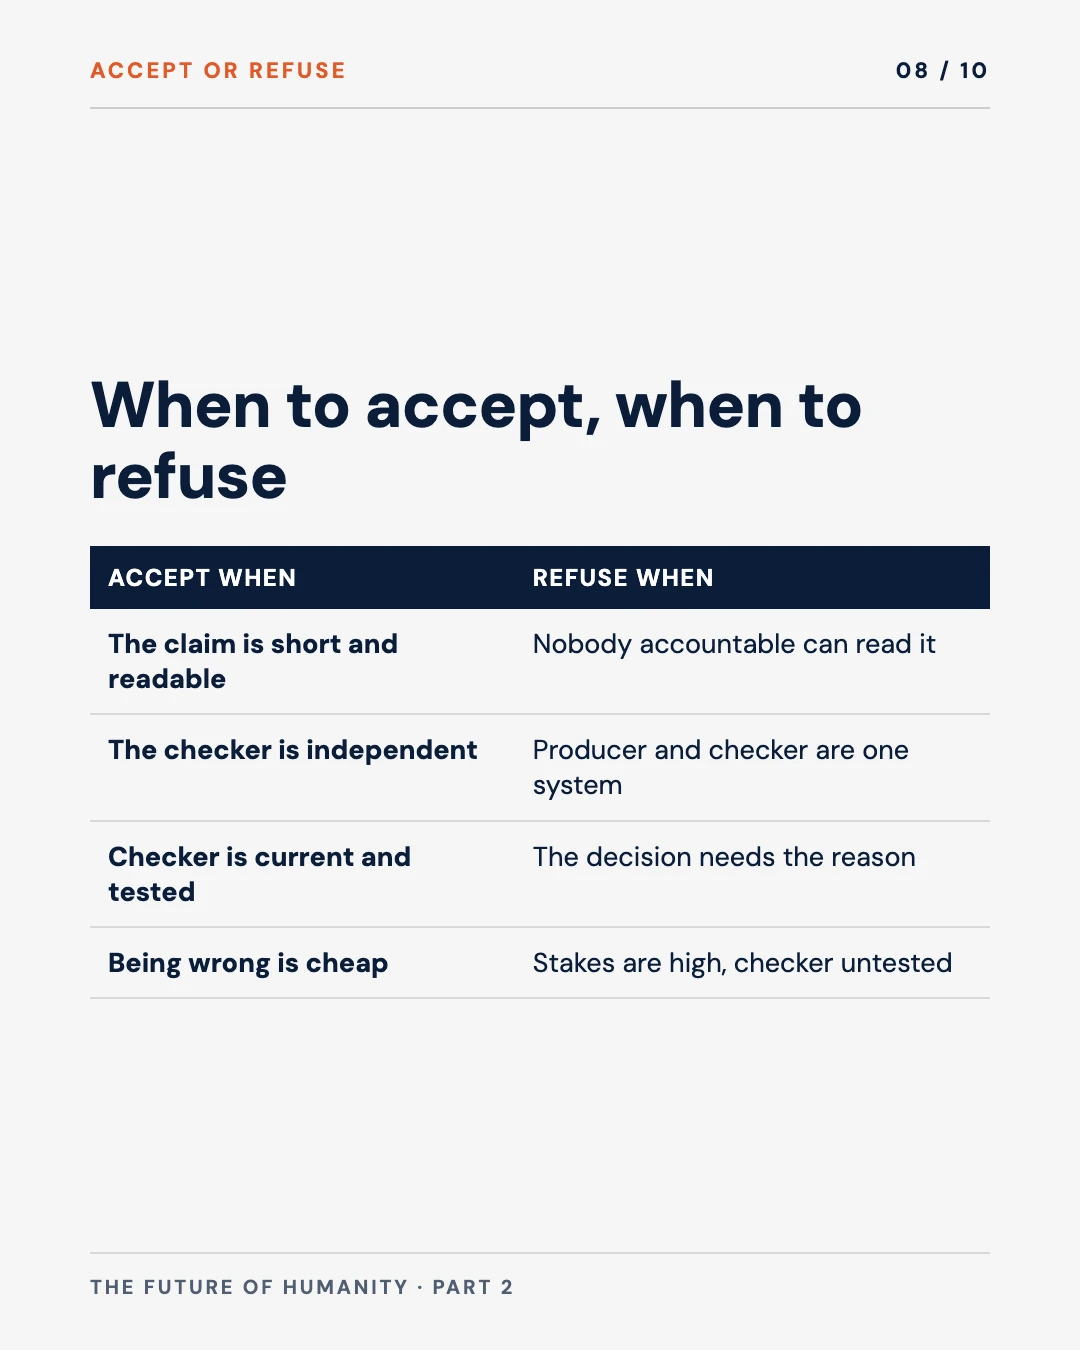
- Accept a result you cannot follow when the claim is small and readable, the check is independent and current, and being wrong is cheap. Refuse when nobody accountable can read the claim, or when the decision needs the reason and not only the answer.
The argument, in ten slides
Save it, or send it to whoever signs off AI-generated work in your organisation.
A proof nobody can check by hand
Mathematics has argued about this once before. In 1976 Kenneth Appel and Wolfgang Haken proved the four colour theorem, which says any map can be coloured with four colours so that no two neighbouring regions match. Their proof reduced the problem to 1,936 configurations and needed more than a thousand hours of computer time to check them. Many mathematicians objected. A proof, they said, is something a person can check, and this one was not. Errors were also found in the original, and corrected versions followed.
The field eventually accepted the result, and in 2005 Georges Gonthier completed a fully computer-checked proof of the theorem in the Coq proof assistant. That was the first sign of what is now routine. A proof assistant is software in which the proof is written in a strict formal language and a small piece of code, the kernel, checks every step. Lean is the one most mathematicians use today. Thomas Hales, who proved the Kepler conjecture in 1998, later led Flyspeck, a project to formalise his own proof.
The old objection was that nobody can check the computer’s work. The new situation reverses it. The checking is now the one thing a machine does more reliably than a person. What nobody can supply is the reading.
What a Lean check guarantees
A proof in Lean is accepted or rejected, with no middle ground. If the kernel accepts it, then the conclusion follows from the stated assumptions by valid logical steps. That is a stronger guarantee than a human referee gives. A referee skims the routine parts and trusts the author. The kernel checks every line.
It answers one question only. The conclusion follows from what was stated. Three things sit outside that guarantee.
Whether the statement says what we meant. A formal statement can be a faithful translation of the question, or a slightly different one that happens to be provable. Hales calls the discipline statement fidelity and writes that “a proof in Lean should not be accepted until a human audit is performed to ensure statement fidelity.” The same applies to the definitions the statement uses.
Whether the checker itself is sound. The kernel is a program. It has been tested heavily and is small compared with the proofs it checks, but it is still code.
Whether anyone understands why it is true. Lean does not care. Terence Tao put the question to the International Congress of Mathematicians in July 2026: “Could we have a verified proof of a major result that no human understands enough to explain it?”
The machine checks the middle of the chain. People still own both ends.
Schematic. Links 2 and 3 follow Thomas Hales: "a proof in Lean should not be accepted until a human audit is performed to ensure statement fidelity" (guest post on Terence Tao's blog, 9 October 2026). Link 6 follows Tao's question at ICM 2026, whether there could be "a verified proof of a major result that no human understands enough to explain it".
The left side of this chain is about meaning and the right side is about understanding. The middle is the part machines now do better than we do. That is why the mismatch from Part 1 bites: the part that scales is the part that was already easy to trust.
A machine proves Fermat’s Last Theorem
On 4 September 2026 Anthropic’s science team published an account of a Lean proof of Fermat’s Last Theorem. A full disclosure first: Anthropic makes the Claude models I work with every day, so this is the maker’s own account, and I treat it as one.
According to Anthropic, Claude agents worked largely autonomously for 11 days, with occasional high-level instructions from the researcher who set the task. The output is about 13 million lines of Lean, over five times the size of Mathlib, the community library of formalised mathematics it builds on. It contains about 30,300 proved theorems, of which 29,500 are used in the final proof. Anthropic reports about six billion output tokens of compute. The proof follows a simplified version of Andrew Wiles’s argument, as laid out by Darmon, Diamond and Taylor, and uses only Lean’s three standard axioms. A separate comparison tool confirmed that the theorem Lean checked matches Mathlib’s own statement of Fermat’s Last Theorem.
Kevin Buzzard, who leads a human effort to formalise the same theorem at Imperial College London, reviewed it. He wrote that it “proves Fermat’s Last Theorem with no assumptions other than the axioms of mathematics”, and that “AI autoformalization artefacts are now robust enough to be built upon.”
Five Mathlibs of code that no person is expected to read
Source: Anthropic, Formalizing Fermat's Last Theorem, 4 September 2026. Bar lengths are schematic, drawn from Anthropic's "over 5x the size of Mathlib". Anthropic notes the proof is probably much longer than necessary.
Three details matter more than the headline.
- This was not a new proof. Fermat’s Last Theorem was proved by Wiles in 1995. The novelty is the formal, machine-checked version.
- The statement check was narrow. The reassurance that the right theorem was proved came from matching Mathlib’s existing statement, which human mathematicians wrote and have reviewed. That is the safest design, and it is worth noticing why it works. The statement is short and readable. The 13 million lines are not.
- The proof is probably far longer than it needs to be. Anthropic’s own footnote says so, and about 7 per cent of the non-boilerplate lines came from early failed attempts.
Anthropic also states that a formalised proof should not replace a human-readable exposition. I agree, and so does the next section.
The summer the checker was fooled
On 25 July 2026 a public repository appeared claiming an AI-assisted disproof of the Collatz conjecture, one of the most famous open problems in mathematics. Lean accepted it. So did a second, independently written checker called nanoda. Three days later Kiran Gopinathan reduced it to a short proof of False, the statement that a contradiction is true, and opened an issue.
The cause was a bug in the kernel’s handling of nested inductive types, a way of defining data structures. Leonardo de Moura, Lean’s creator, wrote the postmortem. A fix was pushed about an hour after the report, and Lean 4.32.2 followed on the same day. He is clear about what kind of failure it was: “an implementation bug, not a hole in Lean’s meta-theory”. The exploit also had to go through metaprogramming, and it passed nanoda only because nanoda had its own separate bug.
A false "proof" passed two independent checkers, and was fixed within a day.
Sources: de Moura, Postmortem for Kernel Soundness Bug 14576, 1 August 2026; Lean 4.32.2 release notes, 28 July 2026; Hales, guest post on Terence Tao's blog, 9 October 2026. The bug was reachable only through metaprogramming. Exploiting it needed two separate bugs in two separate checkers.
”We absolutely cannot put blind trust in systems such as Lean.”
Thomas Hales Guest post on Terence Tao's blog, 9 October 2026
Thomas Hales
Mathematician, proved the Kepler conjecture
"A proof in Lean should not be accepted until a human audit is performed to ensure statement fidelity."
Terence Tao
Fields Medallist, UCLA
"Could we have a verified proof of a major result that no human understands enough to explain it?"
Photos: Thomas Hales, Slawekb, CC BY-SA 3.0, cropped; Terence Tao, Institute for Pure & Applied Mathematics, CC BY 4.0, cropped.
I read this as good news with a lesson attached. The system worked: the exploit was found within days, fixed within hours, and written up openly. It also showed that “two independent checkers agreed” is not the same as “the result is true”, and Hales says so directly: “Cross-checking the proof by different kernels does not remove all doubt,” because “different kernels might have the same defects.” His concern for the longer term is that the AI tools that find such bugs could also plant a hidden one. He asks for several independent checkers, ideally one designed from scratch without sharing code, and for people to keep auditing the foundations.
Understanding is a separate product
Suppose the check is sound and the statement is right. A correct result nobody understands is still a poor asset, and Tao’s lecture is blunt about why. Mathematicians do not only want to know that a theorem is true. They want the idea, because the idea is what lets the next person prove something new. He cites William Thurston’s point that mathematics is not a production quota of theorems.
Tao also warns about a quieter effect. AI-written proofs are very well presented, but the writing “dwells at length on trivialities, while passing very briefly through (or even obscuring) the most interesting and novel portions of the argument.” Over-polished exposition removes the natural friction that tells a human reader where the difficult step is. In his words, it may remove friction “without actually encouraging the reader to learn and understand the key ideas of the argument."
"Paradoxically, ‘mistakes’ in human exposition can ultimately be helpful to the reader!”
Terence Tao Mathematics in the Age of AI, ICM 2026
This is what happens to expertise. Not all of it disappears. The part that becomes less valuable is reproducing a derivation by hand. The part that becomes more valuable is writing the right question, auditing the formal statement, and explaining a result well enough that others can build on it. Those are the skills I flagged in What You Can Do Without AI Is What I Hire For.
When to accept a result you cannot follow
Most of us accept results we cannot follow every day. I cannot verify the firmware in my phone or the structural calculations behind a bridge. I rely on a chain of institutions, tests and track records. Machine-checked AI output is a new link in that chain, and I would accept it under these conditions:
- The claim is short and readable. Someone accountable can read the statement, even if nobody reads the proof.
- The check is independent of the producer. The AI that wrote the proof is not the one that certifies it.
- The checker is current and has a track record. Versions are pinned, bugs are published, and a second implementation agrees.
- The question is closed. It has a yes or no answer, and the answer is the thing you need.
- Being wrong is cheap or reversible. A flawed result gets caught before it carries weight.
When to refuse
I would refuse, or at least hold the result back, in these cases:
| Situation | Why I would refuse | What I would ask for |
|---|---|---|
| Nobody accountable can read the statement being checked | The check could be answering a different question | A human-readable statement, signed off by a named person |
| The producer and the checker are the same system | The check is not independent | A second, separately built checker |
| The decision needs the reason, not only the answer | Regulators, courts and customers ask why | An explanation a person can give and defend |
| The result will be built on by others | Nobody can extend what nobody understands | A readable exposition, as Anthropic and Tao both ask |
| The stakes are high and the checker is untested | One undiscovered bug is enough | Independent kernels, pinned versions, a human audit |
My own framework, drawing on Hales’s guidance on statement fidelity and independent kernels.
The pattern outside mathematics is the same. AI-generated code with a formal proof of one property, an AI-prepared audit with an automated test of the controls, a model-written contract checked by a clause scanner: each carries a certificate that answers a narrow question. Ask which question, and who wrote it.
Questions for leaders
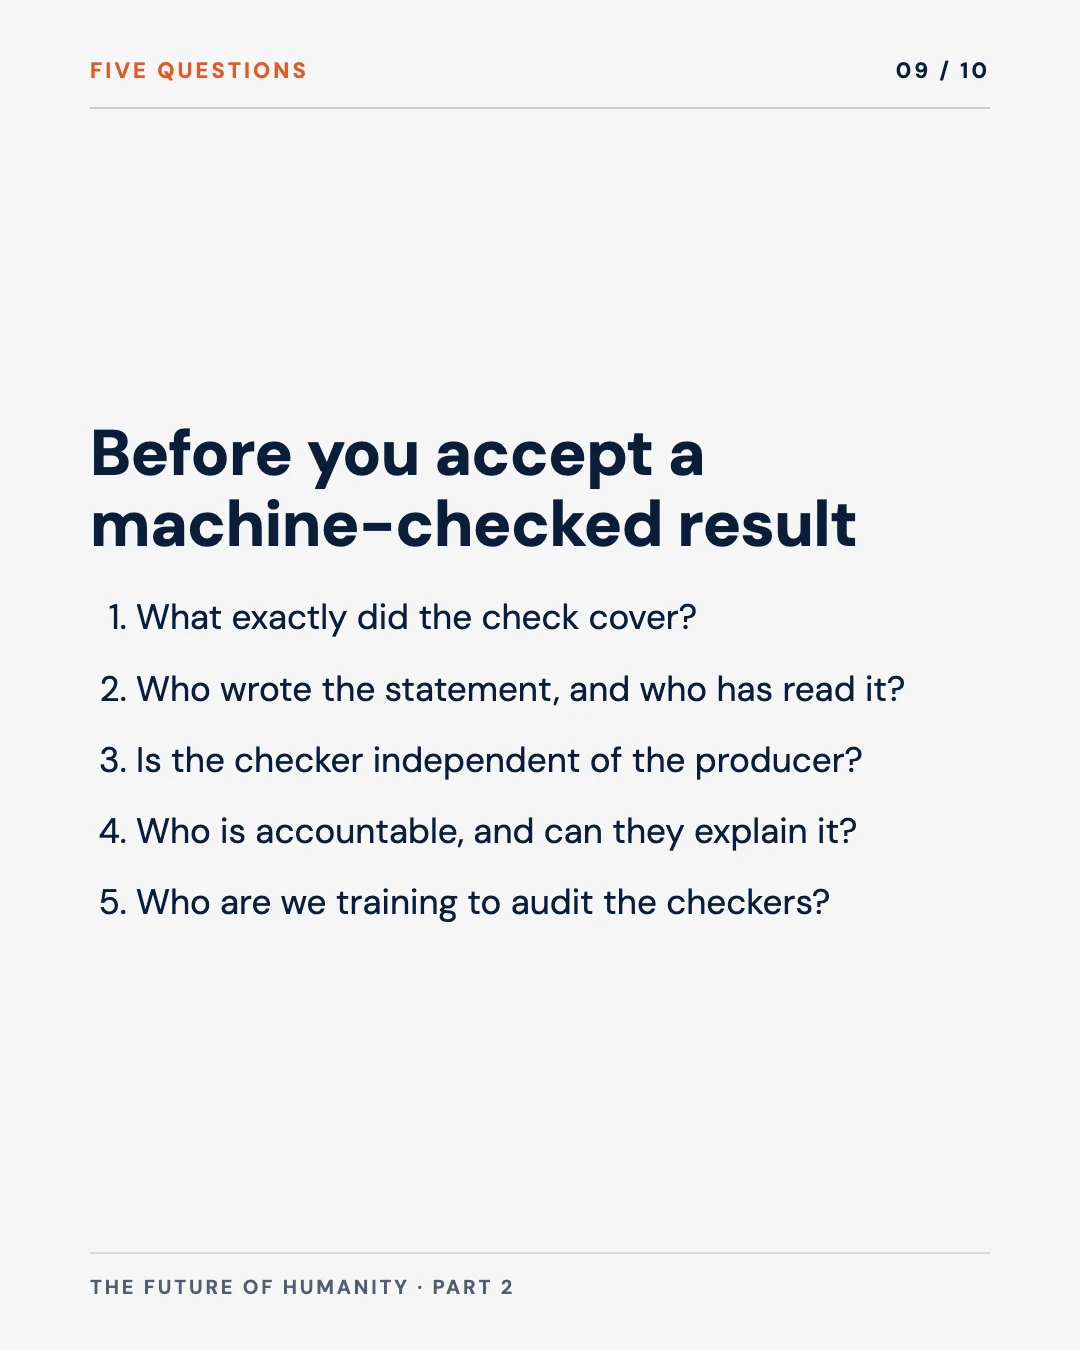
Five questions I would put to a team that accepts machine-checked work:
- For each result we accept on the strength of an automated check, what exactly did the check cover?
- Who wrote the statement the check was run against, and who has read it?
- Is the checker independent of the system that produced the work?
- Where we rely on a result nobody understands, who is accountable if it fails, and can they explain the decision to a regulator?
- Which people are we training now to read statements and audit checkers, so the skill exists in five years?
Evidence & Methodology
The Fermat’s Last Theorem figures come from Anthropic’s own account, and Kevin Buzzard’s quotes are as that account reproduces them. The Lean bug details come from Lean’s maintainers. The quotes from Hales and Tao come from their own published texts. The two lists of conditions and the table are my own.
| Claim | Source | Grade |
|---|---|---|
| Claude agents produced a Lean proof of Fermat’s Last Theorem in 11 days, about 13 million lines, over five times Mathlib, three standard axioms | Anthropic, Formalizing Fermat’s Last Theorem, 4 September 2026 | Reported, by the maker, single source |
| A comparator confirmed the checked statement matches Mathlib’s own statement of the theorem | Anthropic, same post | Reported, by the maker |
| Buzzard: “proves Fermat’s Last Theorem with no assumptions other than the axioms of mathematics” | Quoted in Anthropic’s post | Reported |
| The proof is probably much longer than necessary; failed early attempts account for about 7 per cent of non-boilerplate lines | Anthropic, same post, footnote | Reported |
| Appel and Haken’s 1976 proof reduced the four colour theorem to 1,936 configurations and needed over 1,000 hours of computing | Secondary accounts of the 1976 proof, including University of Illinois | Measured, secondary |
| A Coq proof of the four colour theorem was completed in 2005 | Gonthier’s own 2005 account and Coq documentation | Measured |
| The Collatz “disproof” exploited a kernel bug in nested inductive types; fix pushed about an hour after the report; Lean 4.32.2 released 28 July 2026 | de Moura, Postmortem for Kernel Soundness Bug 14576, 1 August 2026; Lean 4.32.2 release notes | Measured, primary |
| The exploit also passed nanoda because of a separate nanoda bug, so two bugs in two implementations were needed | de Moura, same postmortem | Measured, primary |
| ”We absolutely cannot put blind trust in systems such as Lean”; “a proof in Lean should not be accepted until a human audit is performed to ensure statement fidelity”; “Cross-checking the proof by different kernels does not remove all doubt” | Hales, guest post on Terence Tao’s blog, 9 October 2026 | Measured, primary text |
| Tao: a verified proof of a major result “that no human understands enough to explain it”; AI-polished exposition may remove natural friction | Tao, Mathematics in the Age of AI, ICM 2026 lecture slides, 24 July 2026 | Measured, primary text |
| The accept and refuse conditions and the five leader questions | My own judgement | My call |
Sources
- Anthropic. (2026, September 4). Formalizing Fermat’s Last Theorem.
- de Moura, L. (2026, August 1). Postmortem for kernel soundness bug 14576.
- Lean. (2026, July 28). Lean 4.32.2 release notes.
- Hales, T. (2026, October 9). What mathematicians should know about the Lean theorem prover: questions of reliability and AI. Guest post, What’s new, Terence Tao’s blog.
- Tao, T. (2026, July 24). Mathematics in the age of AI. Public lecture, International Congress of Mathematicians, Philadelphia.
- Gonthier, G. (2005). A computer-checked proof of the four colour theorem. Microsoft Research Cambridge.
- University of Illinois. (2009). Color controversy.
The Takeoff Nobody Noticed
The speed mismatch between what machines produce and what people can check.
What You Can Do Without AI Is What I Hire For
Why the ability to check the machine is becoming the scarce skill.
Build the Part of AI That Nobody Sees
The records, checks and controls that let people stand behind what AI produces.
Part 3 looks at agent swarms and the closing loop: what changes when AI helps build the next AI, and the human step shrinks. If your board is deciding which AI results it will accept without understanding them, that is a conversation my executive programme is built for.
Cite or quote this article
Was this useful?