
Listen to this article
Jump to a section
In this article
Executive Summary
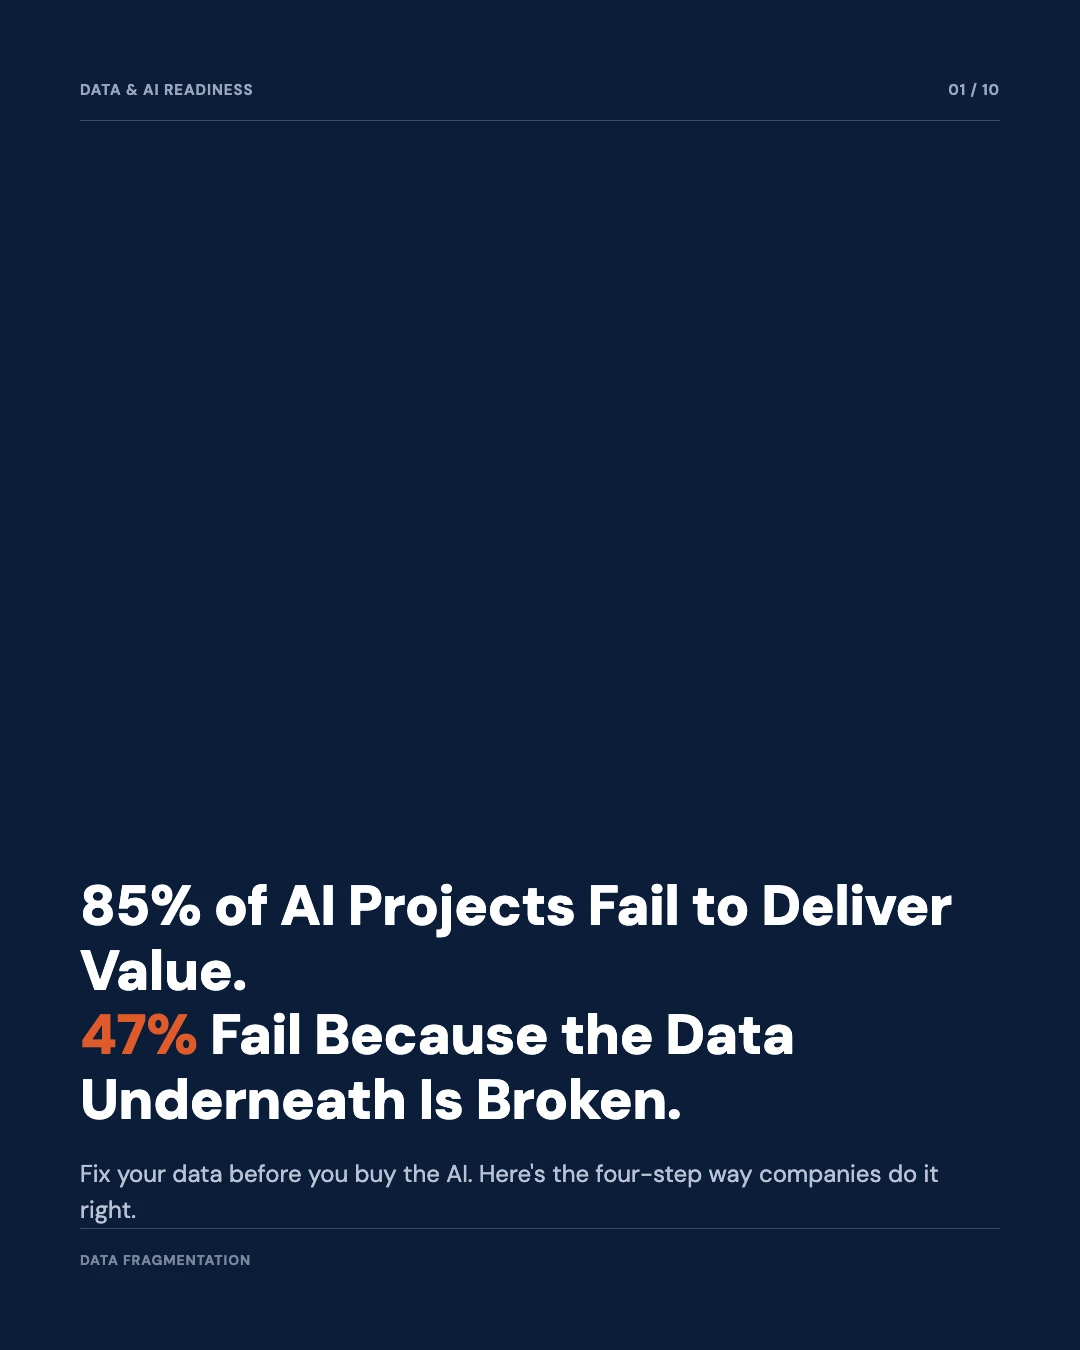
Many companies buy expensive AI models before they fix their data. This is a mistake. AI needs clean, connected data to work well. Without it, AI gives wrong answers, makes things up, or even leaks private information. Gartner forecasts 60% of AI projects will be abandoned through 2026 specifically for lack of AI-ready data.
60%
of AI projects forecast to be abandoned through 2026 for lack of AI-ready data (Gartner)
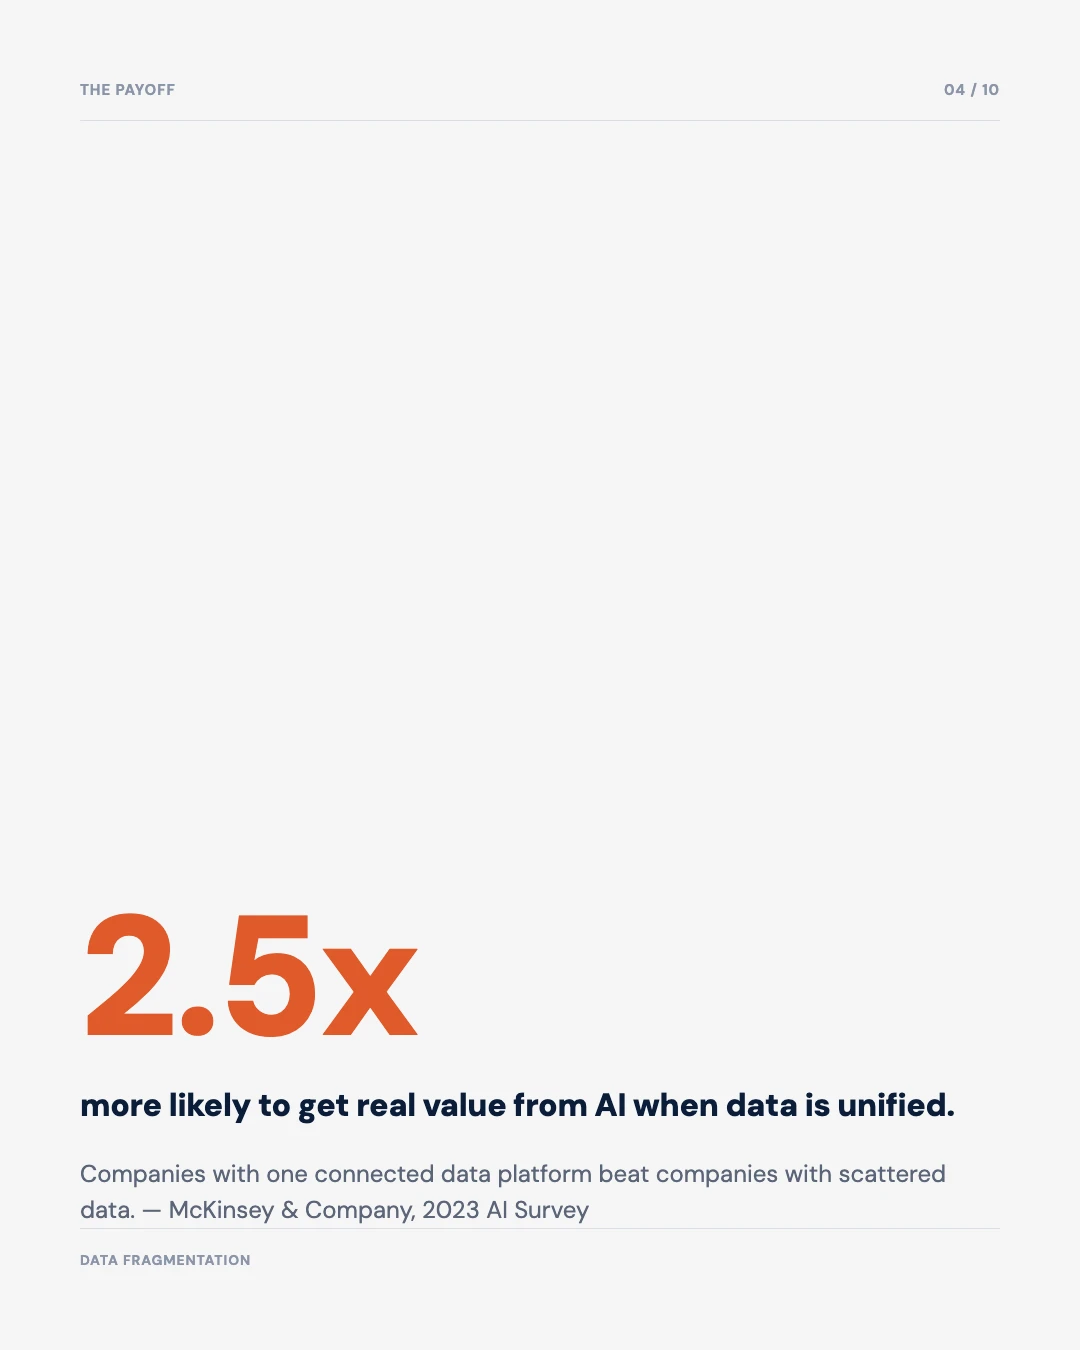
2.5x
more likely to get real value from AI when a company’s data is unified instead of scattered
$4.45M
average yearly cost of poor data rules and hidden data silos, in security risk and wasted work
Core conclusions
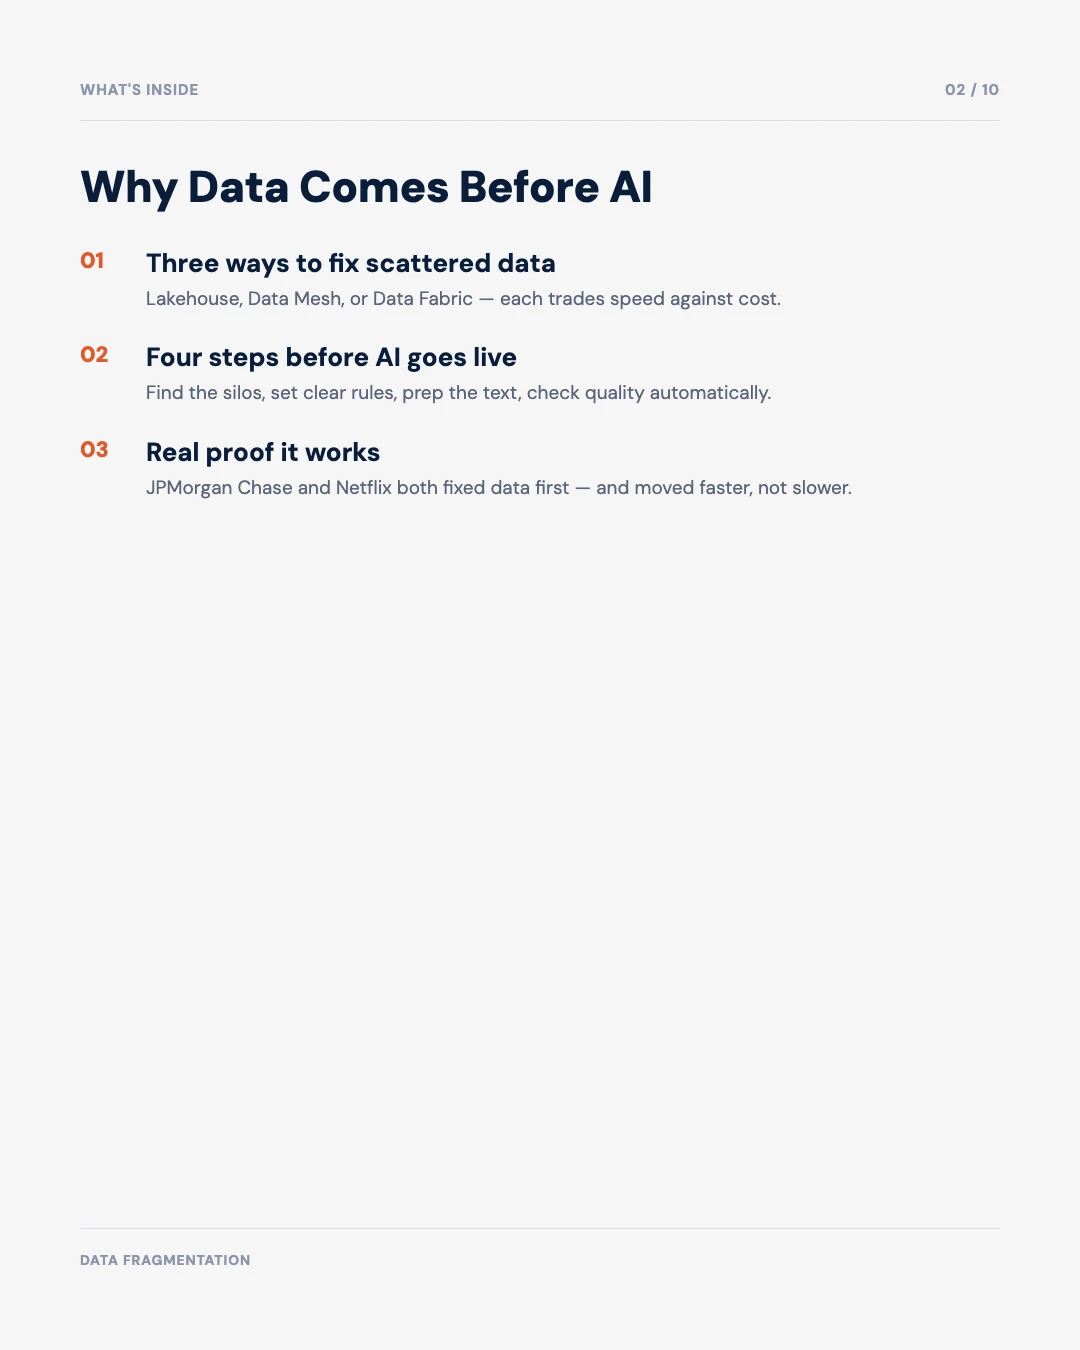
- There are three main ways to fix scattered data before adding AI: a Centralised Lakehouse, a Data Mesh, or a Data Fabric. Each one trades speed against cost and complexity, and picking the wrong one wastes months.
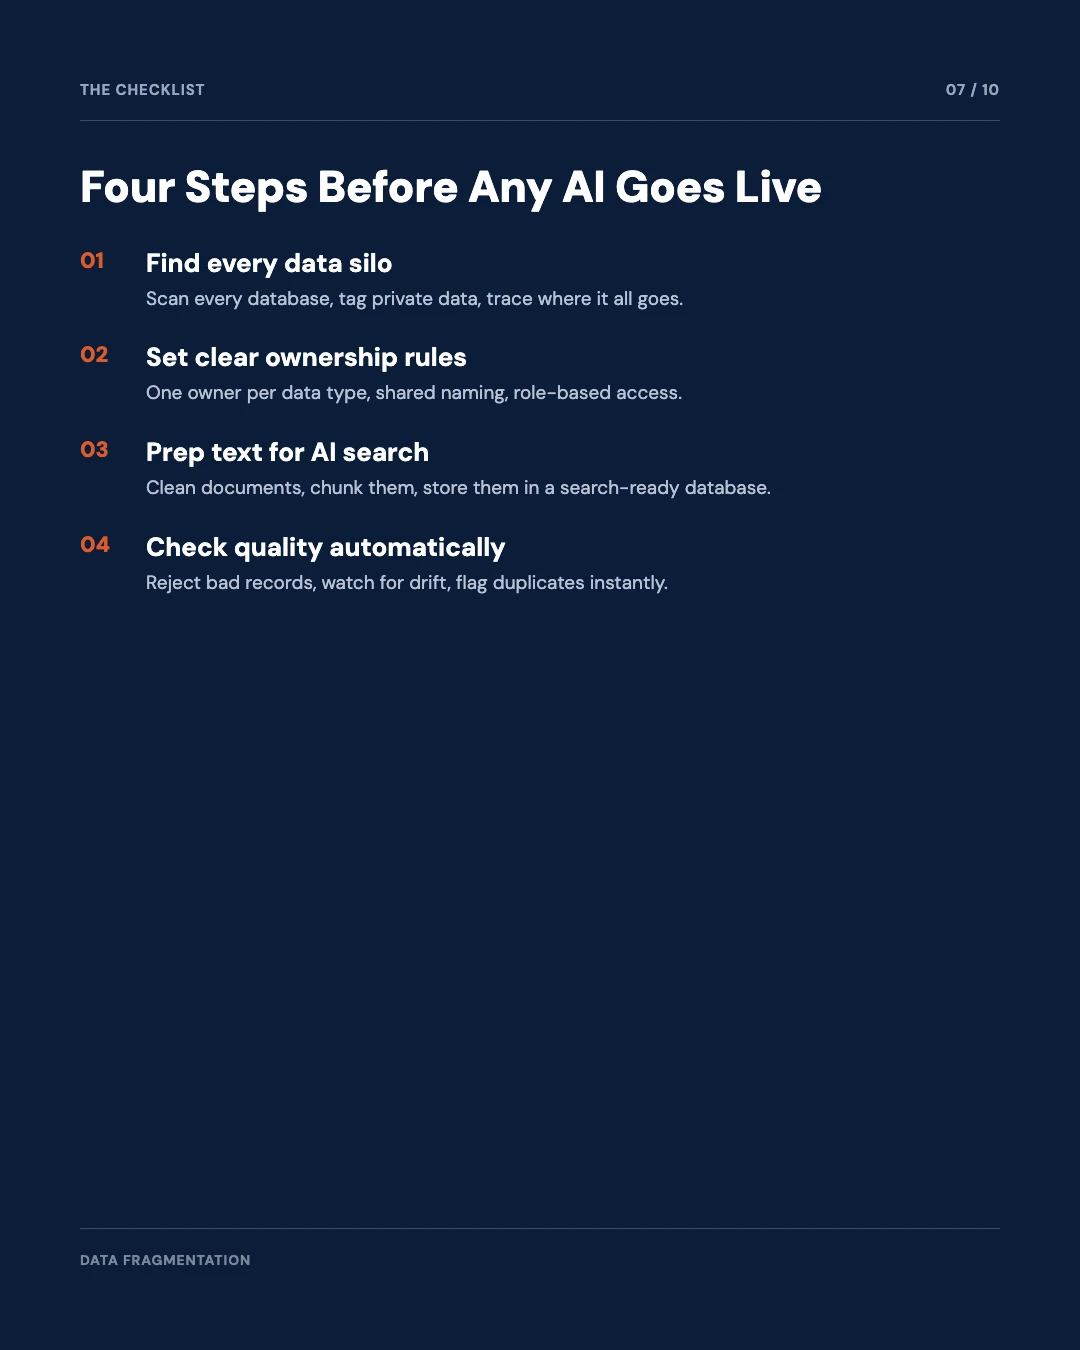
- Four steps come before any AI model goes live: find every data silo, set clear rules for who owns what data, turn messy documents into clean AI-ready chunks, and run automatic checks that catch bad data before it reaches the AI.
- This isn’t theory. JPMorgan Chase and Netflix both restructured their data first, before scaling AI, and both point the same way: companies that fix data before buying AI move faster.
Fixing your data before AI, in ten slides
Save it, share it, or send it to whoever is about to sign an AI contract.
Why buying AI first is a mistake
Many company leaders buy powerful AI models before they fix the data underneath them. This feels like progress. It is the opposite. An AI model is only as good as the data it can see. If that data is locked away in old, disconnected systems, the AI cannot find it, cannot understand it, and cannot use it safely.
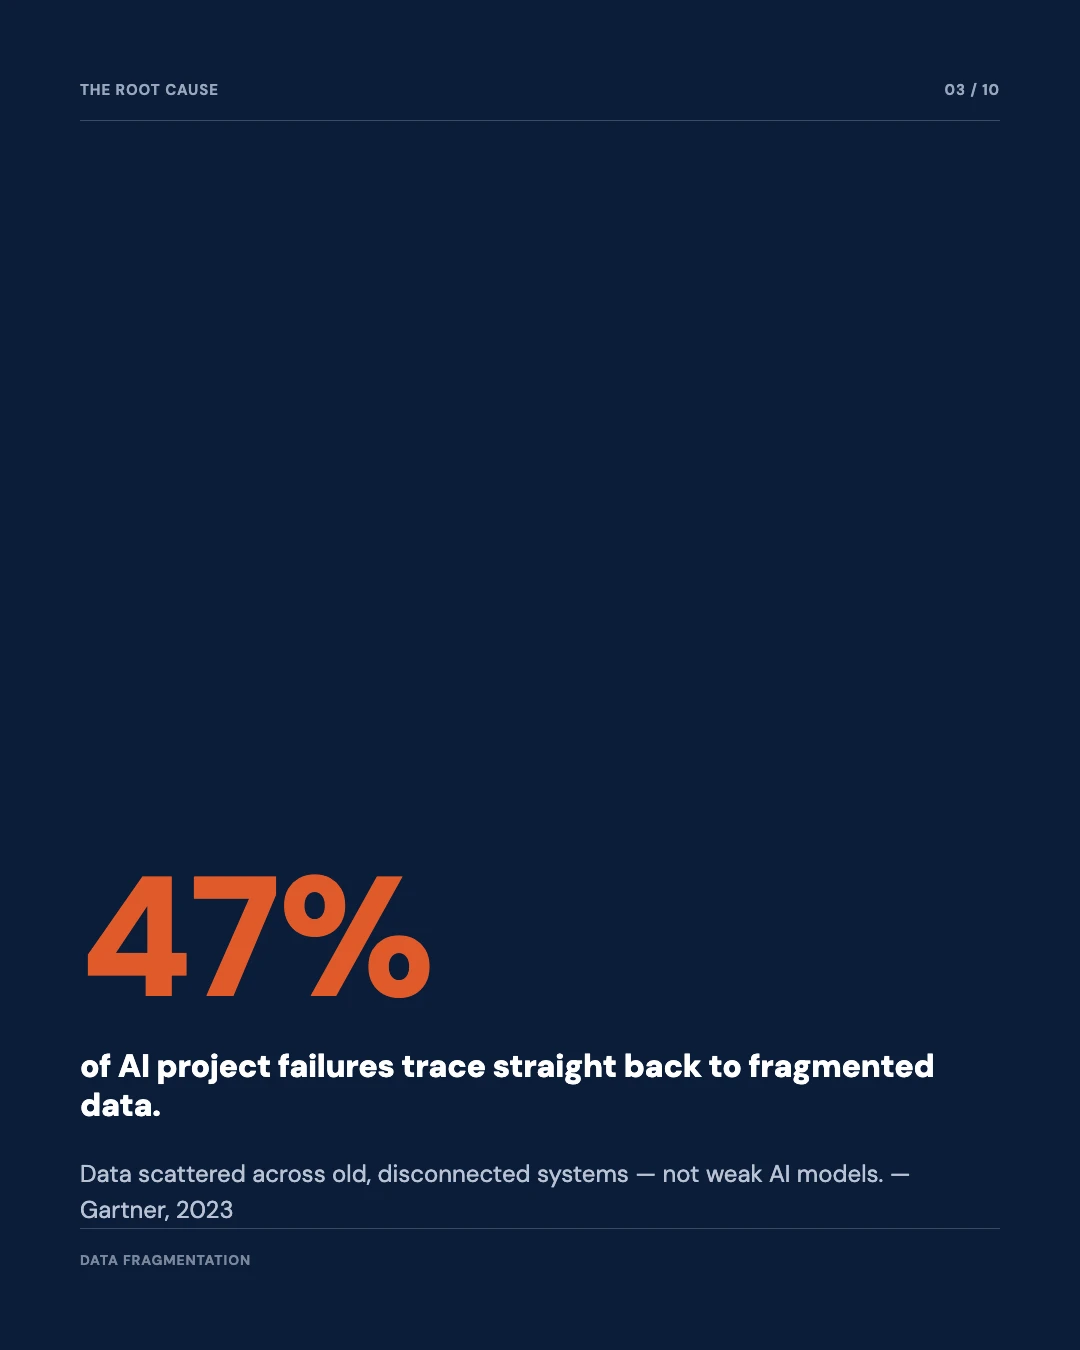
Gartner forecasts that 60% of AI projects will be abandoned through 2026, and data fragmentation, meaning it is scattered across old databases that don’t talk to each other, is a leading reason why. When AI cannot see clean, connected data, it does one of three bad things. It gives wrong answers. It makes up facts that sound true but aren’t, a problem called hallucination. Or it accidentally shows sensitive customer information to people who should never see it.
The data backs this up from more than one angle. McKinsey & Company’s 2023 AI survey found that companies with unified data platforms, meaning all their data lives in one connected system, were far more likely to get real economic value from AI than companies with scattered data, the 2.5x figure shown above. IBM’s 2023 Cost of Data Breach Report put a number on the downside of getting this wrong: poor data rules and hidden data silos cost companies an average of $4.45 million every year, through security risks and wasted work, the same figure shown above.
Companies that build a shared data layer and automatic data checks before they turn on AI models cut their data preparation time in half within six months, compared to companies still relying on slow, manual data cleanup.
| Metric | Value | Source |
|---|---|---|
| AI projects forecast to be abandoned through 2026 for lack of AI-ready data | 60% | Gartner, 2025 |
| More likely to generate economic value from AI with unified data | 2.5x | McKinsey & Company, 2023 AI Survey |
| Average yearly cost of poor data governance and unmapped silos | $4.45 million | IBM, 2023 Cost of Data Breach Report |
Three different studies, one same message: AI does not fail because the model is weak. It fails because the data underneath it was never made ready.
Three ways to fix scattered data
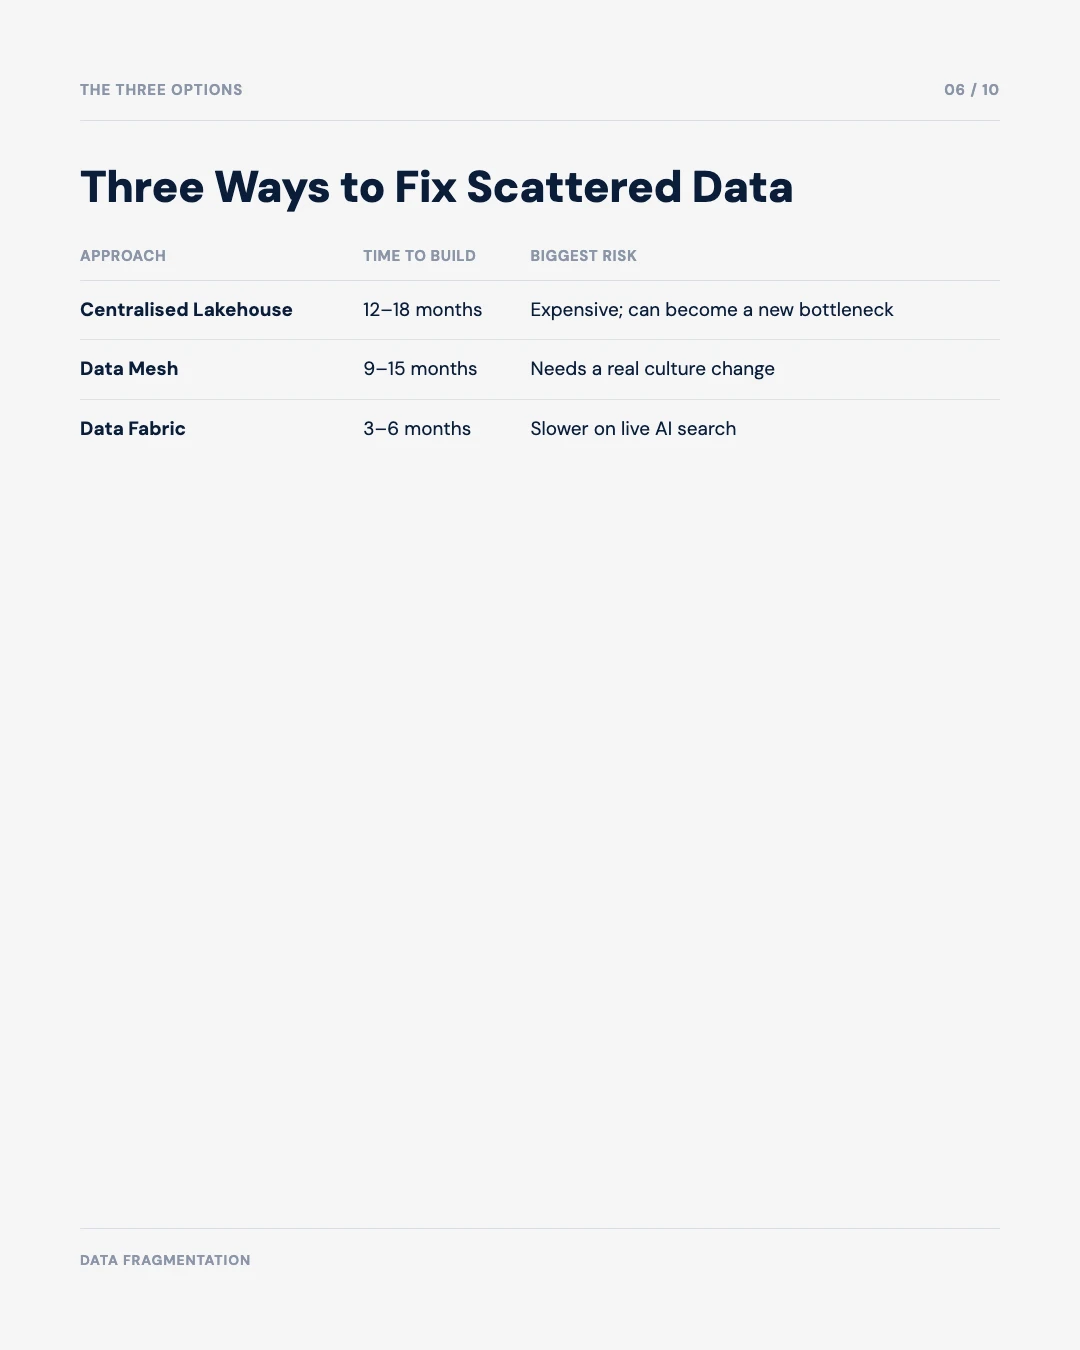
Once a company decides to fix its data before turning on AI, it has three main paths to choose from. Each one is a real technical approach, and each one trades speed against cost and complexity. Picking the wrong one for your situation can waste months of work.
| Approach | How it works | Time to build | Best thing about it | Biggest risk |
|---|---|---|---|---|
| Centralised Lakehouse (e.g. Snowflake, Databricks) | Moves all raw and structured data into one single cloud storage system | 12 to 18 months | Very fast for big analytical questions; one place to control everything | Expensive to build; can turn into a new giant bottleneck |
| Data Mesh (Federated Ownership) | Treats data like a product; each business team manages its own data | 9 to 15 months | Scales well; the people closest to the data keep it accurate | Needs a change in company culture; harder to govern across many teams |
| Data Fabric / Virtualisation (Unified Metadata Layer) | Connects existing systems with a virtual catalog, without moving the raw data at all | 3 to 6 months | Fastest to set up; barely disturbs old systems | Can be slower when AI needs to search data live |
There is no single “best” option. A Data Fabric is fastest to deploy but can slow down live AI searches. A Lakehouse gives the strongest analytics but costs the most and takes the longest. A Data Mesh scales well but needs real buy-in from every team.
Four steps to get data ready for AI
Whichever path a company picks, four steps have to happen before an AI model can be trusted with real company data.
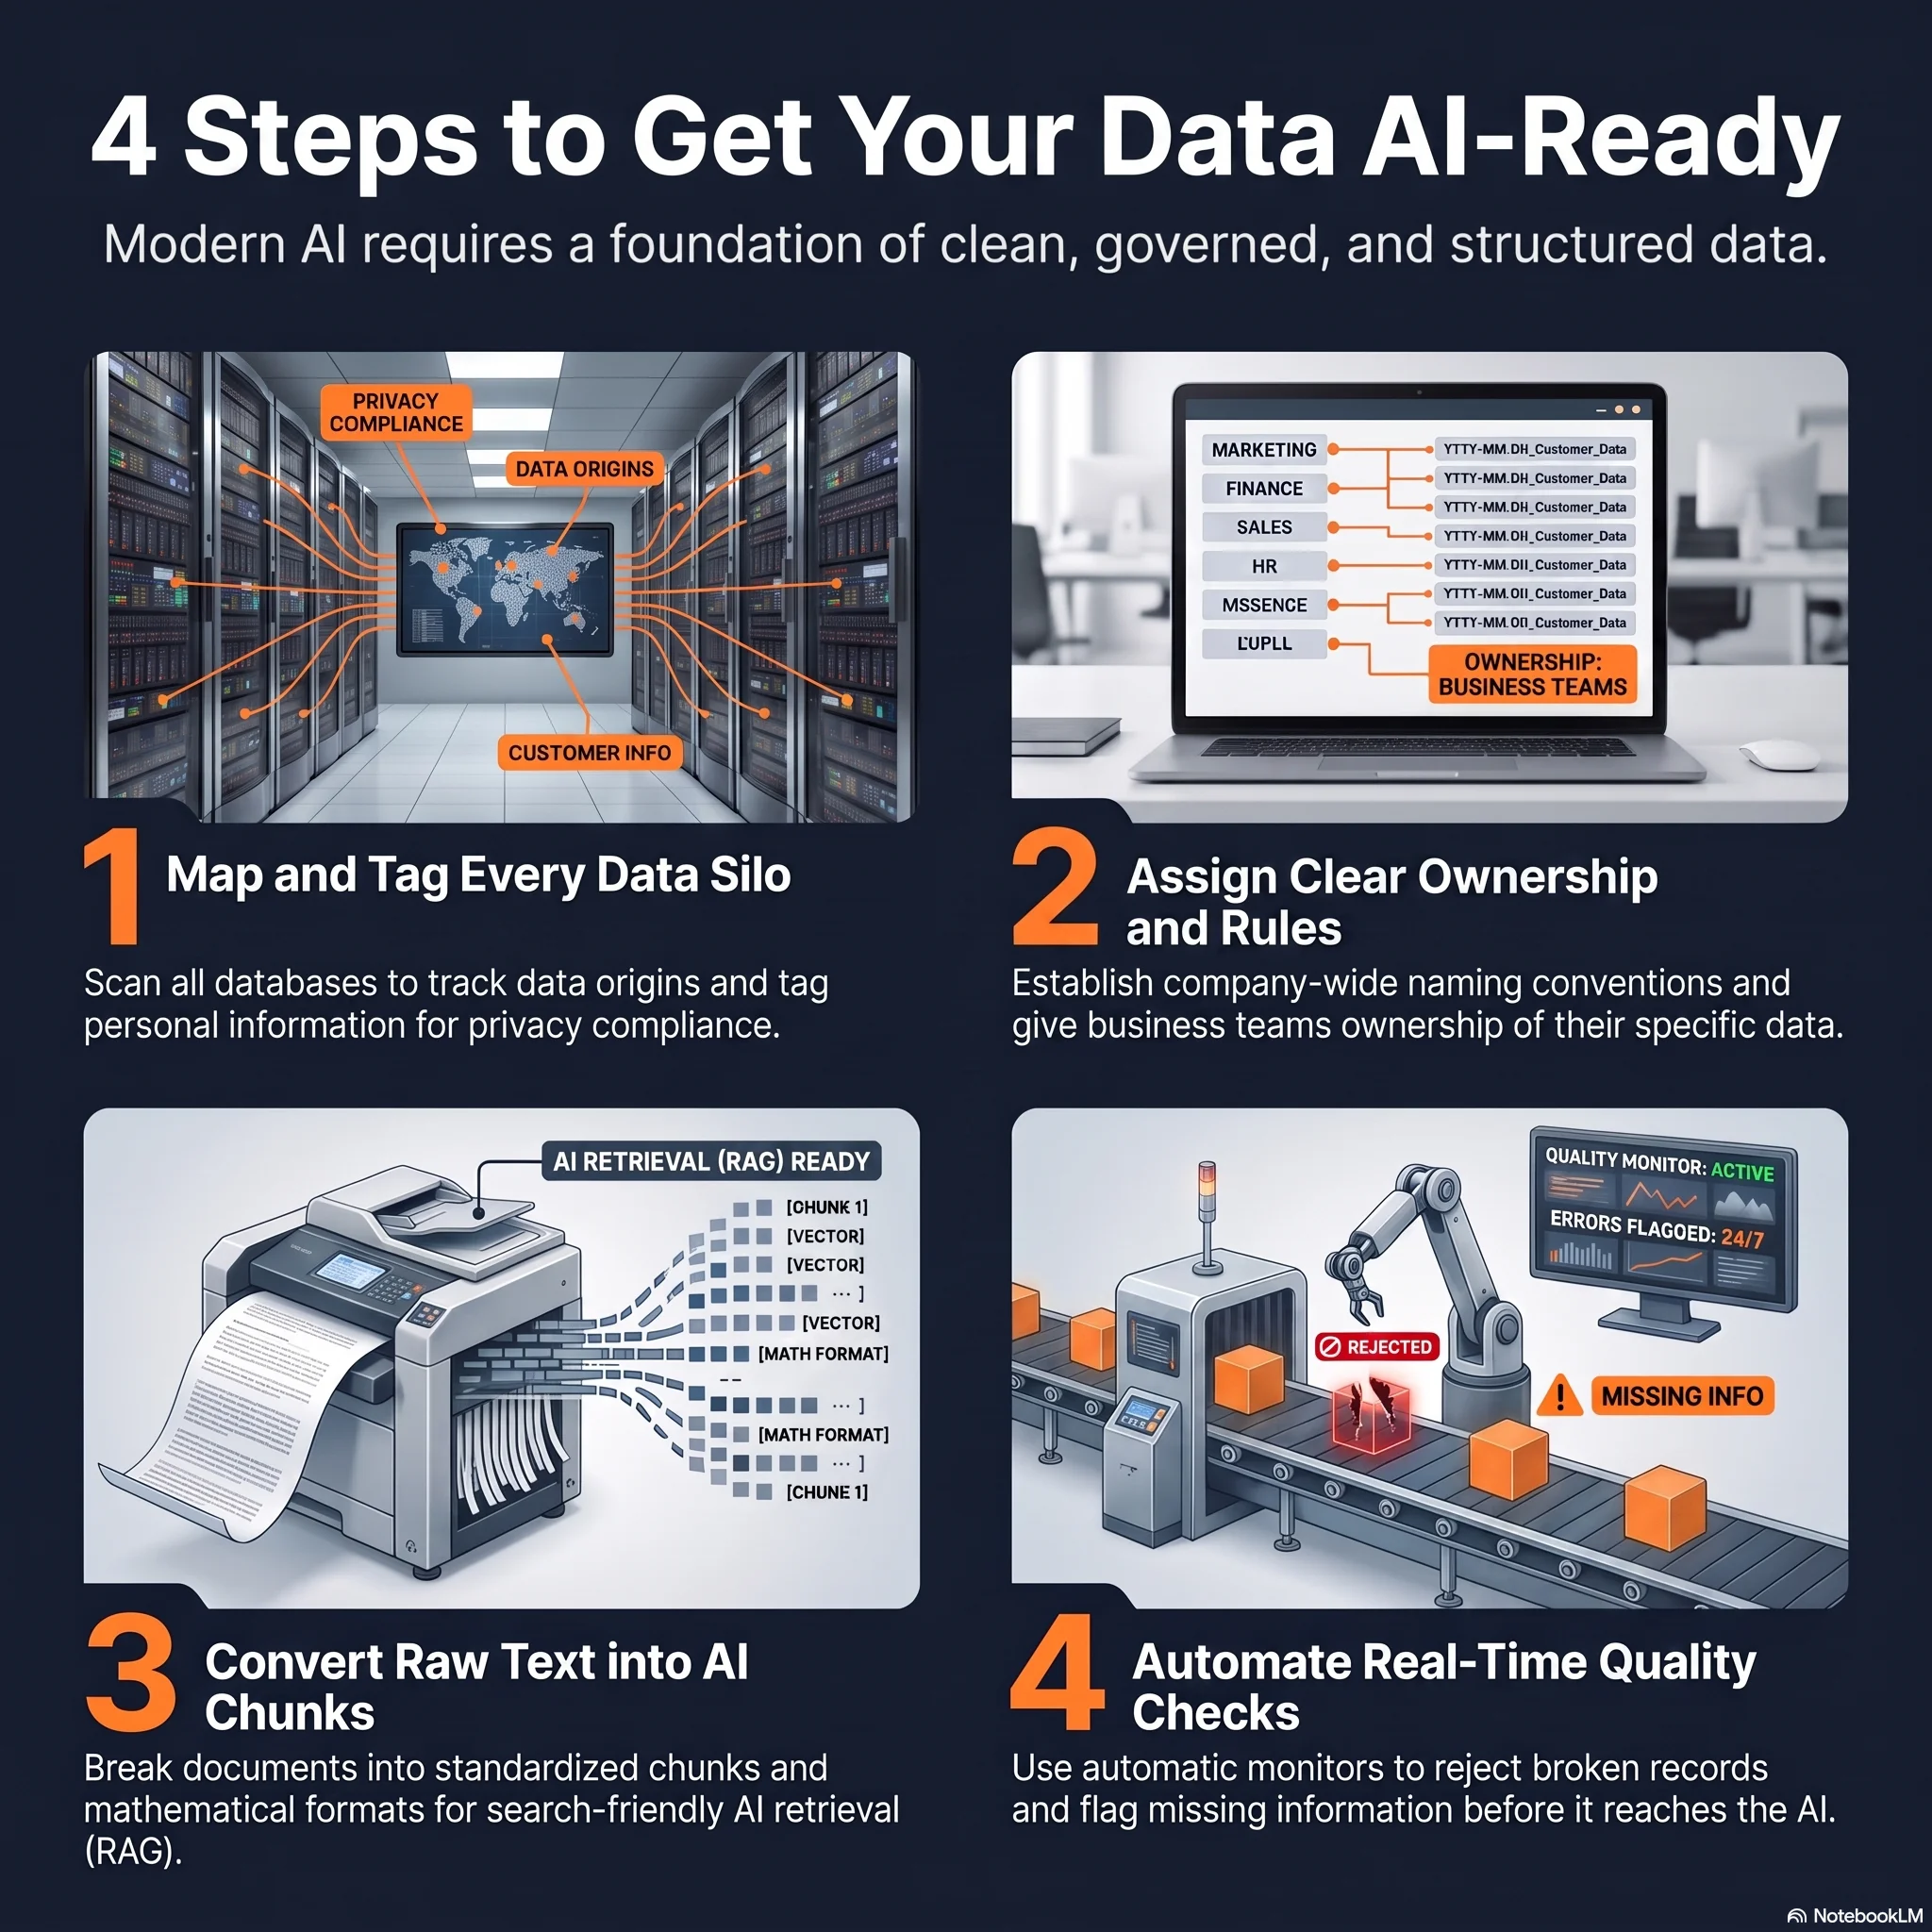
Step 1: Find every data silo. A company cannot fix data it cannot see. Teams need to scan every database, every sales system, and every customer records system. This means automatically scanning for data tables nobody remembers exist, tagging any personal information so it follows privacy laws like GDPR, and tracking exactly where every piece of data came from and where it goes.
Step 2: Set clear rules for who owns what. When one central team controls all data decisions, approvals slow to a crawl. It works better to give each business team ownership of its own data, while everyone follows the same company-wide rules. That means naming a clear owner for every type of data, controlling who can access what through role-based permissions, and using the same naming rules and date formats company-wide, so “customer_id” doesn’t mean five different things in five different systems.
Step 3: Turn messy text into clean, AI-ready pieces. Modern AI tools that search company knowledge, a method called Retrieval-Augmented Generation or RAG, need documents like PDFs, emails, and support tickets converted into a mathematical format the AI can search. This means cleaning raw text into a simple, consistent format, breaking long documents into standard-sized chunks (around 512 words each, with a small overlap between chunks so no idea gets cut in half), and storing those chunks in a special search-friendly database built for this purpose.
Step 4: Check data quality automatically, all the time. Manually checking data by hand cannot keep up with AI running in real time. Companies need automatic checks that reject broken or incomplete records before they ever reach the AI, that watch for data slowly drifting out of date, and that instantly flag duplicate records or missing information.
Real companies that did this
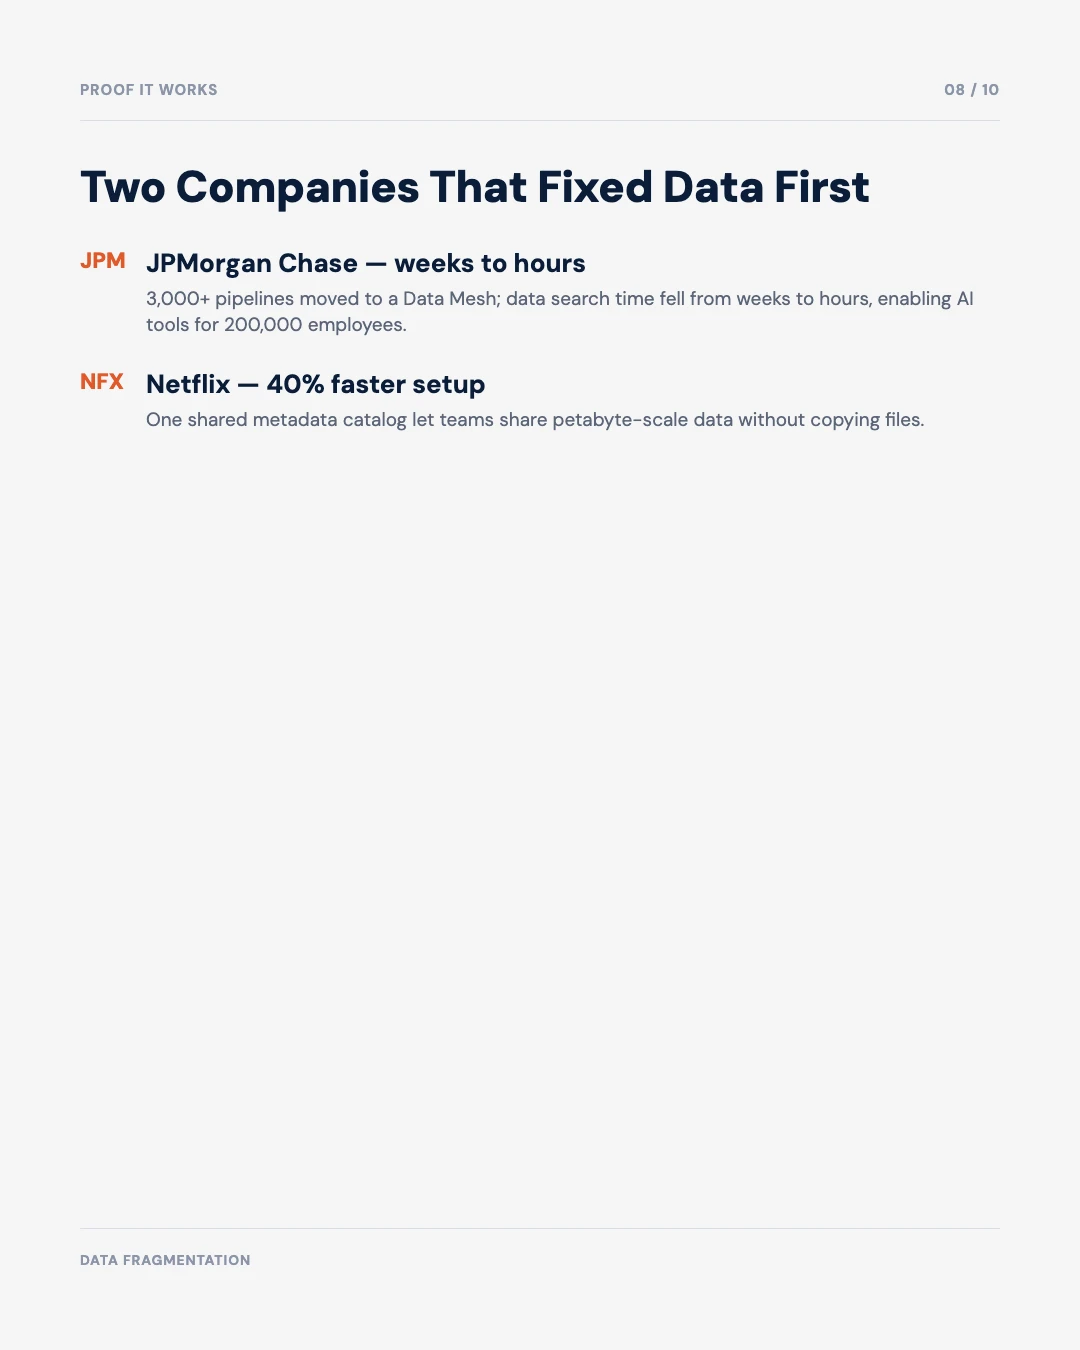
JPMorgan Chase (Data Mesh migration). JPMorgan Chase moved to a Data Mesh architecture, giving individual business teams ownership of their own data while keeping shared company-wide rules, specifically to make data easier for teams to discover and trust. JPMorgan and AWS have documented the architecture publicly; neither has published a specific before-and-after time or headcount figure, so I have not invented one here.
Netflix (metadata catalog). Netflix faced fragmented data at a massive scale, more information than almost any other company handles. It built a shared metadata catalog so different engineering teams could find and use the same data without copying files or locking each other out, an approach Netflix has documented on its own engineering blog. Netflix has not published a specific percentage improvement tied to this change, so this post does not repeat one.
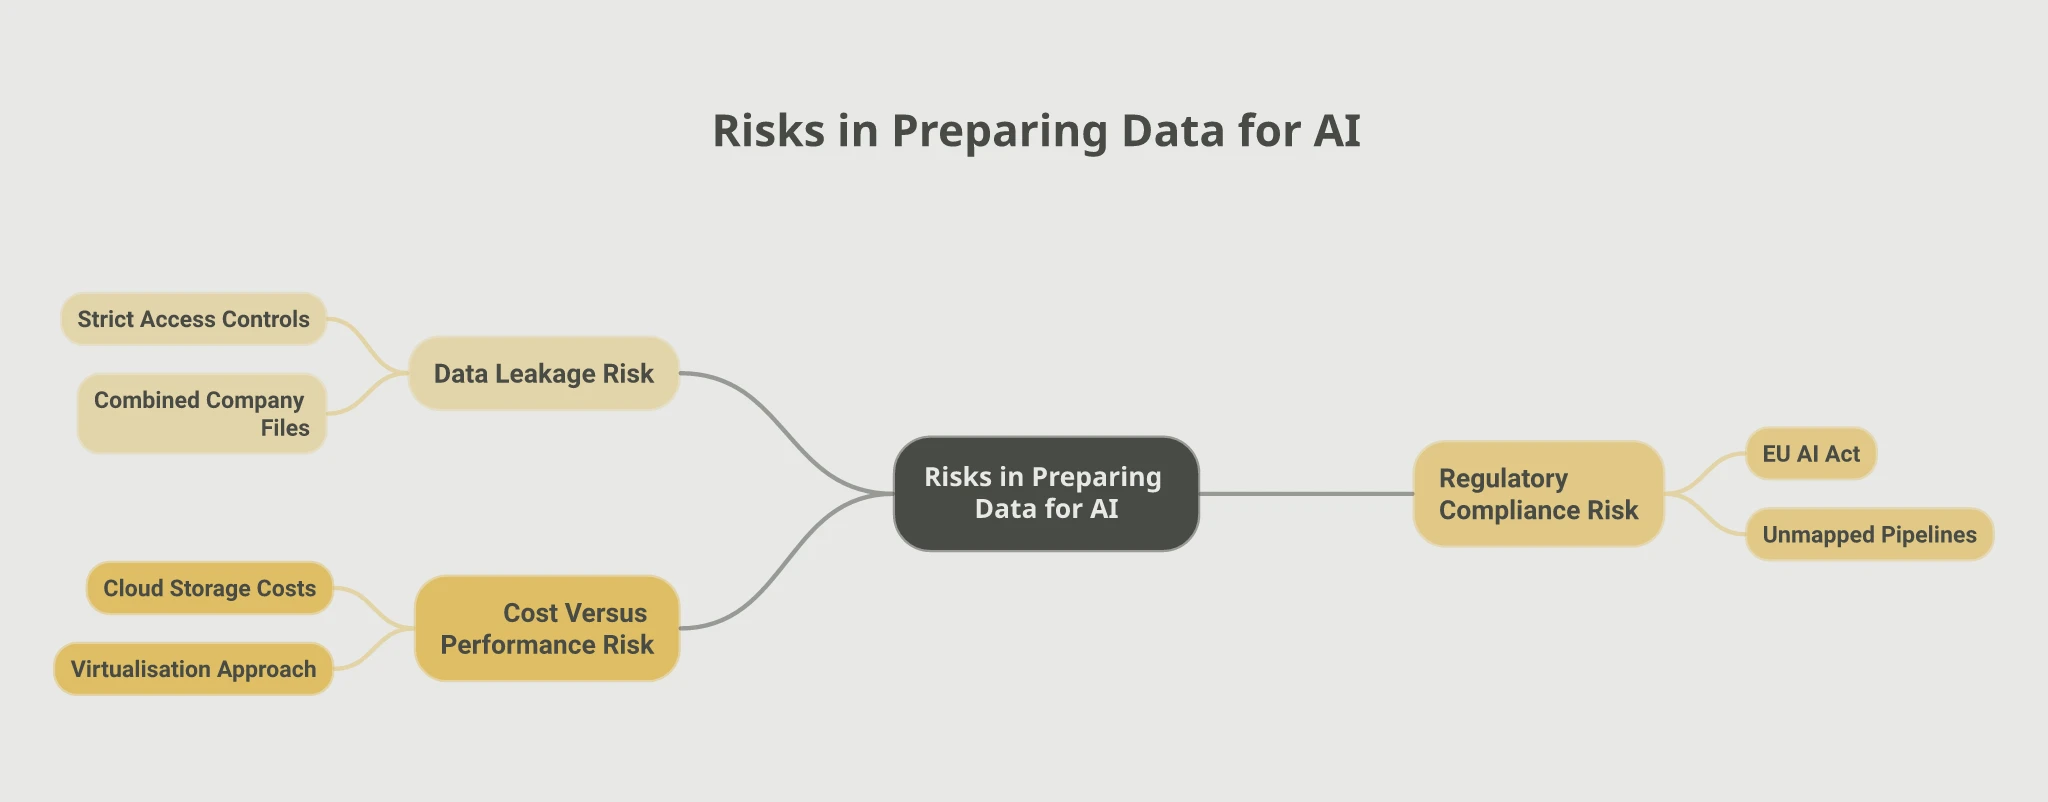
Three risks to watch for
Getting data ready for AI isn’t just a technical project. It also carries real business risk if done carelessly.
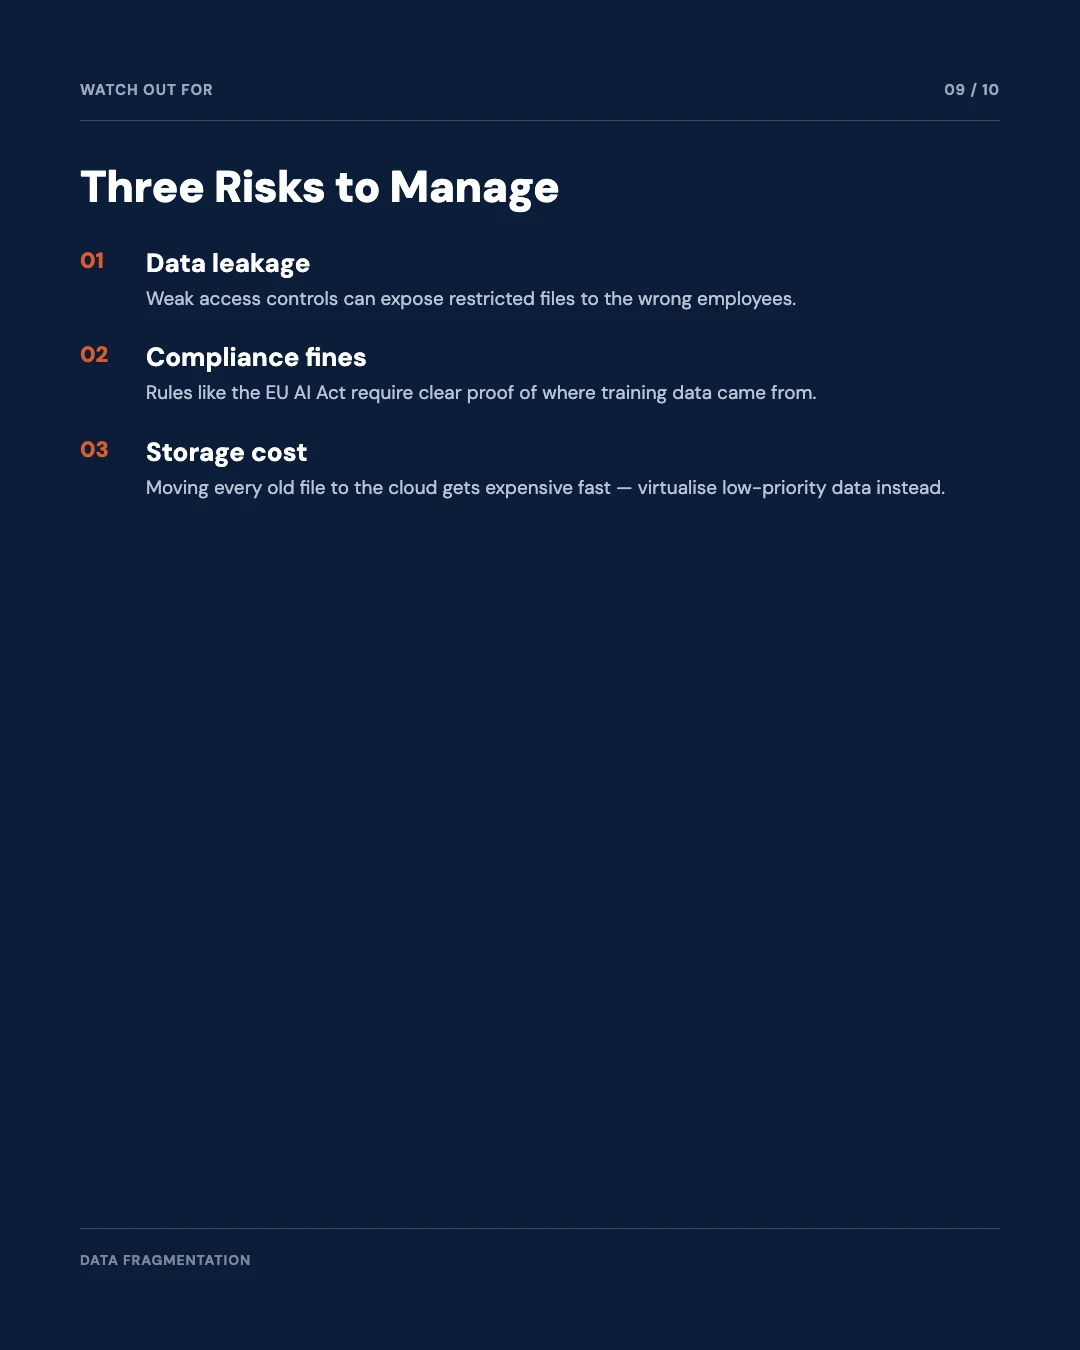
- Data leakage risk. Without strict access controls, training an internal AI model on combined company files can let low-level employees accidentally see restricted information, like executive pay or confidential strategy documents. This risk deserves its own deep dive: see The Data Leakage Risk Hiding Inside Your Fine-Tuned AI Model.
- Regulatory compliance risk. Rules like the European Union AI Act require companies to clearly document where their data came from and how their AI was trained. Data pipelines nobody has mapped out invite real fines.
- Cost versus performance risk. Moving every piece of old company data into cloud storage creates high storage and data-transfer costs. It’s smarter to use a lighter virtualisation approach for old, low-priority data that rarely gets used.
A simple six-month plan
| Phase | Timeline | What gets delivered | How you know it worked |
|---|---|---|---|
| Phase 1: Discovery & Audit | Months 1–2 | Full metadata catalog; personal-data scanning; complete list of data silos | 100% of critical operational databases mapped |
| Phase 2: Governance & Cleaning | Months 3–4 | Clear data ownership rules; standard formats; automatic quality checks | Data defect rate drops below 2% |
| Phase 3: AI Vector Integration | Months 5–6 | Search-ready database set up; RAG system connected; live pilot test running | AI search response time under 200 milliseconds |
Each phase depends on the one before it. Skipping discovery to rush into AI search just means the AI confidently retrieves data nobody checked for accuracy.
Fix the foundation, then build
None of this means a company should be afraid of AI. It means the order of operations matters. Buying a powerful AI model before fixing scattered, disconnected data is like installing a smart thermostat in a house with no wiring: the technology is good, but it has nothing solid to connect to. Fixing data first is not the slow path. It is the only path that reaches the destination, and JPMorgan and Netflix both proved that fixing data first gets a company to real AI results faster.
I’ve written more on what a clean data pipeline needs to include in Stop Tuning Prompts, Start Cleaning Data, and on the full technical setup for search-ready AI systems in How to Build Governed RAG 2.0 Systems.
Evidence & Methodology
The headline number up top now traces to one specific, named Gartner forecast rather than a pairing of figures I could not verify. Here is what holds up under a link.
| Claim | Source | Grade |
|---|---|---|
| 60% of AI projects will be abandoned through 2026 for lack of AI-ready data | Gartner, 2025, linked below | Forecast |
| Companies with unified data are 2.5x more likely to get real value from AI | McKinsey, 2023 AI Survey, cited below | Measured |
| Poor data governance and unmapped silos cost an average of $4.45 million a year | IBM, 2023 Cost of Data Breach Report, cited below | Measured |
| JPMorgan moved to a Data Mesh, Netflix built a shared metadata catalog, both to fix fragmented data before scaling AI | Both companies have documented the architecture publicly; neither publishes a specific before-and-after metric, so this post does not repeat one | Vendor-disclosed, no figure |
Sources
- Gartner. (2025). Lack of AI-ready data puts AI projects at risk.
- McKinsey & Company. (2023). 2023 AI survey.
- IBM. (2023). 2023 cost of data breach report.
- JPMorgan Chase. Data Mesh migration, as described in JPMorgan Chase’s AWS case study on its data mesh architecture.
- Netflix Engineering. Metadata catalog case study.
- European Union. (2024). Regulation (EU) 2024/1689 (EU AI Act).
Free tool
AI Readiness Self-Assessment
Scores how ready your company’s data is before you spend on AI, across the same fragmentation risk behind Gartner’s 60% abandonment forecast.
Free tool
Data Architecture Decision Tool
Seven questions in, a Lakehouse, Data Mesh, or Data Fabric recommendation out, so you can pick between the three paths above without guessing.
The AI Governance & ROI Executive Programme walks your leadership team through fixing the data foundation first, with a scored starting point and a step-by-step plan as the result. Details are on the workshops page.
Was this useful?