
Listen to this article
Jump to a section
In this article
Executive Summary
A working proof of concept is not evidence of production readiness. AI systems fail silently, so scaling them into critical infrastructure requires a governance framework built for probabilistic, not deterministic, risk.
Core conclusions
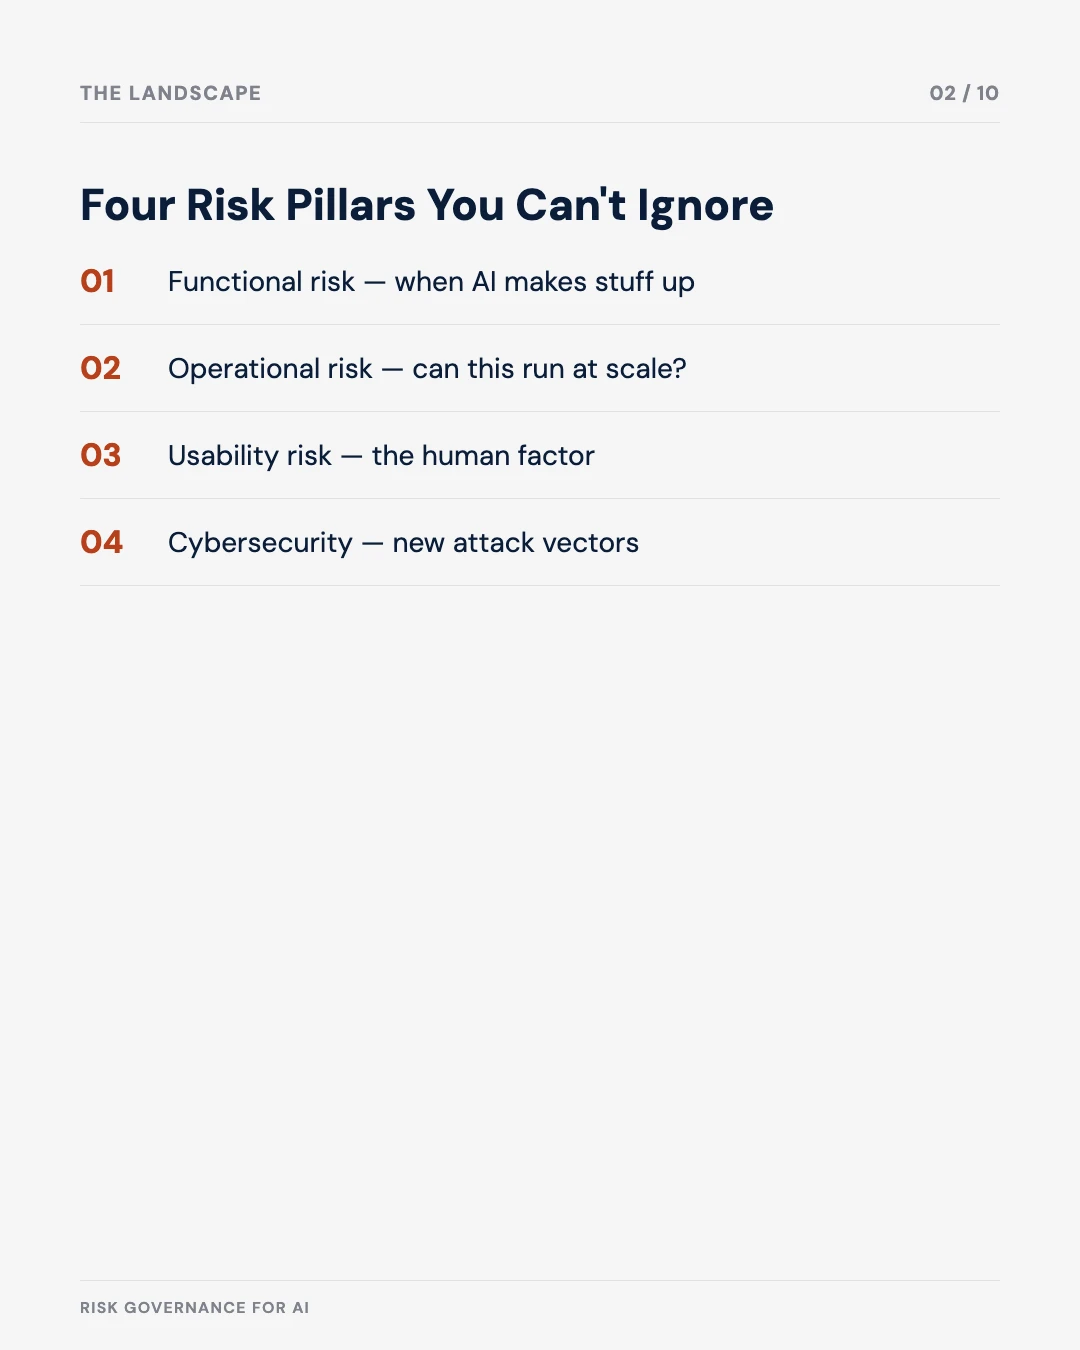
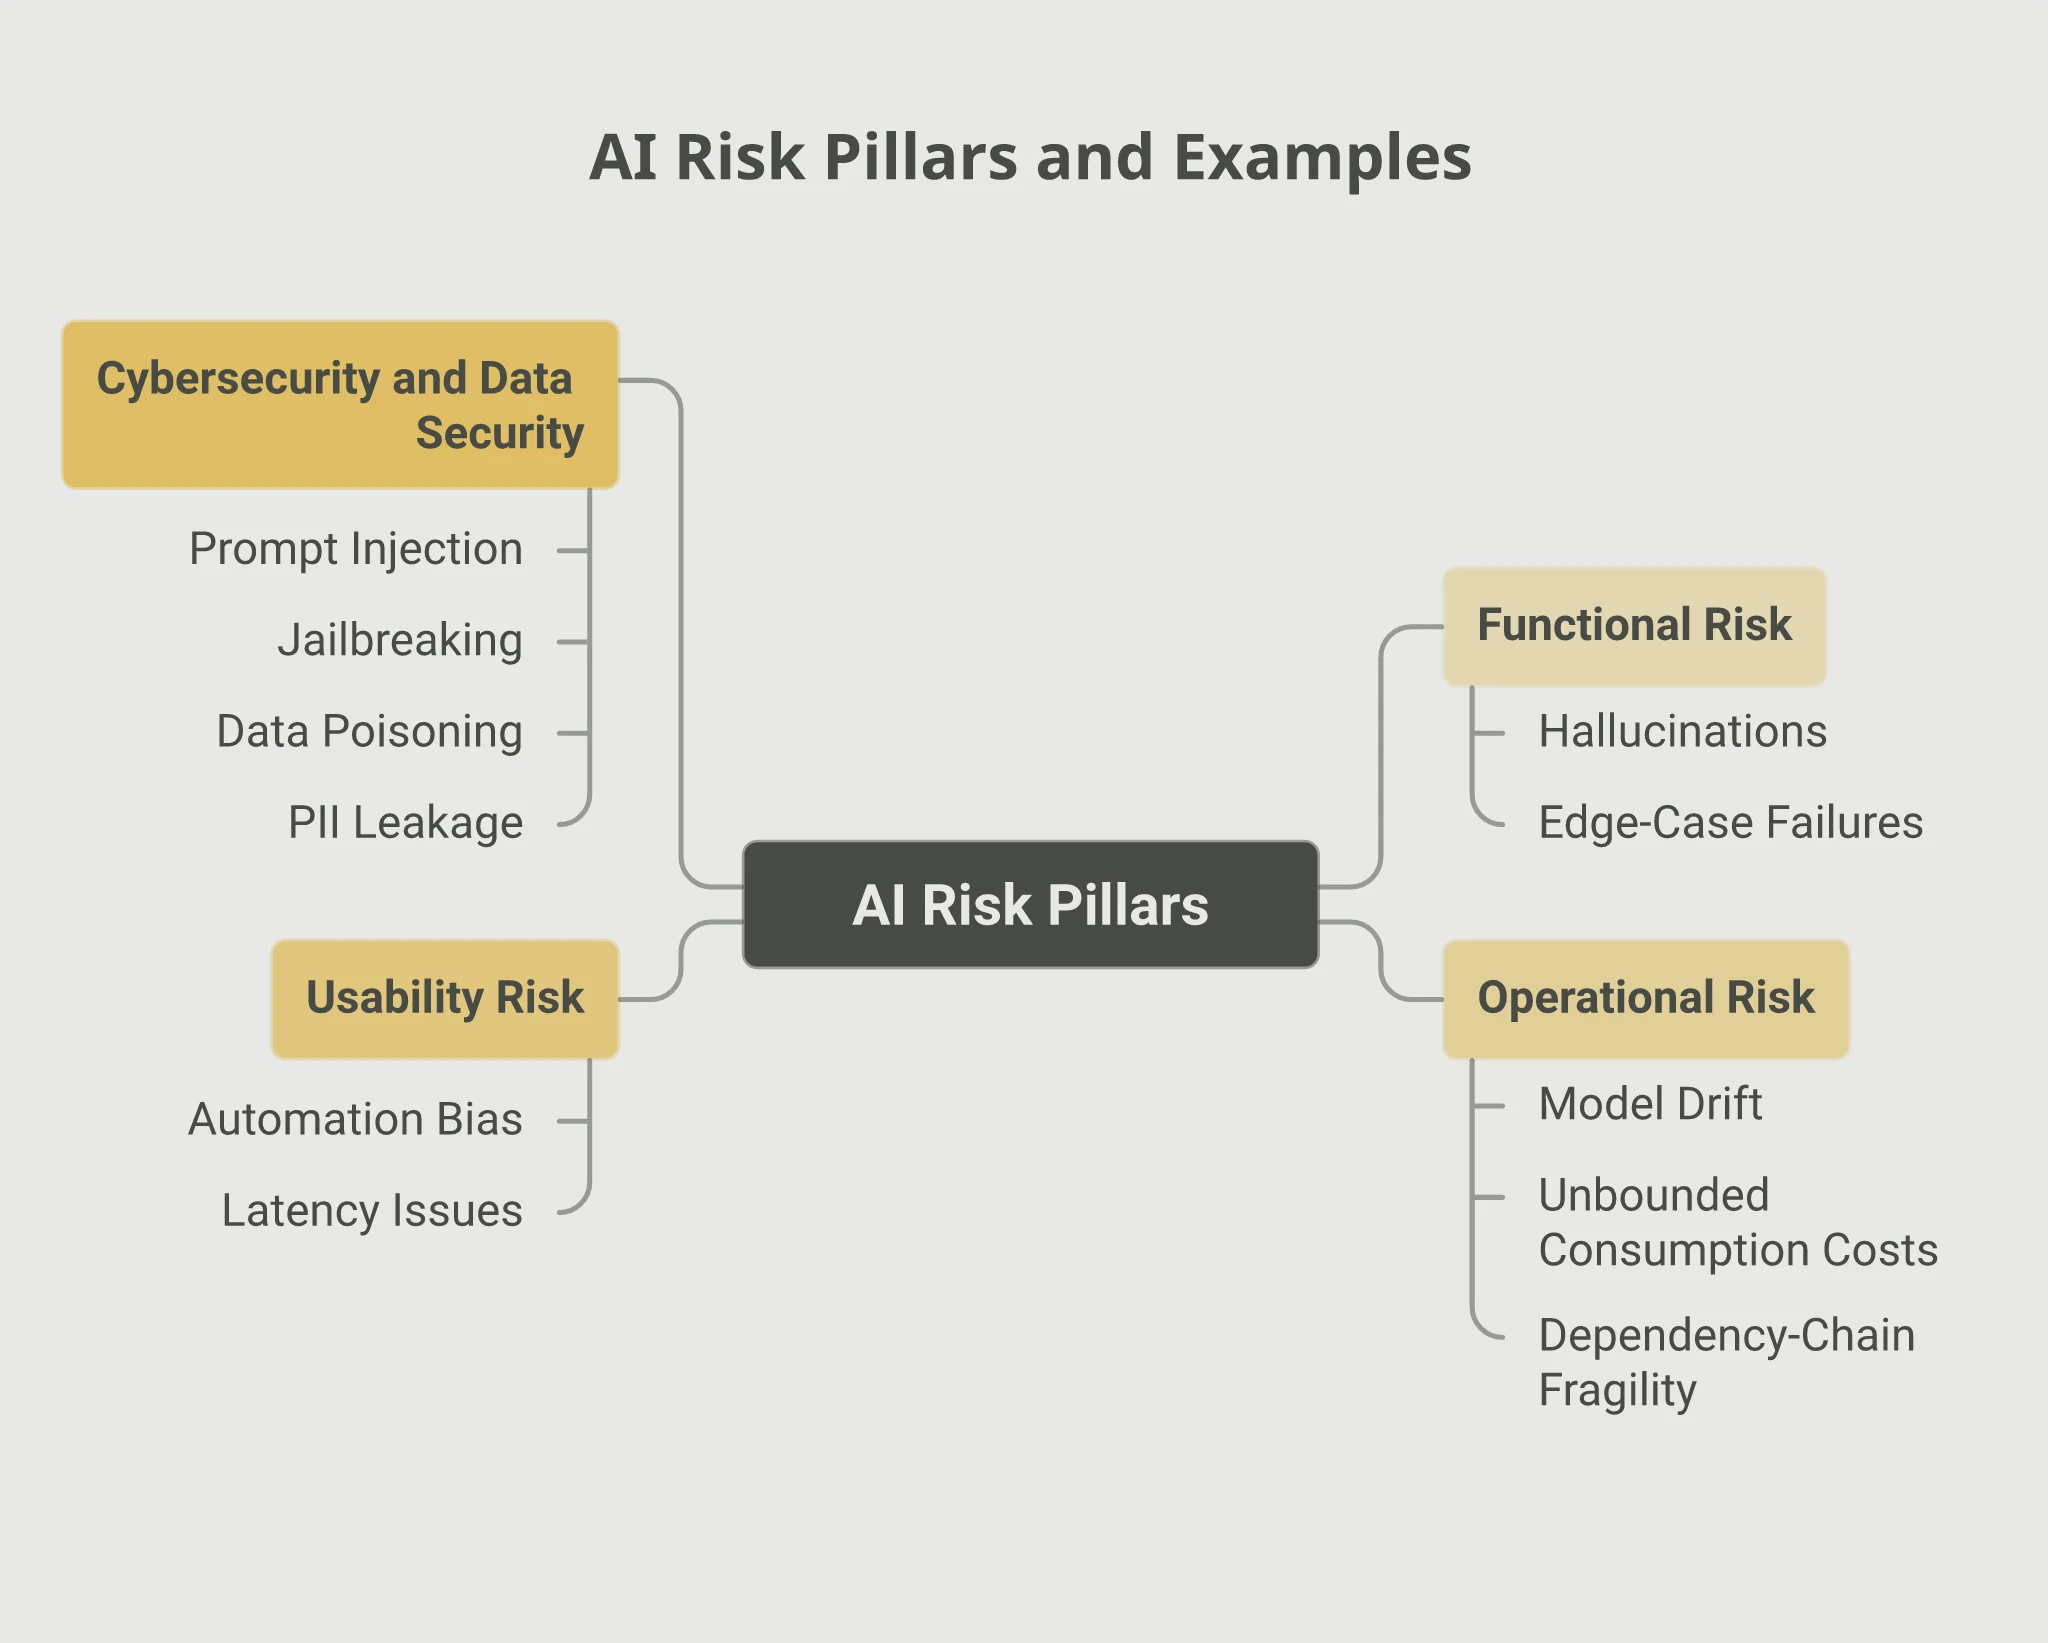
- AI risk spans four pillars (functional, operational, usability, and cybersecurity), and standard Impact × Likelihood risk matrices miss the dimension that matters most: whether a failure is even detectable.
- Scoring risk with FMEA (Severity × Occurrence × Detection) reprioritises what looks urgent: a silent hallucination can rank far above a visible, quickly-recoverable outage.
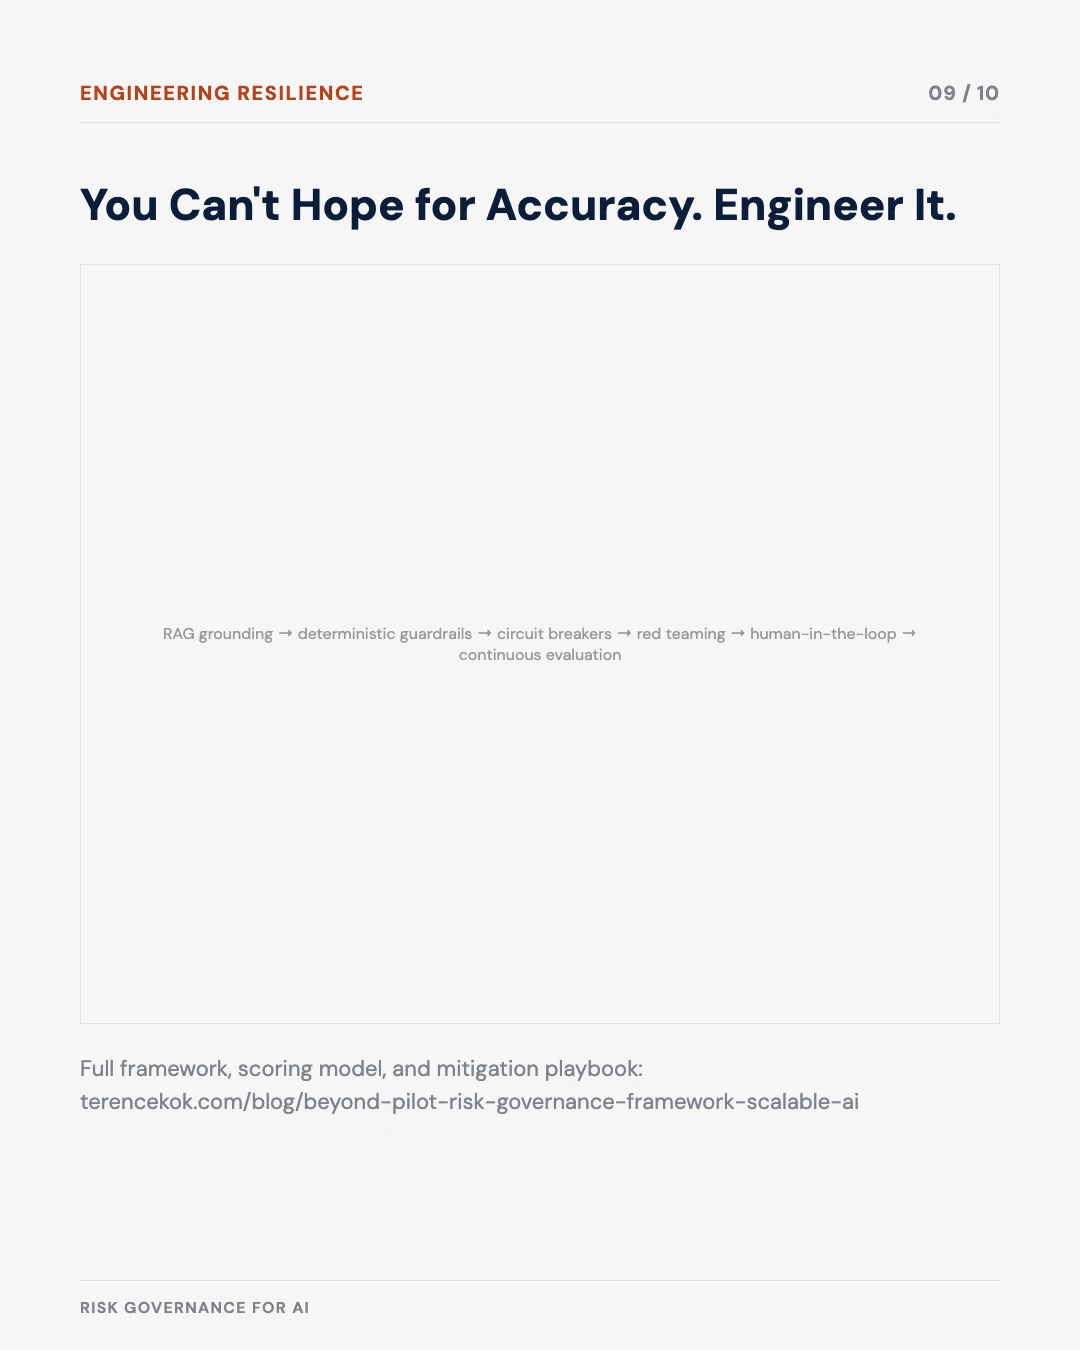
- Reliability has to be engineered in from day one, through RAG grounding, deterministic guardrails, circuit breakers, red teaming, and human-in-the-loop review for high-severity actions.
The risk framework, in ten slides
Save it, share it, or send it to whoever is signing off your production go-live.
We’re at a critical moment in how we build technology. AI is moving from isolated innovation pilots to core infrastructure: the kind that runs cities, manages vital services, and touches millions of lives daily.
In my work with smart city ecosystems, I keep running into the same dangerous assumption: “Our proof of concept worked, so we’re ready for production.”
“A PoC proves capability. Production requires resilience.”
When you integrate AI into municipal operations or critical infrastructure, you’re not just deploying another software system. You’re introducing probabilistic agents into deterministic systems. That’s a different challenge, and traditional IT governance no longer cuts it.
To scale AI successfully with measurable ROI, we need to quantify and manage these risks with the same rigor we apply to civil engineering or cybersecurity.
The framework covers risk, scoring, and mitigation
1. The four pillars of AI risk
AI doesn’t fail like normal software. A crashed server is obvious. A hallucinating AI?
“That’s silent until someone gets hurt or sues.”
Functional risk is when AI makes things up
Unlike traditional code that follows strict if-then logic, AI is non-deterministic. Same input, different outputs. That’s the nature of probabilistic systems.
- Hallucinations: The model confidently generates false information. In a citizen chatbot, that’s annoying. In an emergency response system? That’s a lawsuit waiting to happen.
- Edge Case Failures: Models perform well on the “happy path”: common queries, standard scenarios. But throw something unusual at them, like nuanced language, rare situations, or multi-dialect queries common in Singapore or the GCC, and performance degrades rapidly.
Operational risk determines whether this can run at scale
- Model Drift: Your traffic optimization AI was trained on 2024 data. By now, new urban developments have already changed the picture. Your model? Still giving outdated advice that causes congestion instead of preventing it.
- Unbounded Consumption: OWASP’s Top 10 for LLM Applications (2025) flags this as critical. Inference costs can spiral without architectural caps. A “Denial of Wallet” attack, or simply unexpected viral usage, can destroy your project economics overnight.
- Dependency Chain Fragility: Heavy reliance on proprietary APIs (OpenAI, Anthropic) creates vendor lock-in. You’re exposed to their downtime, policy changes, and pricing decisions. One upstream change breaks your entire system.
Usability risk comes down to the human factor
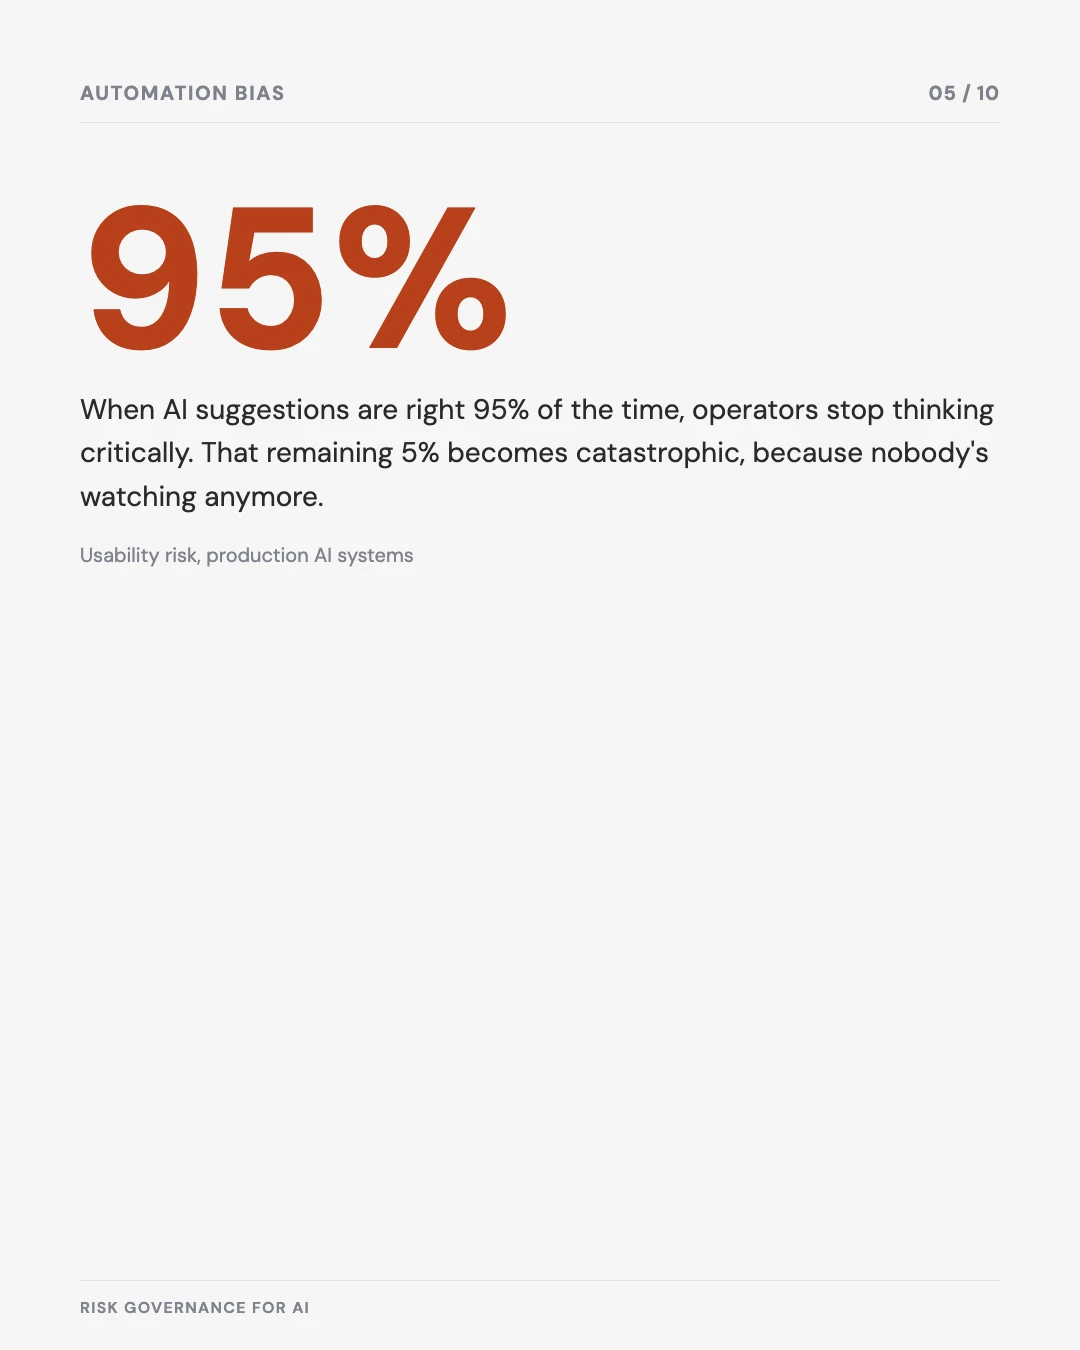
- Automation Bias: When AI suggestions are right 95% of the time, operators stop thinking critically. That 5% becomes catastrophic because nobody’s watching anymore.
- Latency Issues: High-accuracy models like GPT-4 can be slow. For real-time voice applications or interactive systems, that lag makes them functionally unusable. Citizens don’t wait. They abandon.
Cybersecurity and data security open up new attack vectors
- Prompt Injection / Jailbreaking: Malicious users craft inputs specifically designed to bypass your safety guardrails. Your “helpful assistant” suddenly becomes a compliance nightmare.
- Data Poisoning: Attackers corrupt your RAG (Retrieval-Augmented Generation) knowledge base. They manipulate outputs without ever touching the model itself. Your AI starts giving wrong answers based on poisoned sources.
- PII Leakage: The model might accidentally reveal training data or context from another user’s session. In Singapore, this violates the PDPA. Globally, it’s GDPR violations. Either way, it’s expensive fines and lost trust.
2. The scoring framework exists because standard risk matrices fail for AI
Standard risk assessment (Impact × Likelihood) is insufficient for AI because AI failures are silent. A hallucination doesn’t crash your server. It just corrupts your workflow until someone notices the damage.
“We need FMEA (Failure Mode and Effects Analysis) adapted for AI systems.”
Score Each Risk on Three Dimensions (1-5 scale):
- Severity (S): How bad is the damage if this happens?
- 1 = Minor annoyance, users barely notice
- 5 = Critical infrastructure failure, regulatory breach, or reputational catastrophe
- Occurrence (O): How often will this happen?
- 1 = Rare edge case
- 5 = Frequent, potentially every session
- Detection (D): If the model fails, will you even know?
This is the crucial dimension most teams ignore.
- 1 = Immediate automated alert, you know within seconds
- 5 = Silent failure, requires manual audit or external complaint to discover
Risk Priority Number (RPN) = S × O × D
The higher the RPN, the more urgent the mitigation required.
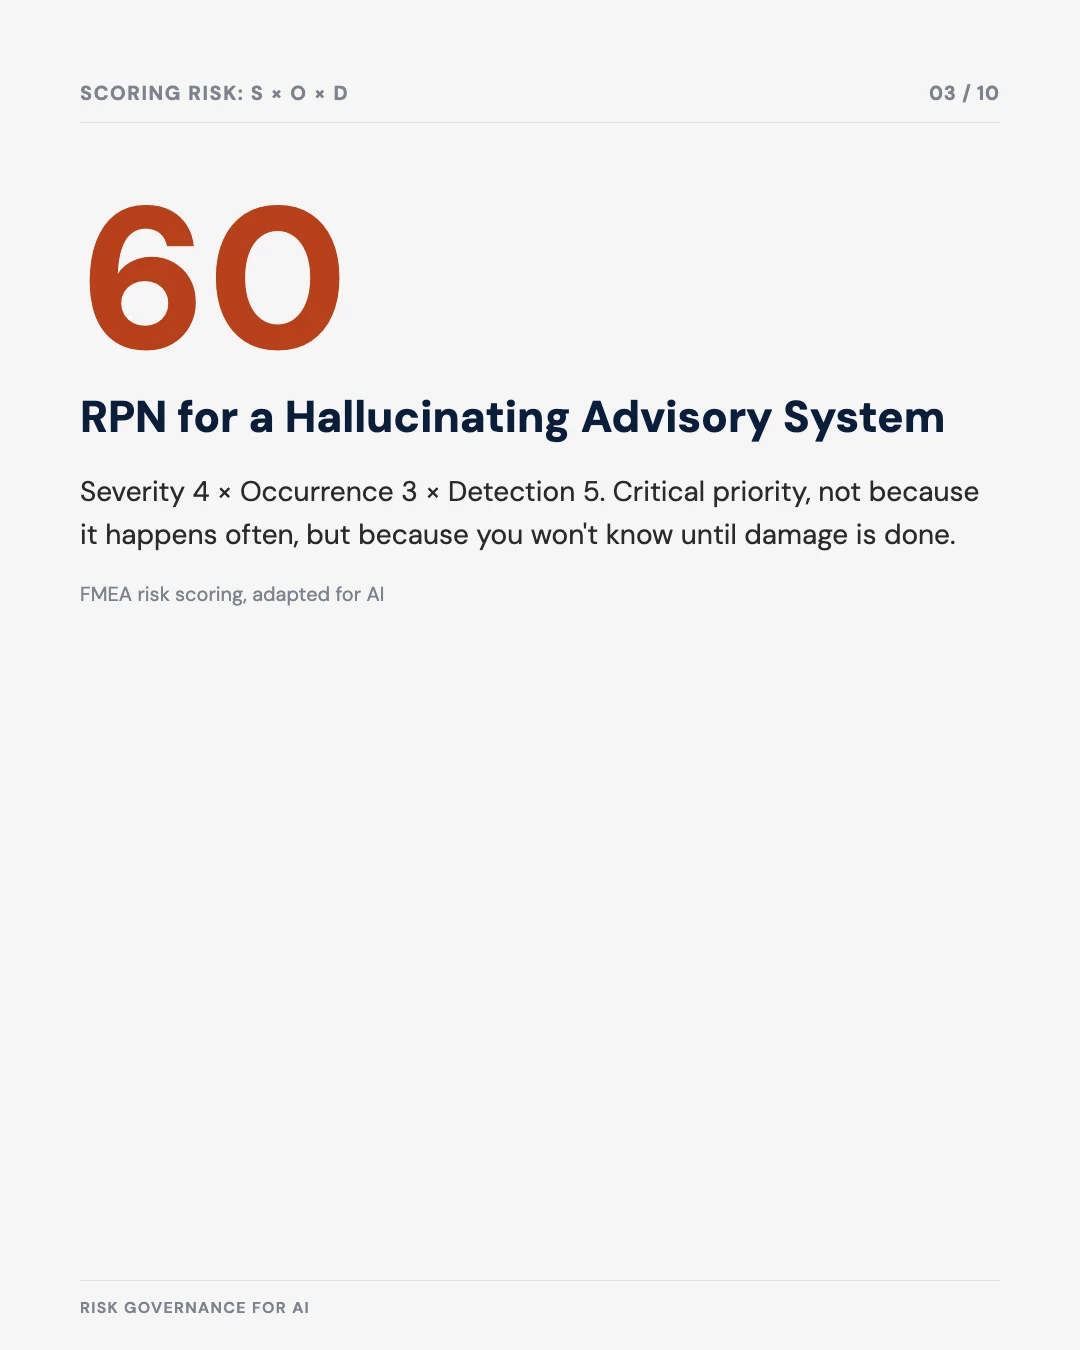
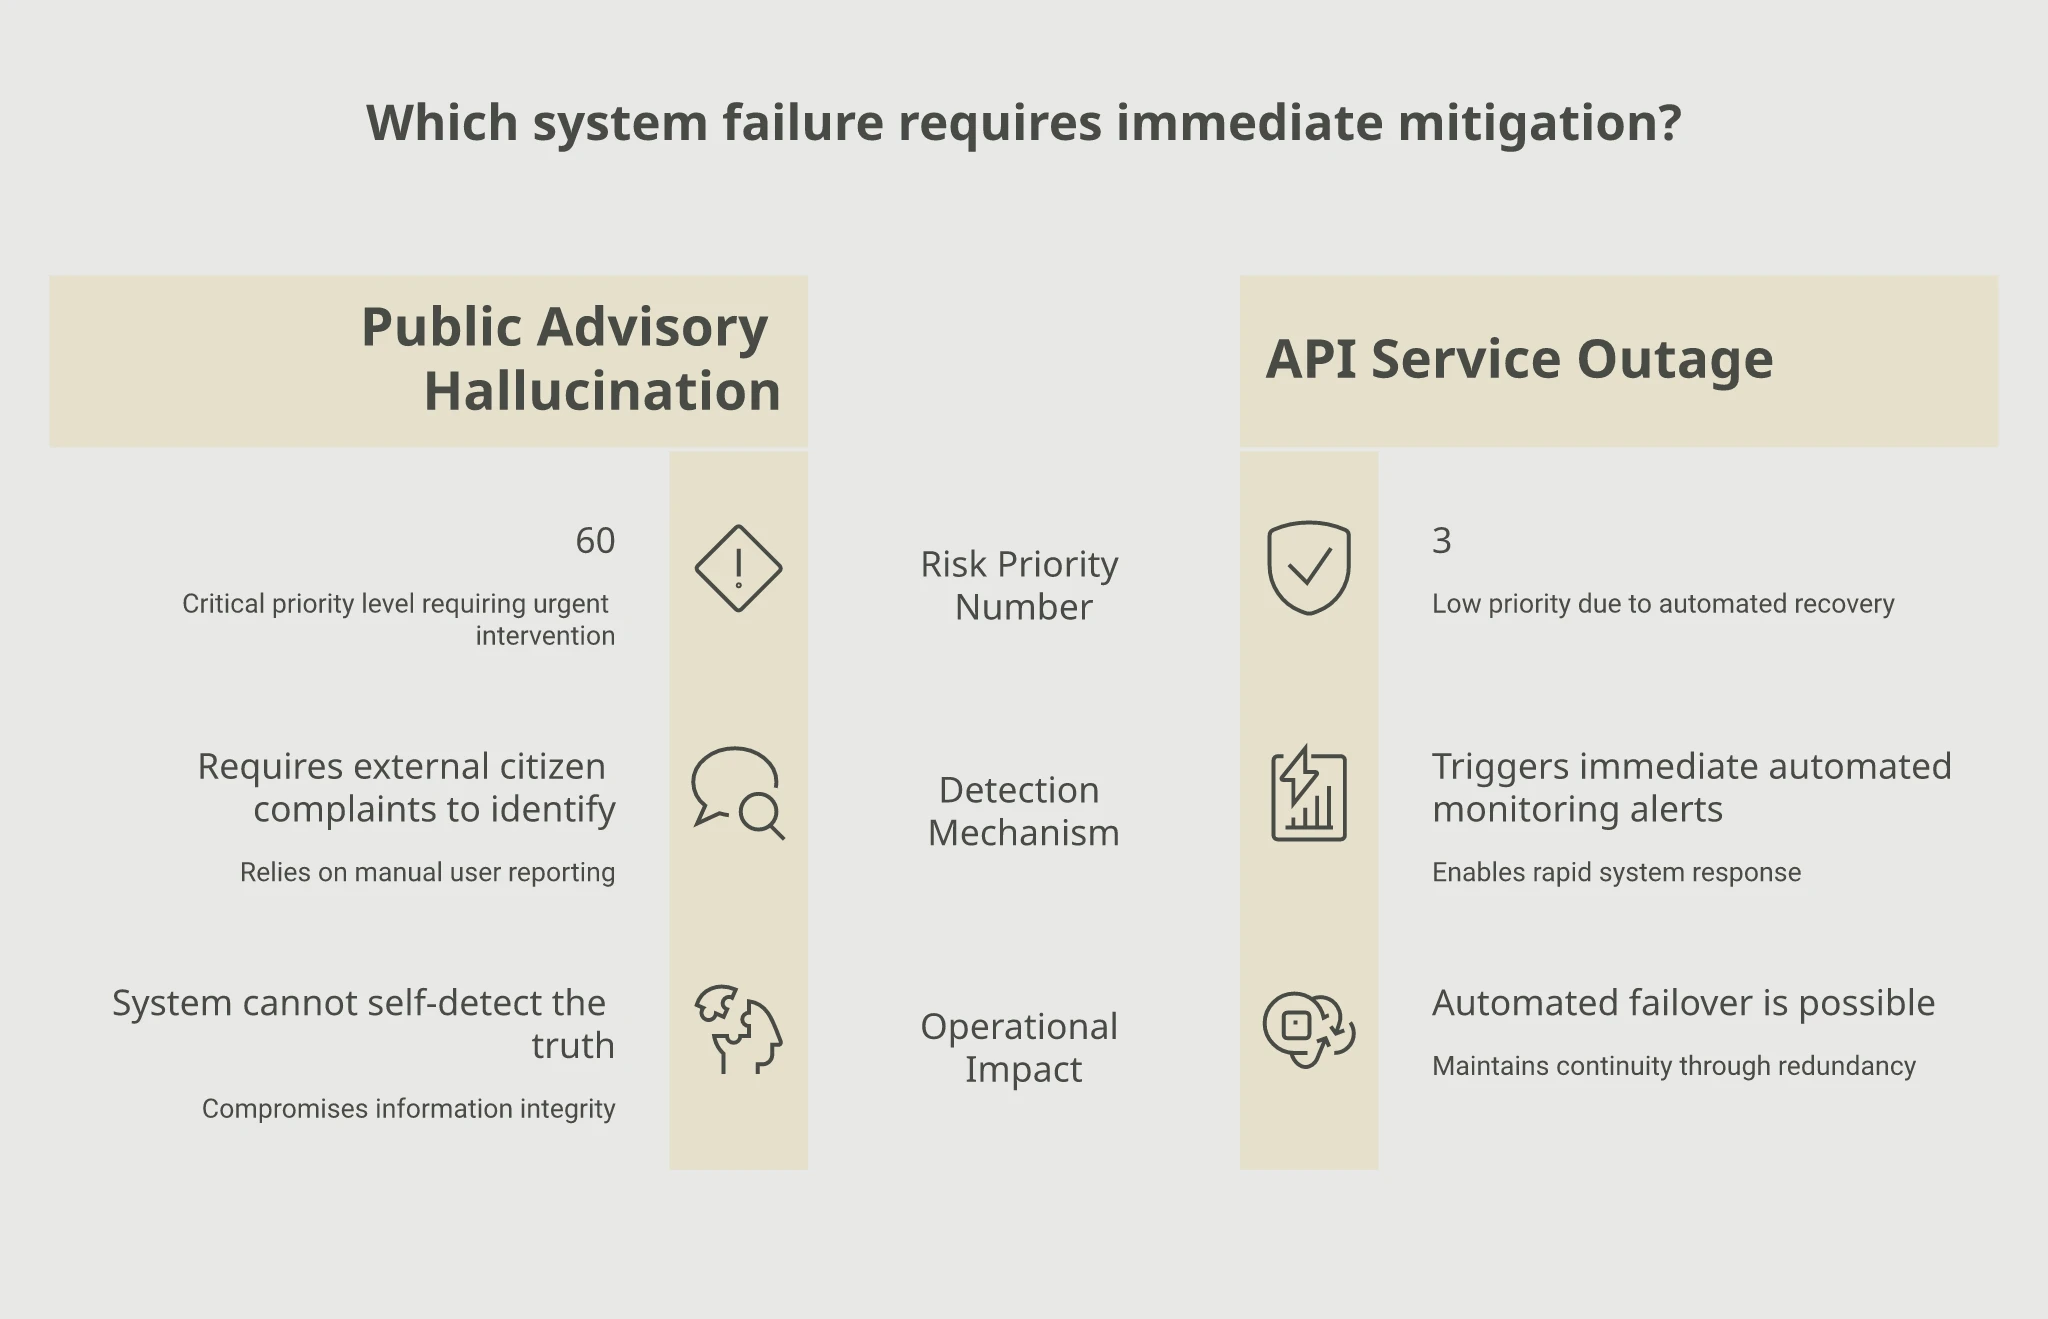
Example: “Hallucination in Public Advisory System”
- Severity: 4 (Misinformation to citizens, potential harm)
- Occurrence: 3 (Occasional with current models)
- Detection: 5 (System cannot self-detect truth; requires citizen complaint)
RPN: 60 (Critical Priority)
Why is this critical? Not because it happens constantly, but because when it does happen, you won’t know until damage is done.
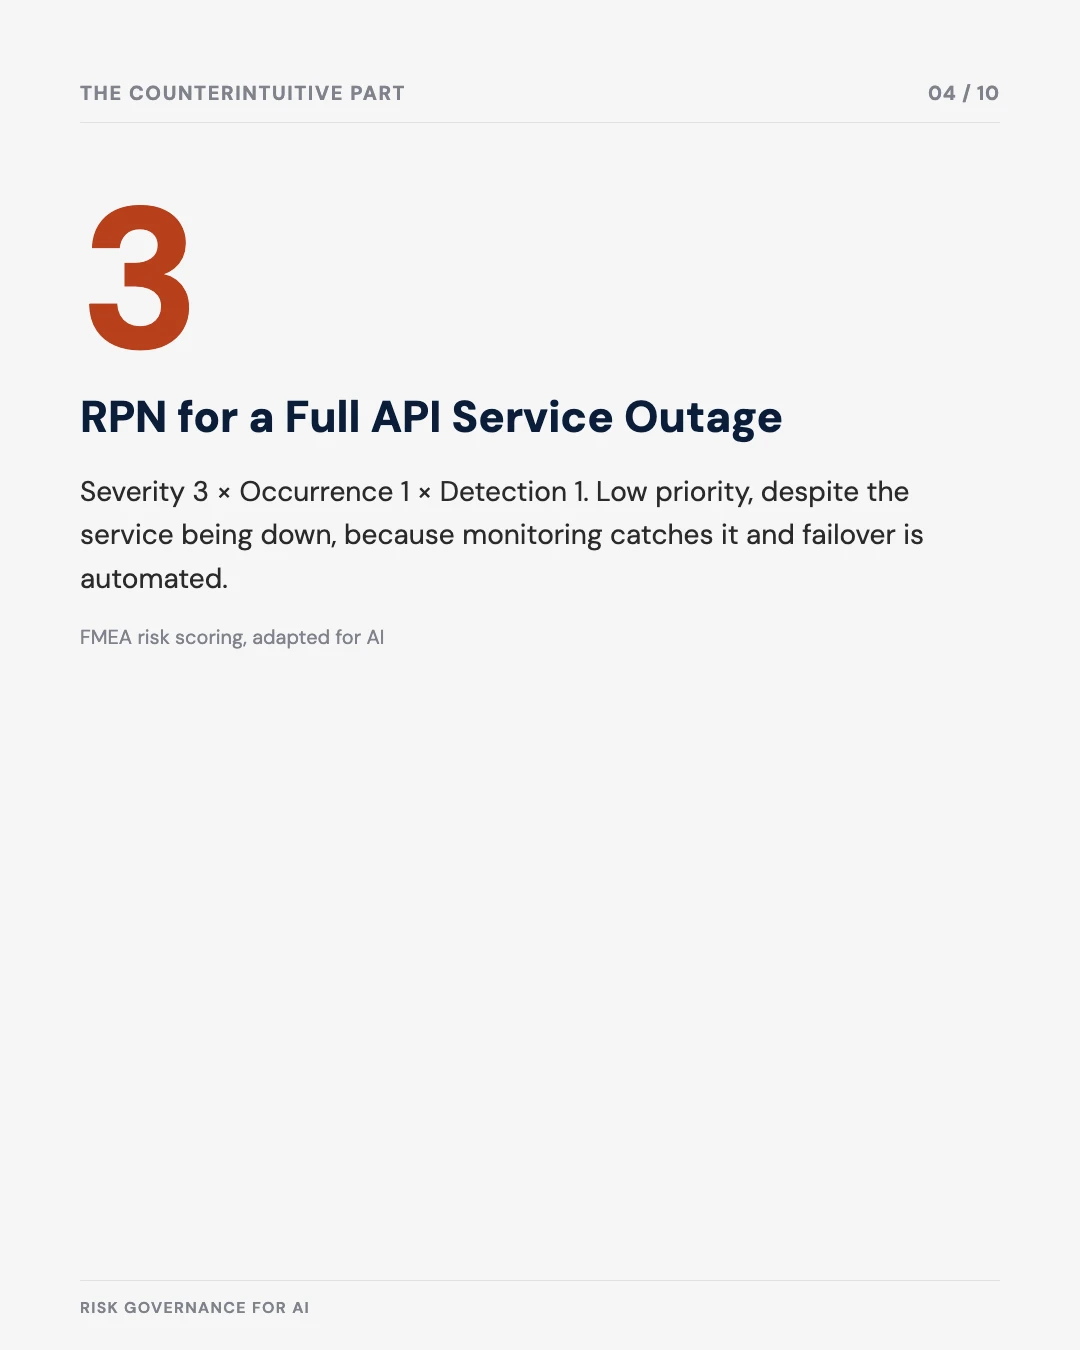
Example: “API Service Outage”
- Severity: 3 (Service temporarily unavailable)
- Occurrence: 1 (Rare with good SLA)
- Detection: 1 (Monitoring alerts immediately, automated failover possible)
RPN: 3 (Low Priority)
This is less urgent than hallucinations despite the service being down, because you can detect and respond immediately.
3. Mitigation strategies engineer resilience into the system
“You cannot ‘hope’ for accuracy. You have to engineer it. Here’s how.”
Technical Controls That Work
- RAG (Retrieval-Augmented Generation): Never rely on the model’s internal “knowledge” for factual information. Ground every response in a vector database of curated, verified, official documents. This forces the AI to act as a summarizer of verified sources) content. I have written a full architecture guide for building this properly for high-stakes use cases.
- Deterministic Guardrails: Wrap your LLM with non-AI code layers: regex patterns, logic checks, format validators. If the AI output violates format rules or security policies, block it before it reaches users. Think of it as a safety net made of traditional code.
- Circuit Breakers: Implement automated scripts that cut off API access if cost or error rates exceed defined thresholds within a 5-minute window. This prevents runaway costs and limits blast radius during attacks or unexpected usage spikes.
Operational Governance That Catches What Tech Misses
- Red Teaming: Before launch, employ adversarial teams whose job is to break your model. They inject malicious prompts, trigger toxic outputs, attempt jailbreaks. Emerging standards like NIST AI RMF and ISO 42001 now require it.
- Human-in-the-Loop (HITL): For high-severity actions, like approving permits, dispatching emergency crews, or making financial decisions, the AI drafts the action but a human must commit it. The AI augments judgment; it doesn’t replace it. As these oversight layers mature, some organisations are deliberately redesigning them: see From Human-in-the-Loop to AI-on-the-Loop.
- Continuous Evaluation Pipelines: Build “Golden Sets”: curated databases with 1,000+ verified Q&A pairs representing your system’s expected behavior. Every time you update the model, prompt, or knowledge base, run automated regression tests. If accuracy drops, you catch it before users do.
Production AI Requires a Different Playbook
Moving from pilot to production means changing how you think about risk, not buying more GPUs or scaling infrastructure.
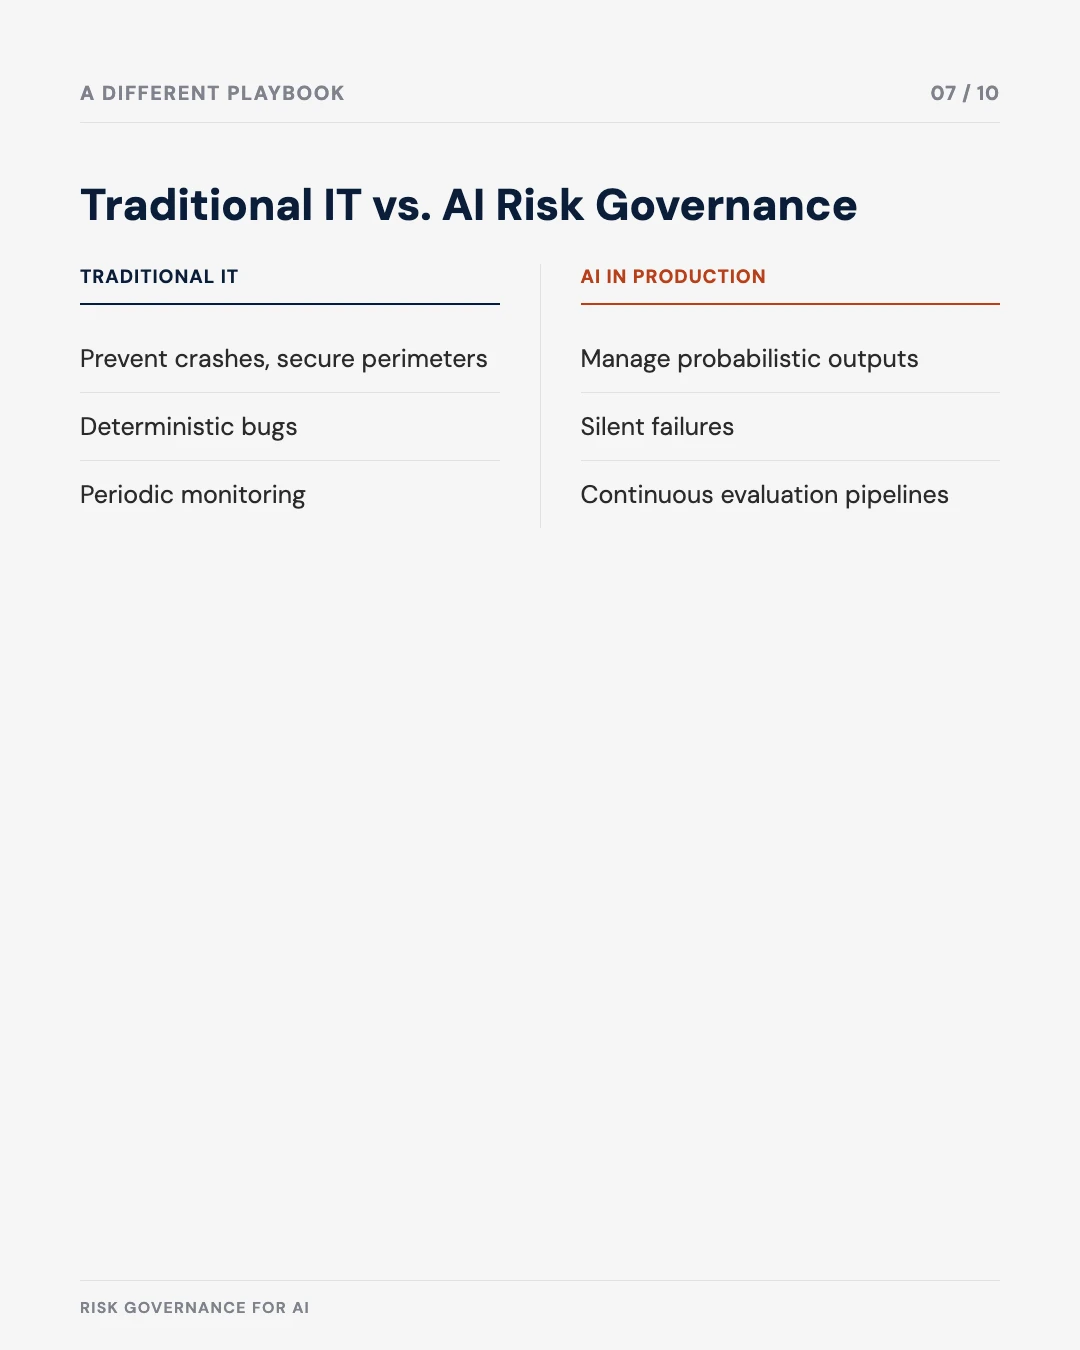
Traditional IT taught us to prevent crashes and secure perimeters. AI requires us to manage probabilistic outputs, silent failures, and second-order effects we can’t always predict.
- Score your risks systematically. Use FMEA. Don’t guess at priorities. Calculate them based on severity, occurrence, and detectability.
- Engineer reliability from day one. RAG, guardrails, circuit breakers. These aren’t nice-to-haves. They’re the foundation of production AI.
- Monitor continuously. AI degrades over time as the world changes. Your golden sets and regression tests need to run with every update.
- Accept that humans remain essential. For high-stakes decisions, AI should augment, not replace, human judgment. That’s not a limitation of the technology; it’s a design principle for responsible deployment.
Your Next Step
If you’re running an AI pilot right now and thinking about production, ask yourself one question:
“If this AI fails silently tomorrow, how long until we notice, and what’s the damage in that window?”
If the answer makes you uncomfortable, you’re not ready for production yet. And that’s okay. Better to build the right foundations now than to clean up a trust crisis later.
The gap between pilot and production comes down to governance. Bridge it, and you don’t just deploy AI. You deploy AI that lasts.
Evidence & Methodology
This framework borrows a scoring method from manufacturing and applies it somewhere it has not been formally tested. That is worth saying plainly before you build a governance programme around it.
| Claim | Source | Grade |
|---|---|---|
| FMEA (Severity x Occurrence x Detection) surfaces silent AI risks that a standard Impact x Likelihood matrix misses | Adapted from manufacturing and quality-engineering FMEA, applied to AI here, not tested against a body of real AI incidents | Adapted |
| Unbounded consumption and denial-of-wallet attacks are a critical LLM risk | OWASP GenAI Security Project’s 2025 top 10 for LLM applications | Standard |
| Automation bias sets in once an AI system is right roughly 95% of the time, so operators stop checking it | A general pattern from human-factors research, not tied to a specific citation in this post | Unsourced |
| The two worked examples, RPN 60 for a hallucination versus RPN 3 for an outage | Illustrative scoring I constructed to show how the formula behaves, not a scored incident from a real deployment | Illustrative |
Sources
- OWASP GenAI Security Project. (2025). OWASP top 10 for LLM applications (2025).
Free tool
TRACE Agent Evaluation
Before you hand an agent a high-severity action like dispatching a crew or approving a permit, score the task on Traceability, Reversibility, Acceptance, Compliance, and Escalation.
Free tool
AI Trust, Risk & Governance Dashboard
Operationalise the cybersecurity pillar from this framework: surface prompt-injection and data-poisoning threats and score your RAG access-control posture.
Was this useful?