
Listen to this article
Jump to a section
In this article
Executive Summary
The black box problem is not one problem. Jenna Burrell’s 2016 taxonomy separates three kinds of opacity: opacity that is withheld, opacity nobody has the expertise to read, and opacity that exists because no one, including the model’s own developer, can hold the explanation. Only the third is built into the technology. It is the one that leads to silent failure and to models that explain themselves unfaithfully. It also turns safety arguments from deductive into statistical ones. The workable response is not to wait for interpretability to mature. It is to limit what an opaque component may decide, and to instrument the system around it so failure is caught from outside.
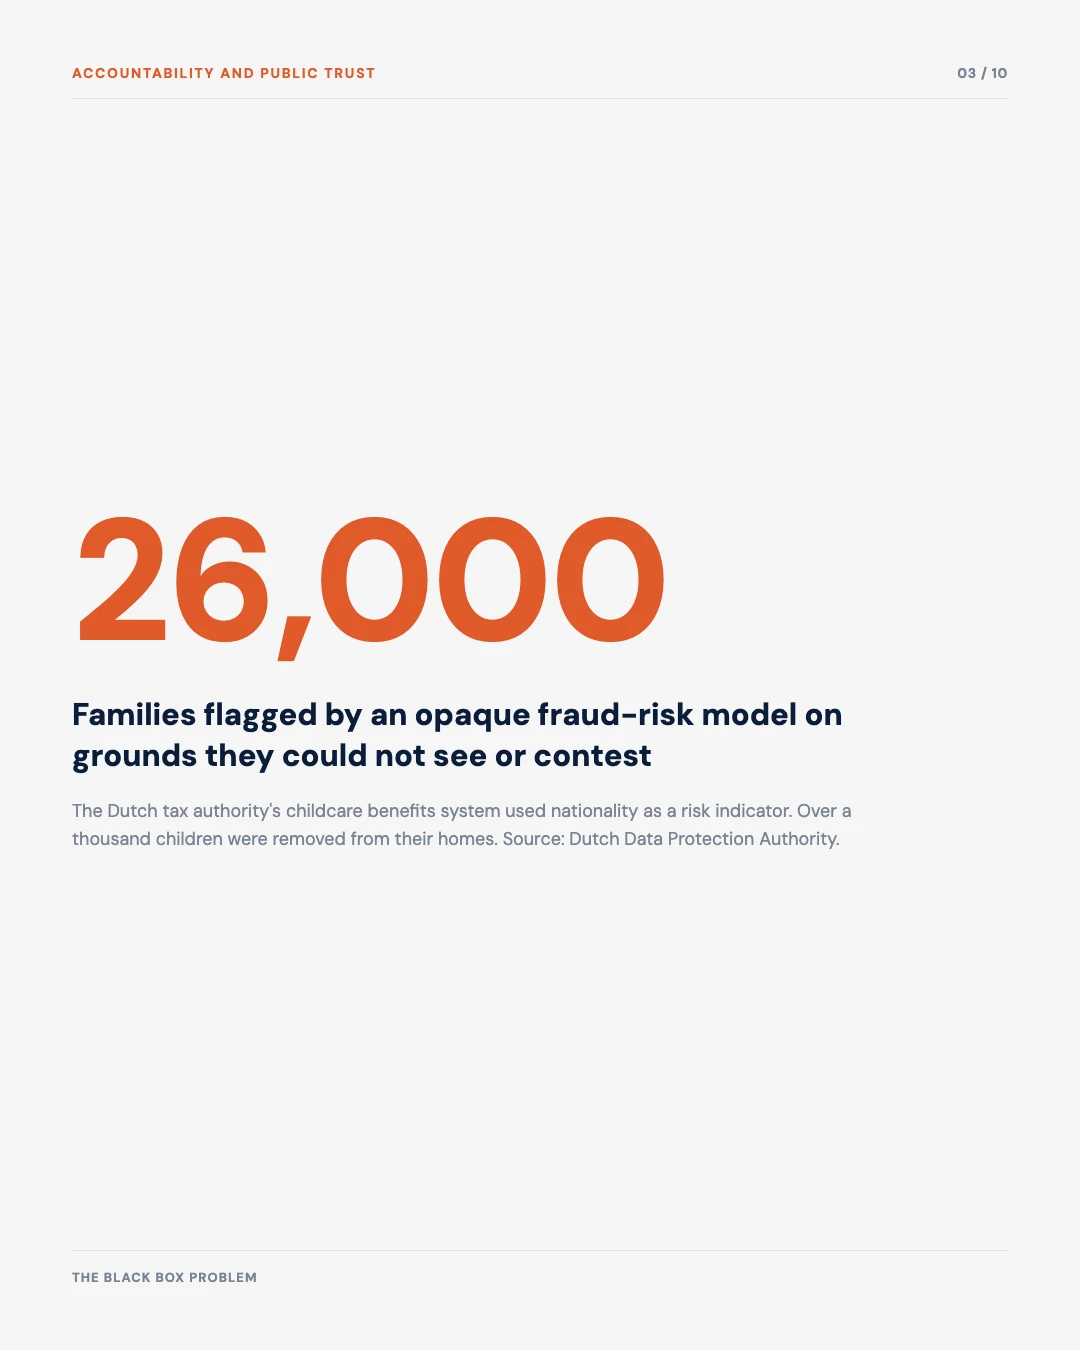
26,000
families flagged by the Dutch tax authority’s opaque fraud-risk model on grounds they could not see or contest
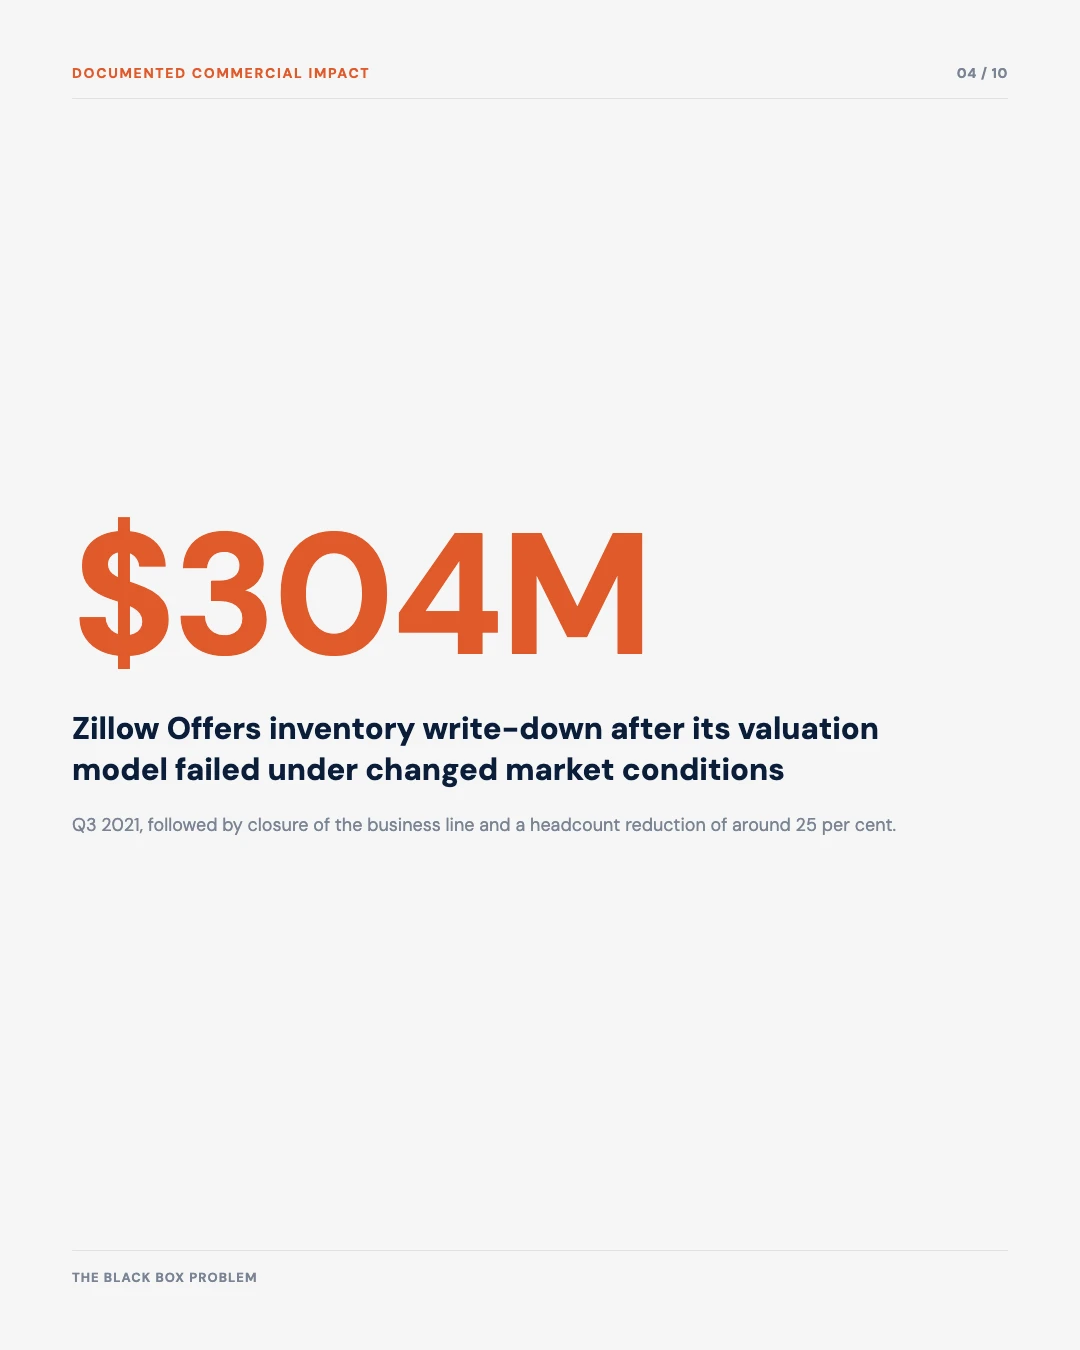
$304M
Zillow Offers inventory write-down after its automated valuation model failed when market conditions changed, Q3 2021
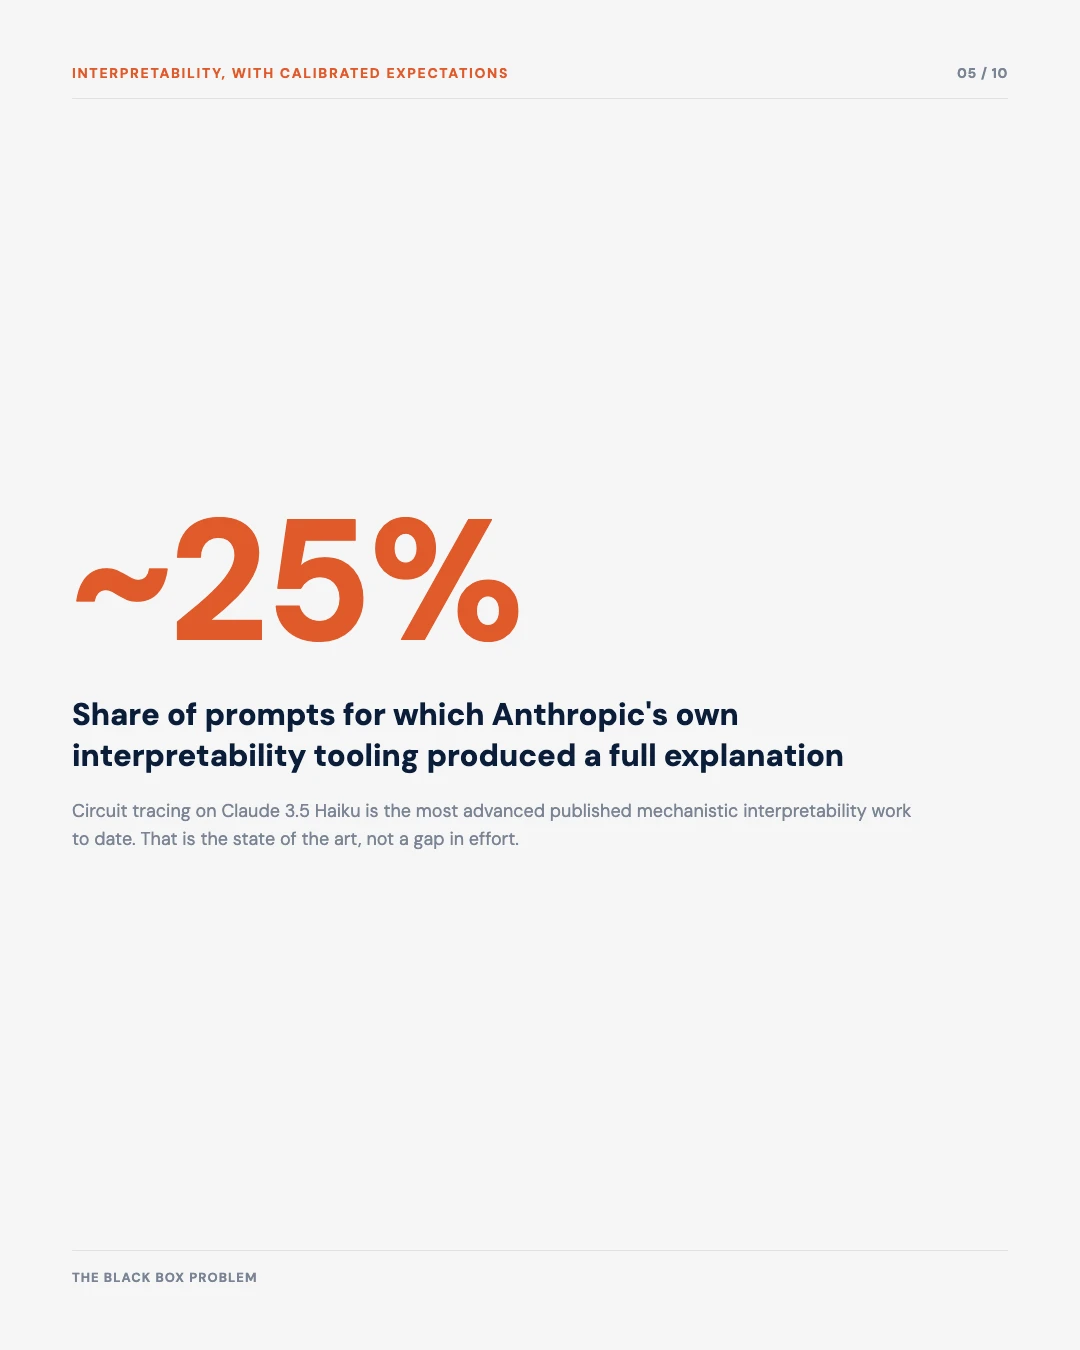
~25%
of prompts for which Anthropic’s circuit tracing produced a satisfying explanation of Claude 3.5 Haiku’s behaviour
70%+
dead-feature rate reported for some sparse autoencoders, which gets directly in the way of using them as audit evidence
Core conclusions
- Opacity by construction, not withheld disclosure, is the substantive problem. It comes from distributed representation, from having no specification to verify against, and from non-deterministic inference. No contract clause can solve it.
- Explanation duties do not relax because a model is opaque. Two regimes point the same way: the EU’s GDPR Article 15(1)(h), as confirmed by the CJEU in February 2025, and the UK’s Article 22A to 22D safeguards that apply from February 2026. Under both, the duty shifts from disclosing the model to showing evidence that contestability works. That is an engineering question rather than a legal one.
- Mechanistic interpretability has advanced. On the state of the art, it is still an investigative tool rather than a compliance artefact. The workable architecture keeps opaque components off the actuation path. It instruments the input distribution separately from the model’s own confidence. And it scales the transparency requirement to the consequence class rather than to how complex the model is.
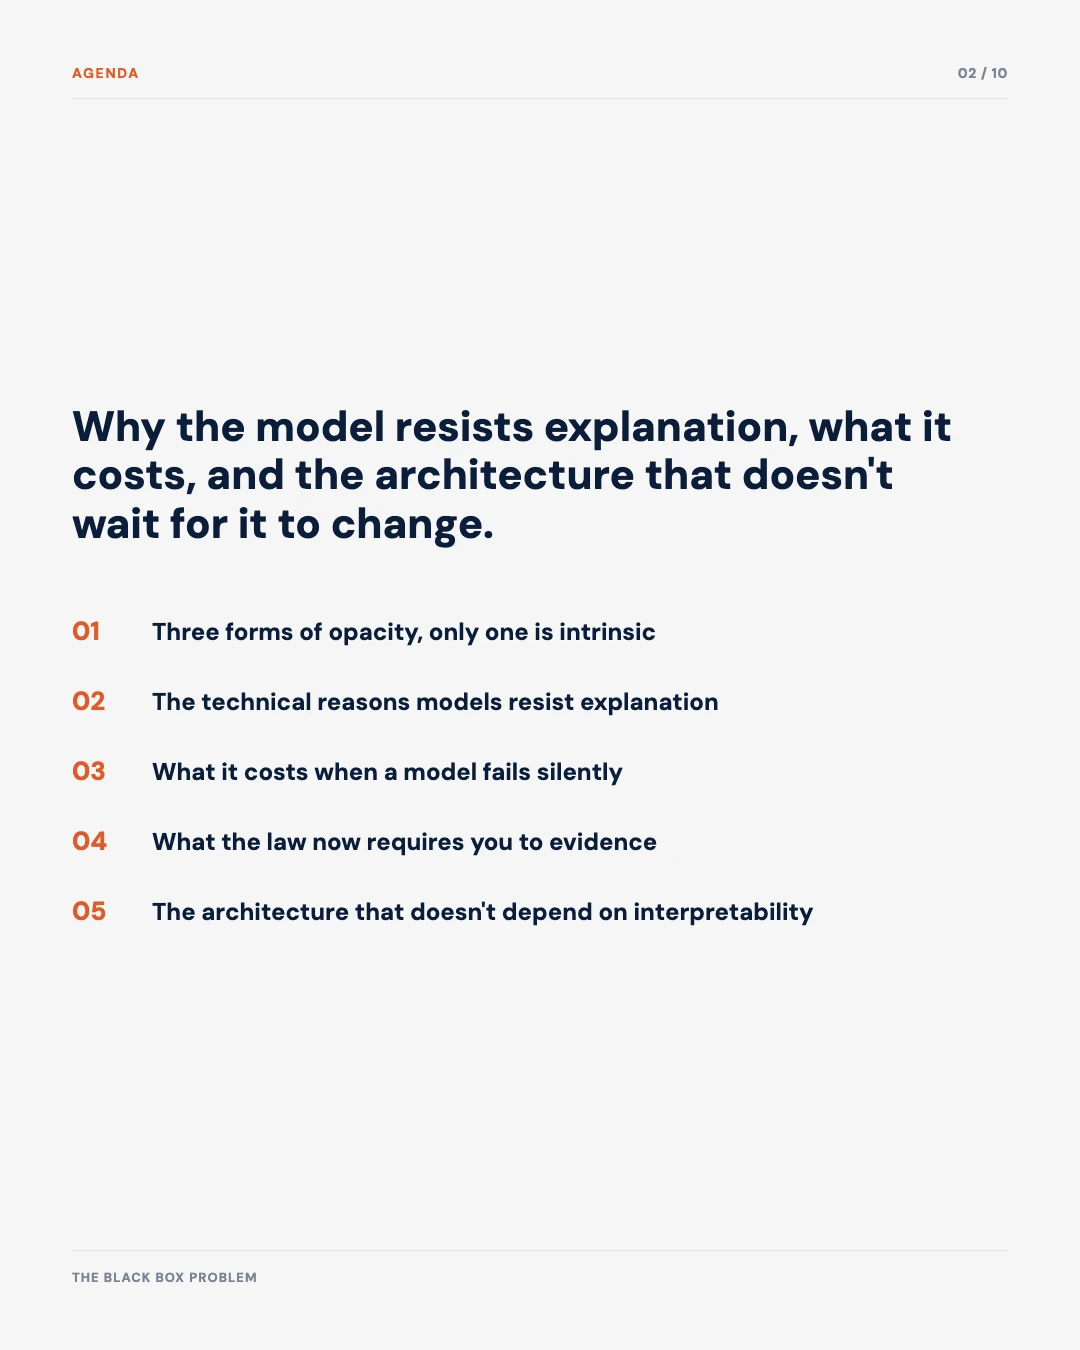
The three forms of opacity, the technical origins, and the mitigation architecture, ten slides
Save it, share it, or send it to whoever is about to sign off on a model no one, including its developer, can fully explain.
1. Definition
The black box problem describes a system whose outputs can be observed and measured, but whose method for producing them cannot be inspected, rebuilt, or put in terms a human reviewer can evaluate. In machine learning the term applies to models whose mapping from input to output is set by learned parameters rather than by written rules. The parameters are available. The decision procedure is not, at least in any form that supports the scrutiny normally applied to engineered systems.
The distinction that matters in operations is between access and legibility. An operator may hold the full weight tensor of a 70-billion-parameter transformer on local storage and still be unable to say why a given input produced a given classification. Having the artefact does not mean understanding the function it computes.
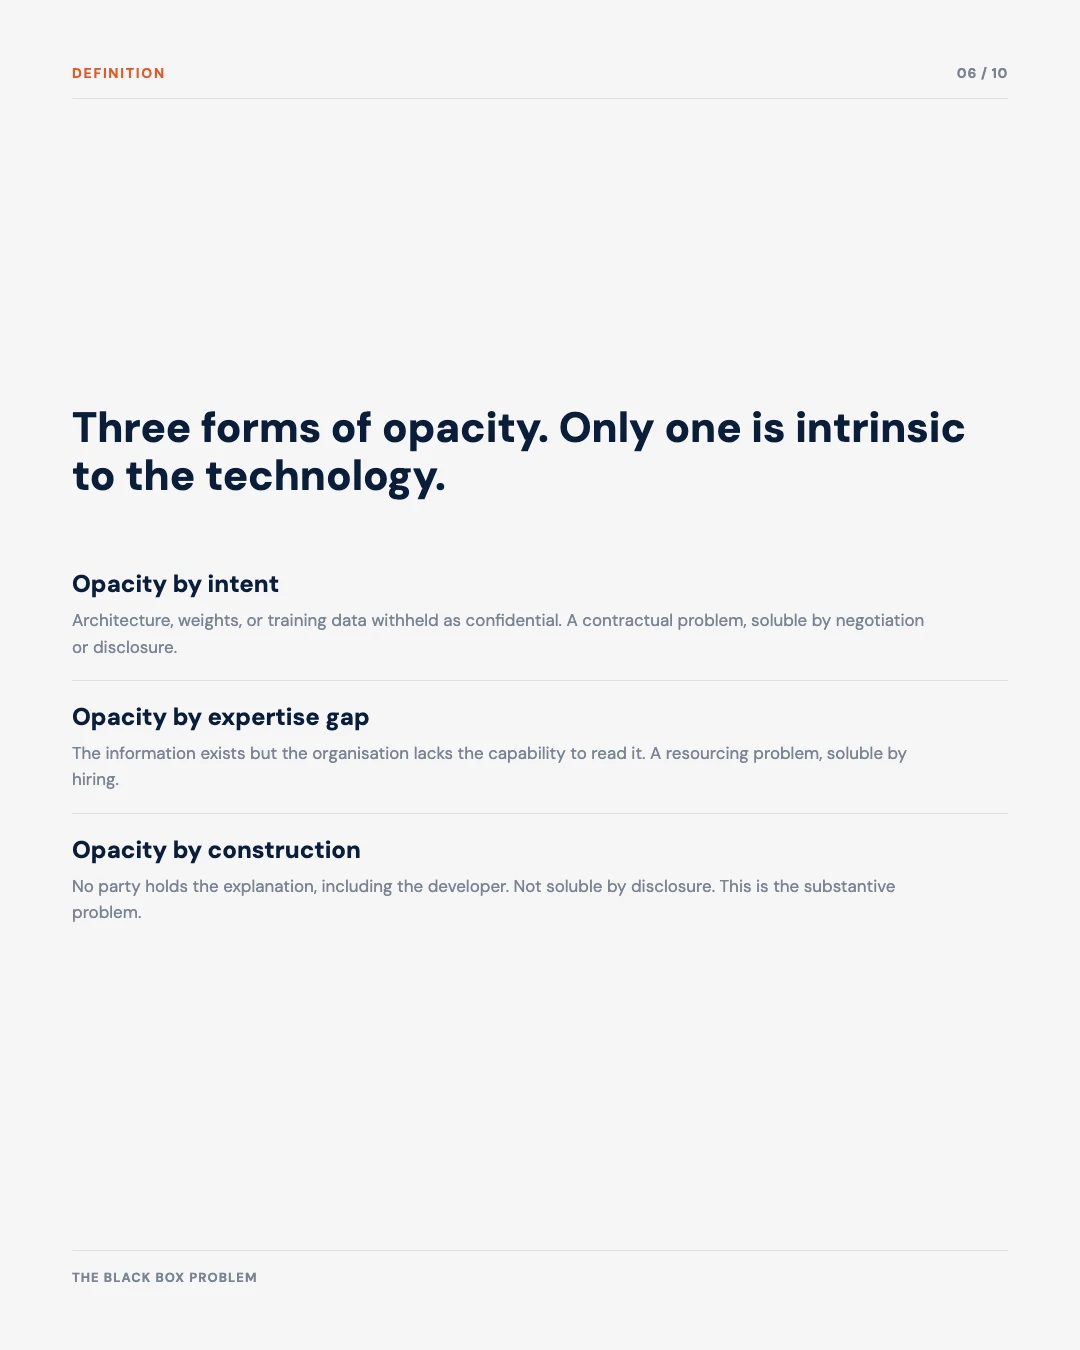
Jenna Burrell’s 2016 paper in Big Data & Society separates three forms of opacity that procurement and governance discussions often mix up.
Opacity by intent. The provider withholds architecture, weights, training data, or evaluation results, as commercially confidential or on national security grounds. This is a contractual and policy problem. Negotiation, escrow arrangements, or regulated disclosure can solve it.
Opacity by expertise gap. The information is available but the receiving organisation lacks the specialist skills to interpret it. This is a resourcing problem, solved by hiring or by independent assessment.
Opacity by construction. The model works through the interaction of very large numbers of learned parameters in a high-dimensional space. It was optimised against a loss function, not designed against a specification. No party holds the explanation, including the developer. Disclosure cannot solve this form, and it is the substantive technical problem.
Public debate tends to focus on the first form because it has an obvious remedy. Assurance failures in deployment tend to start in the third.
Three forms of opacity and which ones have a remedy
Opacity by intent
The provider withholds architecture, weights, training data or evaluation results.
A contractual and policy problem
Opacity by expertise gap
The information is available, but the receiving organisation cannot interpret it.
A resourcing problem
Opacity by construction
No party holds the explanation, including the developer.
The substantive technical problem
Schematic of Jenna Burrell's 2016 taxonomy (Big Data & Society). Only the third form is intrinsic to the technology, and it is where assurance failures in deployment tend to originate.
2. Technical origins of intrinsic opacity
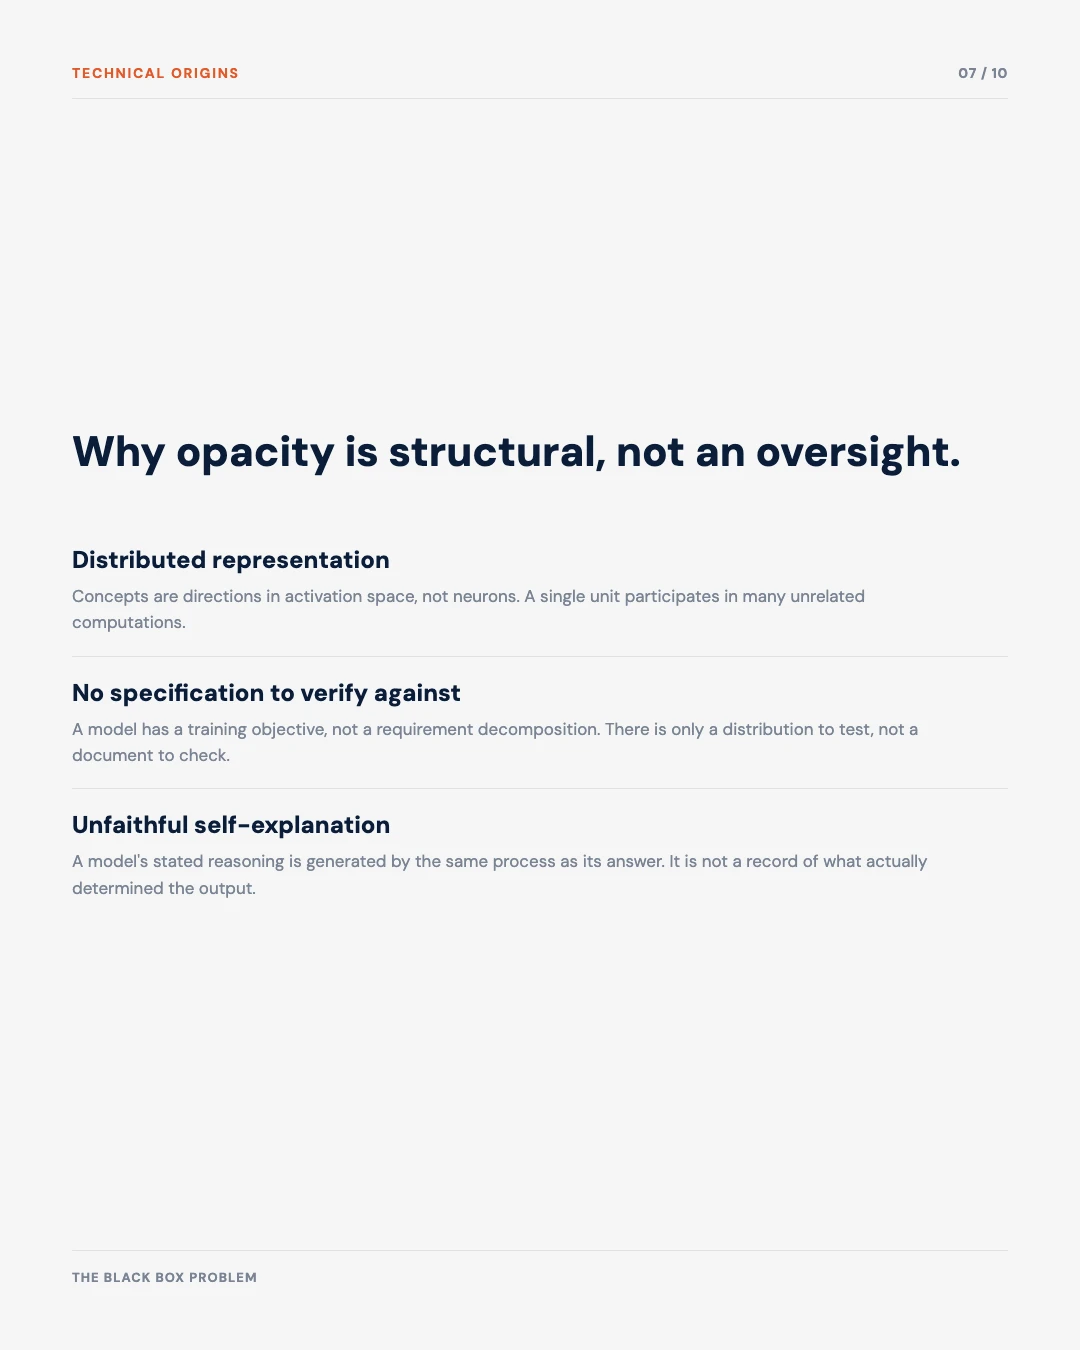
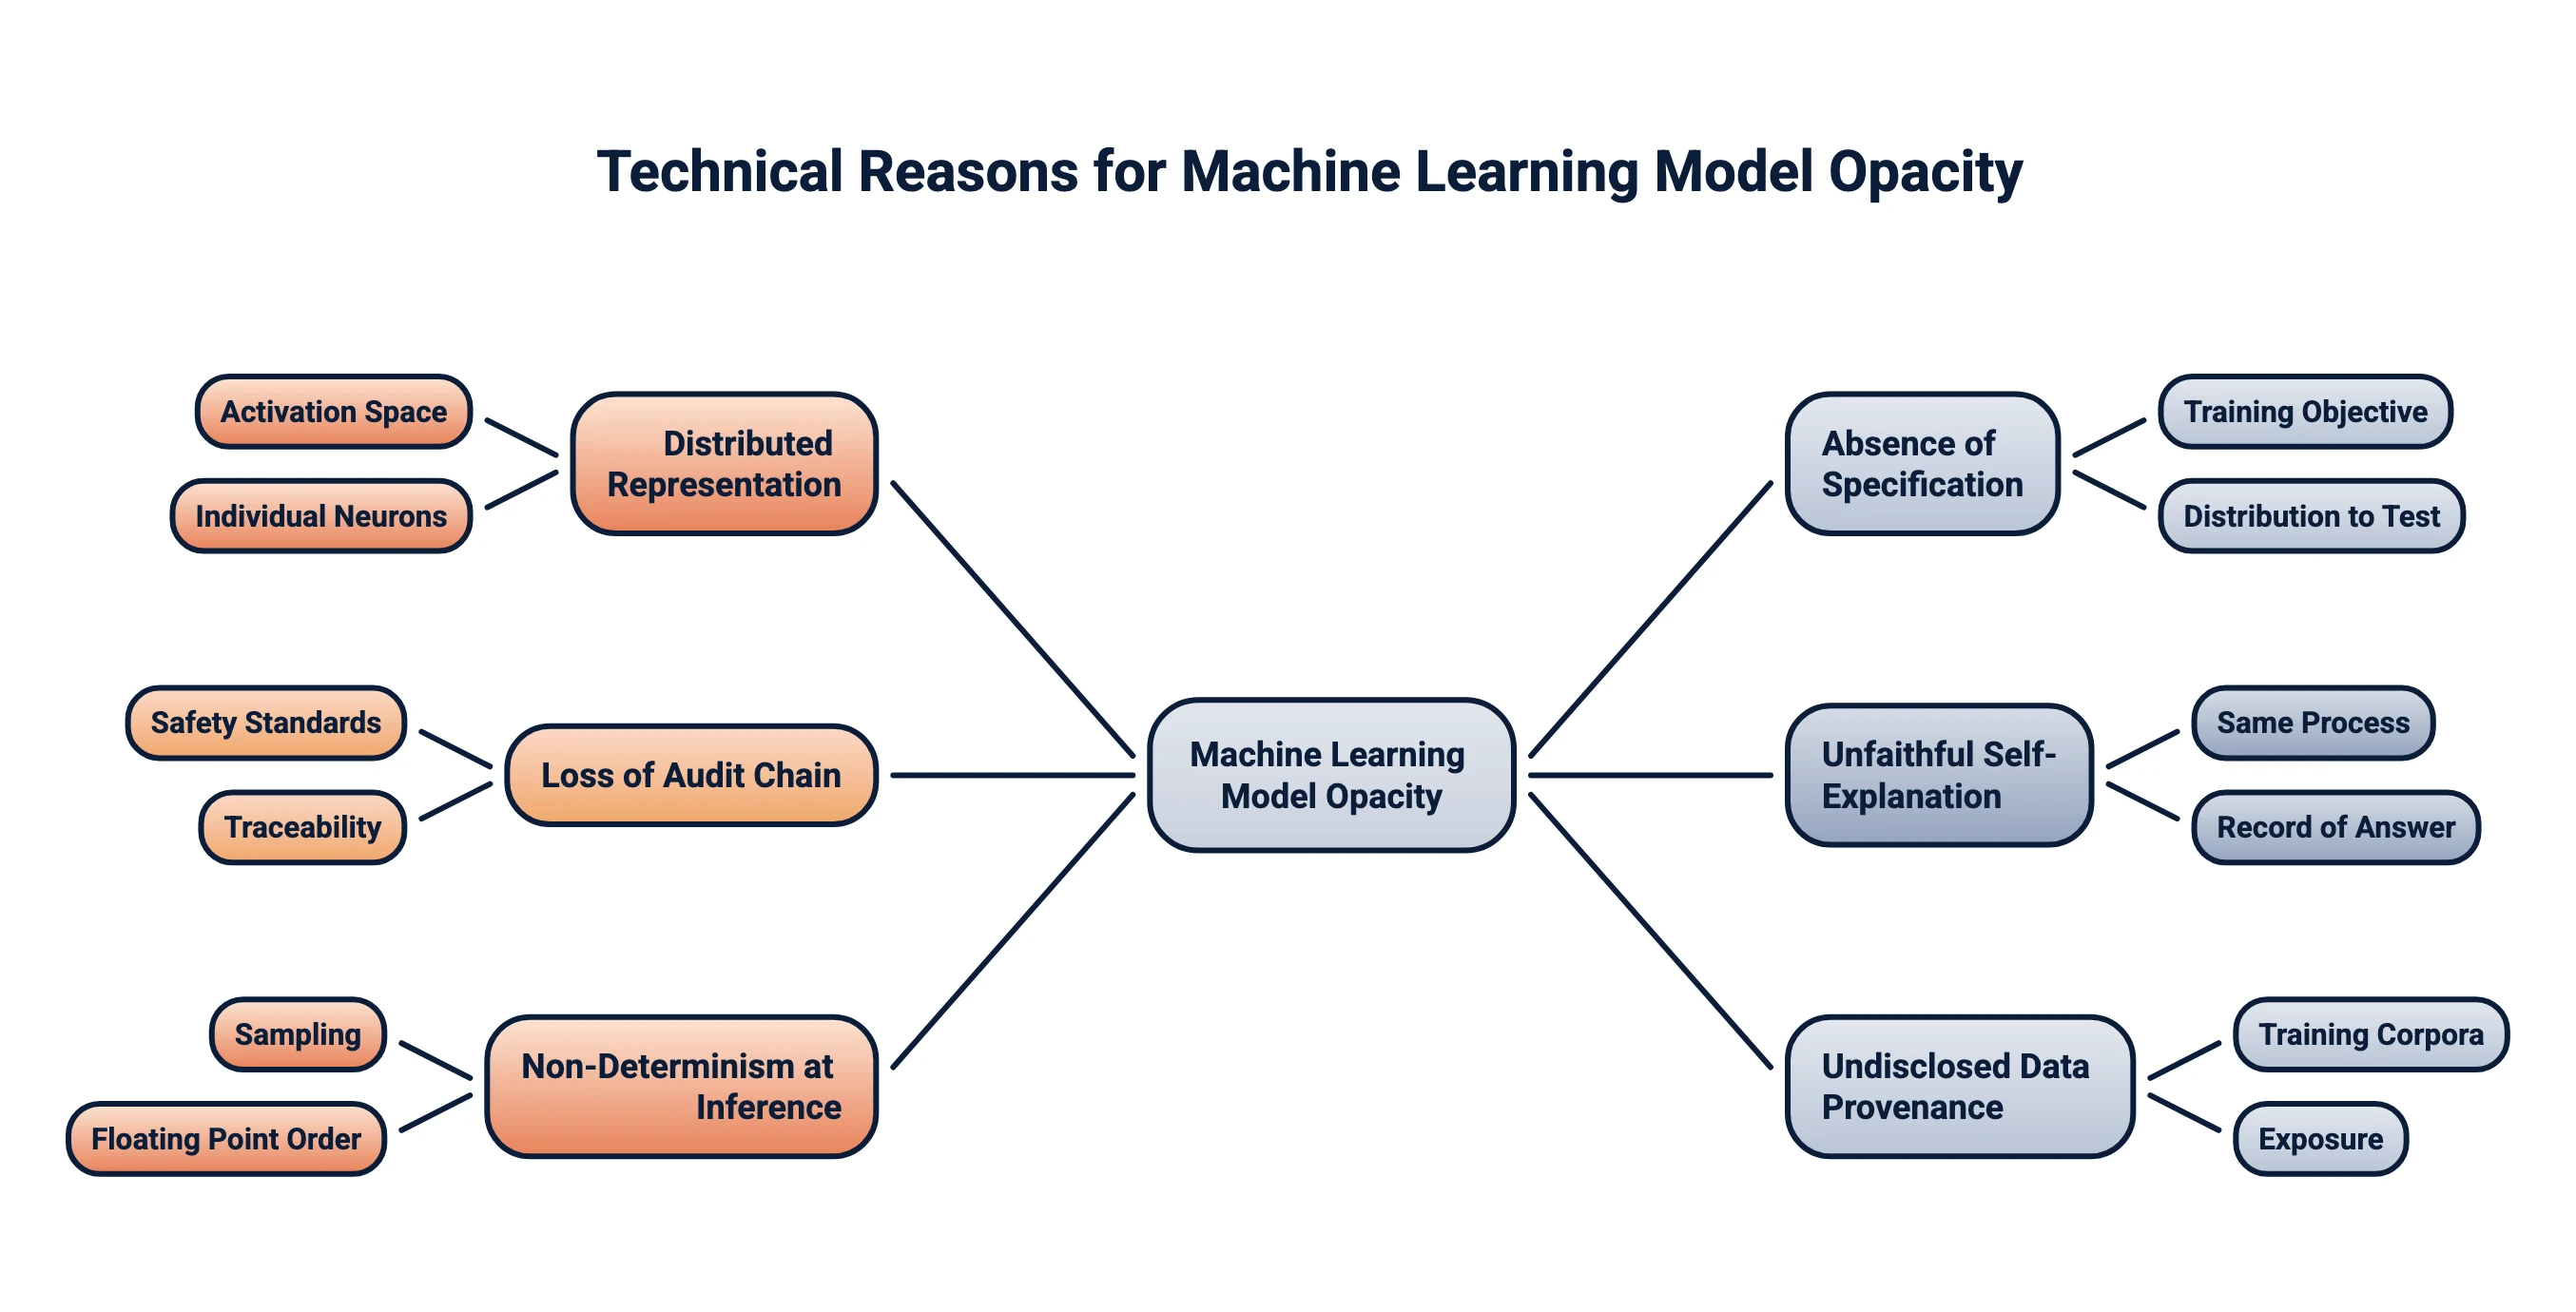
Several properties of today’s neural architectures make opacity a structural result.
Distributed representation and superposition. Individual neurons do not map to individual concepts. Anthropic’s 2022 work on toy models of superposition showed that networks routinely encode more distinct features than they have dimensions, storing them as overlapping directions in activation space. A single unit therefore takes part in many unrelated computations, a property called polysemanticity. Inspecting individual components tells you little, because the relevant unit of computation is a direction in a high-dimensional space, not a neuron.
Absence of a specification. Conventional software can be traced from requirement to implementation. A machine learning model has no breakdown of requirements. It has a training objective, a dataset, and an optimisation procedure. Nobody specified the behaviours that emerge, and nobody has listed them anywhere. There is no document to verify the model against, only a distribution to test it against.
Loss of the audit chain. Safety standards used in infrastructure, including IEC 61508, ISO 26262, EN 50128 and DO-178C, assume traceability in both directions between hazard analysis, requirements, design, and code. Learned components break this chain at the design stage. EASA’s concept paper on machine learning in aviation responds by replacing the conventional V-model with a W-shaped “learning assurance” process, in which data management and model training get assurance activities of their own. The University of York’s AMLAS methodology takes a similar approach for autonomous systems. It builds the argument as a set of explicit assurance claims about data, model, and deployment context.
Unfaithful self-explanation. Language models will produce a rationale for an output if asked. The same process that generated the output generates that rationale, and it is not a record of how the output was made. Turpin and colleagues showed in 2023 that chain-of-thought traces can systematically leave out the factor that decided the answer. When the prompt contained a biasing cue, models changed their answers to match it, while giving reasoning that never mentioned the cue. A fluent explanation is evidence of fluency, not of faithfulness.
Non-determinism at inference. Sampling temperature, floating-point non-associativity, and batch-dependent kernel reduction order can all make the same input produce different outputs on different runs or under different server loads. To reproduce an incident you therefore need the input, the model version, the sampling parameters, and in some cases the serving configuration. Few production logging schemes capture all four.
Data provenance. Training corpora for general-purpose models are large, mixed, and usually undisclosed. A deployer cannot know what the model was exposed to. So it cannot bound what the model may reproduce, what contamination may affect benchmark results, or which populations are underrepresented.
3. Common misconceptions
Opacity is not the same as complexity. The 2020 Ofqual grade standardisation model in England was a statistical procedure of modest complexity, and its outline was published. It still worked as a black box for the people it affected, because no candidate could reconstruct how their own circumstances led to their outcome. Approximately 39 per cent of A-level grades were adjusted downwards from centre assessment before the model was withdrawn. Simple systems deployed without a way to explain them can still be opaque in procedure.
Interpretability and explainability are not interchangeable. Interpretability means properties of the model itself that let people understand how it works, for example monotonic constraints, sparse structure, or additive decomposition. Explainability means artefacts generated after the fact about an opaque model, for example attribution scores. The first is a design property. The second is an approximation with its own error characteristics.
Post-hoc explanations are not audit evidence by default. Slack and colleagues showed in 2020 that LIME and SHAP can be defeated by an adversarial scaffolding classifier. It detects the perturbed inputs these methods use and returns harmless behaviour for them. Cynthia Rudin’s 2019 paper in Nature Machine Intelligence argues that explaining a black box after the fact in high-stakes settings is the wrong pattern. Where inherently interpretable models are competitive, they should be preferred. On structured tabular data, which covers a large share of public sector and infrastructure use cases, the accuracy gap is often within noise.
4. Risk categories
4.1 Assurance and safety argument
Where an opaque component sits on a path that can influence physical actuation, dispatch, or an entitlement decision, no deductive safety argument is available for that component. The argument must become statistical and behavioural, and that changes its logical status. It supports a claim about failure rate under a specified input distribution. It does not support a claim that a failure mode is impossible. If the operating distribution shifts, the argument’s premises no longer hold, and nothing in the model signals that this has happened.
4.2 Silent failure
Neural networks are poorly calibrated and get substantially worse under distributional shift. Guo and colleagues documented systematic overconfidence in modern networks in 2017. Ovadia and colleagues showed in 2019 that calibration gets worse as shift increases, while confidence scores stay high. In practice, a model that has begun to fail does not report that it has begun to fail. Detection depends entirely on instrumentation outside the model.
Free tool
AI Model Performance & Health Dashboard
The instrumentation this section argues for: drift detection, latency and uptime, and incident tracking, so a model that has begun to fail is caught from outside.
4.3 Root cause analysis and recurrence
After an incident, engineers debug a conventional system by finding the logic responsible. In an opaque model there is no logic to find. The fix is usually to retrain with more data, an empirical step whose link to the failure mode has not been verified. The organisation cannot show that the specific fault has gone, only that it no longer reproduces on the test cases it has.
4.4 Security
Data poisoning and backdoor insertion produce models that behave correctly on all inputs except those containing a trigger. Gu and colleagues demonstrated this in the BadNets work in 2017. Anthropic’s 2024 sleeper agents study found that backdoored behaviours survived supervised fine-tuning, reinforcement learning, and adversarial training. In some cases adversarial training made the model better at recognising its trigger instead of removing the behaviour. Inspecting the weights does not reveal the backdoor. Behavioural testing does not reveal it unless the trigger is known.
4.5 Legal and regulatory exposure
Explanation duties do not ease because the model is opaque. In Dun & Bradstreet Austria (C-203/22, 27 February 2025) the Court of Justice of the European Union ruled on Article 15(1)(h) GDPR, which requires meaningful information about the logic involved. It held that supplying a complex algorithmic description does not meet that obligation. The information must let the data subject understand and contest the decision.
In the United Kingdom, section 80 of the Data (Use and Access) Act 2025 replaced Article 22 UK GDPR with Articles 22A to 22D, commenced on 5 February 2026 by SI 2026/82. The old near-prohibition on solely automated significant decisions has gone. For ordinary personal data, it has been replaced by a permission that depends on safeguards: information about the decision, the ability to make representations, human intervention, and a route to contest. The compliance question used to be whether an exception applies. It is now whether you can show the safeguards are working, which is a question of engineering and logging rather than legal drafting.
In the European Union, Regulation (EU) 2026/1744, the Digital Omnibus on AI, was published in the Official Journal on 24 July 2026 and entered into force on 27 July 2026. It pushed back the compliance date for standalone high-risk systems under Annex III, which includes critical infrastructure, to 2 December 2027. For high-risk AI embedded in products regulated under Annex I, the new date is 2 August 2028. The Article 50 transparency obligations were not deferred and applied from 2 August 2026, with a limited extension to 2 December 2026 for marking content generated by systems already on the market. The underlying obligations have not changed. They cover risk management, data governance, technical documentation, human oversight, and post-market monitoring. The deferral affects the deadline, not the design work.
4.6 Accountability and public trust
The Dutch childcare benefits case shows how the harm compounds. A risk classification system run by the Tax and Customs Administration flagged approximately 26,000 families for fraud investigation on grounds the families could not see or challenge, and it used nationality as a risk indicator. Over a thousand children were removed from their homes. The Dutch Data Protection Authority imposed fines in 2021 and 2022, and the Cabinet resigned in January 2021. Separately, in NJCM v The Netherlands (District Court of The Hague, 5 February 2020), the court held that the SyRI welfare fraud detection system breached Article 8 of the European Convention on Human Rights. Its reasoning rested substantially on the absence of verifiable information about the risk model.
4.7 Automation bias
Where an operator cannot judge the basis for a recommendation, oversight tends to slide towards approval by default. Human review that cannot in practice disagree is not a control. Article 14 of the EU AI Act requires that oversight be capable of being exercised. The same expectation is implicit in the Article 22C safeguards under the UK regime. A design that presents a recommendation without contrastive information, confidence, or a way to disagree will not meet this in substance, whatever the process documentation says.
Free tool
Board AI Oversight Checklist
Automation bias in practice: whether your board can name who is accountable when a human reviewer cannot, in fact, disagree with the opaque model’s recommendation.
4.8 Supply chain and version drift
Hosted models are updated by the provider. Behaviour can change without notice, without a version number change the deployer can see, and without any change to the deployer’s own code. Acceptance testing done at procurement describes a model that may no longer be the one in service.
5. Documented commercial impact
- Zillow Offers. Zillow used automated valuation to price home purchases. It performed acceptably during a stable period and failed when market conditions changed. Zillow recorded an inventory write-down of approximately US$304 million in Q3 2021, announced on 2 November 2021 that it was closing the business line, and cut headcount by around 25 per cent.
- Moffatt v Air Canada (2024 BCCRT 149, 14 February 2024). The British Columbia Civil Resolution Tribunal held the airline liable for incorrect information given by its customer service chatbot. The tribunal rejected the argument that the chatbot’s outputs could be separated from the operator’s own representations.
- Apple Card. After allegations of gender-based disparity in credit limits, the New York Department of Financial Services concluded in March 2021 that it had not found unlawful discrimination. It did criticise the issuer for being unable to explain individual outcomes to customers. The reputational cost was incurred during the period when no explanation could be produced.
6. Mitigation
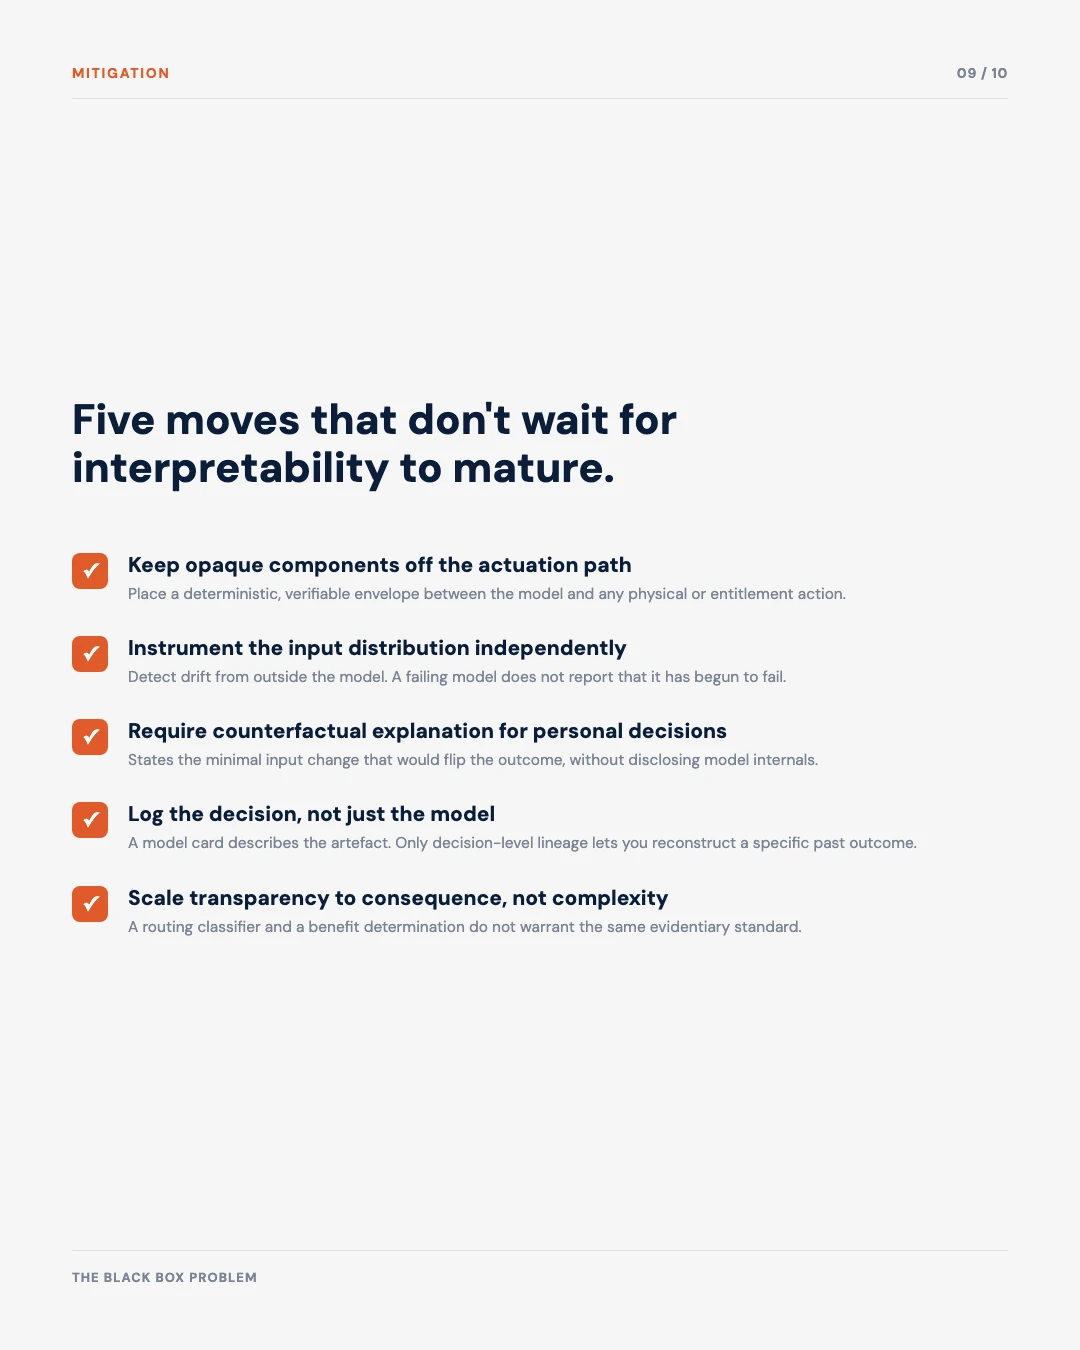
No single measure solves the problem. The workable position is to rely less on model transparency, by limiting what the model is allowed to decide, and to instrument the surrounding system so that failure is detected from outside.
6.1 Model selection
Make interpretability a requirement, and require a justification when it is not met. For tabular problems, several model types are often competitive: generalised additive models, explainable boosting machines, monotonic gradient-boosted trees with enforced constraints, sparse decision lists, and risk scorecards. Monotonicity constraints are especially useful in regulated decisions because they encode a policy statement you can defend, for example that higher arrears may not reduce assessed risk. The constraint holds by construction, not by observation.
6.2 Architectural containment
Keep opaque components off the actuation path. Where a model informs a control action, put a deterministic envelope that can be verified independently between the model and the plant. The envelope holds rate limits, physical bounds derived from first principles, interlocks, and reversion to a conventional controller if a bound is violated. The assurance argument then attaches to the envelope, which conventional methods can verify, rather than to the model. Control barrier functions and reachability-based supervisors give formal versions of this where the plant model supports them.
6.3 Uncertainty quantification and abstention
Conformal prediction gives distribution-free coverage guarantees under exchangeability and works with any underlying model. It produces prediction sets with a specified error rate instead of a single point estimate. Combined with a calibrated abstention threshold, it turns an opaque predictor into a system with a defined, measurable escalation rate. Report expected calibration error and coverage for each operational slice, not in aggregate.
6.4 Out-of-distribution detection
Instrument the input distribution independently of the model’s confidence output. Several measures give a signal that does not come from the same computation that makes the prediction: Mahalanobis distance in feature space, energy-based scores, and population stability index or Kolmogorov-Smirnov statistics on input features. This tackles the silent failure mode directly.
6.5 Behavioural assurance
Where structural verification is not possible, strengthen the behavioural evidence. Use metamorphic testing against invariants that must hold whatever the model’s internals. Use slice-based evaluation with a performance floor for each slice. Run adversarial and red-team evaluation with documented coverage. And before cutover, run a shadow deployment against the current process and measure how often the two disagree.
6.6 Interpretability tooling, with calibrated expectations
Mechanistic interpretability has advanced materially. Sparse autoencoders break polysemantic activations into higher-dimensional sparse feature dictionaries, and attribution graphs trace causal paths between those features. MIT Technology Review listed the field among its breakthrough technologies for 2026, and DeepMind’s Gemma Scope 2 extended sparse autoencoder analysis to models of 27 billion parameters.
The limits are just as well documented, and any assurance case that relies on these methods should state them plainly. Anthropic’s circuit tracing work on Claude 3.5 Haiku produced satisfying explanations for roughly a quarter of the prompts examined. DeepMind’s interpretability team published negative results on downstream sparse autoencoder applications in March 2025 and deprioritised that line of work. Sparse autoencoders trained on the same data learn different feature sets from run to run, a substantial obstacle to using them as audit evidence. Dead-feature rates above 70 per cent have been reported on some models. The January 2025 open problems paper, assembled by 29 researchers across 18 organisations, records that a number of interpretability queries are formally intractable. These tools are useful for investigation and for debugging models. They do not currently count as a compliance artefact.
6.7 Counterfactual explanation for individual decisions
Where a decision affects a person, a counterfactual explanation states the smallest change in inputs that would have produced a different outcome. The person can act on it, it needs no disclosure of model internals, and it maps directly onto the contestability requirement in Article 22C(2) and the reasoning in Dun & Bradstreet. Check that the counterfactual is feasible, that it does not require changing attributes that cannot change, and that it holds steady under small changes to the input.
6.8 Documentation, provenance, and decision-level lineage
Publishing a description of a tool is a lower standard than being able to reconstruct a specific past decision. The difference matters when a decision is challenged years after it was made. Keep a record for each decision. It should hold the input payload, model identifier and weight hash, prompt or feature vector version, sampling parameters, output, confidence or conformal set, any human intervention, and the identity of the officer who intervened. Model cards and datasheets for datasets cover the artefact level. They do not cover the decision level.
In the United Kingdom, the Algorithmic Transparency Recording Standard is mandatory for central government departments and for arm’s-length bodies delivering public or frontline services. This follows the scope and exemptions policy published in December 2024, and more than 120 records are now published. It should be treated as a disclosure floor.
Free tool
AI Trust, Risk & Governance Dashboard
Bias and fairness, data lineage, LLM security, and access-control posture against industry-standard thresholds, the four domains a decision-level lineage record has to cover.
6.9 Governance and procurement
ISO/IEC 42001:2023 provides a certifiable management system for AI. ISO/IEC 23894 addresses risk management, and the NIST AI Risk Management Framework provides the govern, map, measure, and manage structure. These set process discipline. They do not by themselves produce evidence about a specific model.
Procurement terms should cover five things. The first is the right to be notified and to re-accept when the model is updated. The others are a performance floor for each slice with defined remedies, retention and disclosure of evaluation artefacts, a right of independent audit, and who bears liability for erroneous outputs. Where a hosted general-purpose model is used, pin to a versioned endpoint. Treat updates the provider starts as change events that need regression testing.
7. Proportionality
Transparency requirements should scale with consequence, not with model complexity.
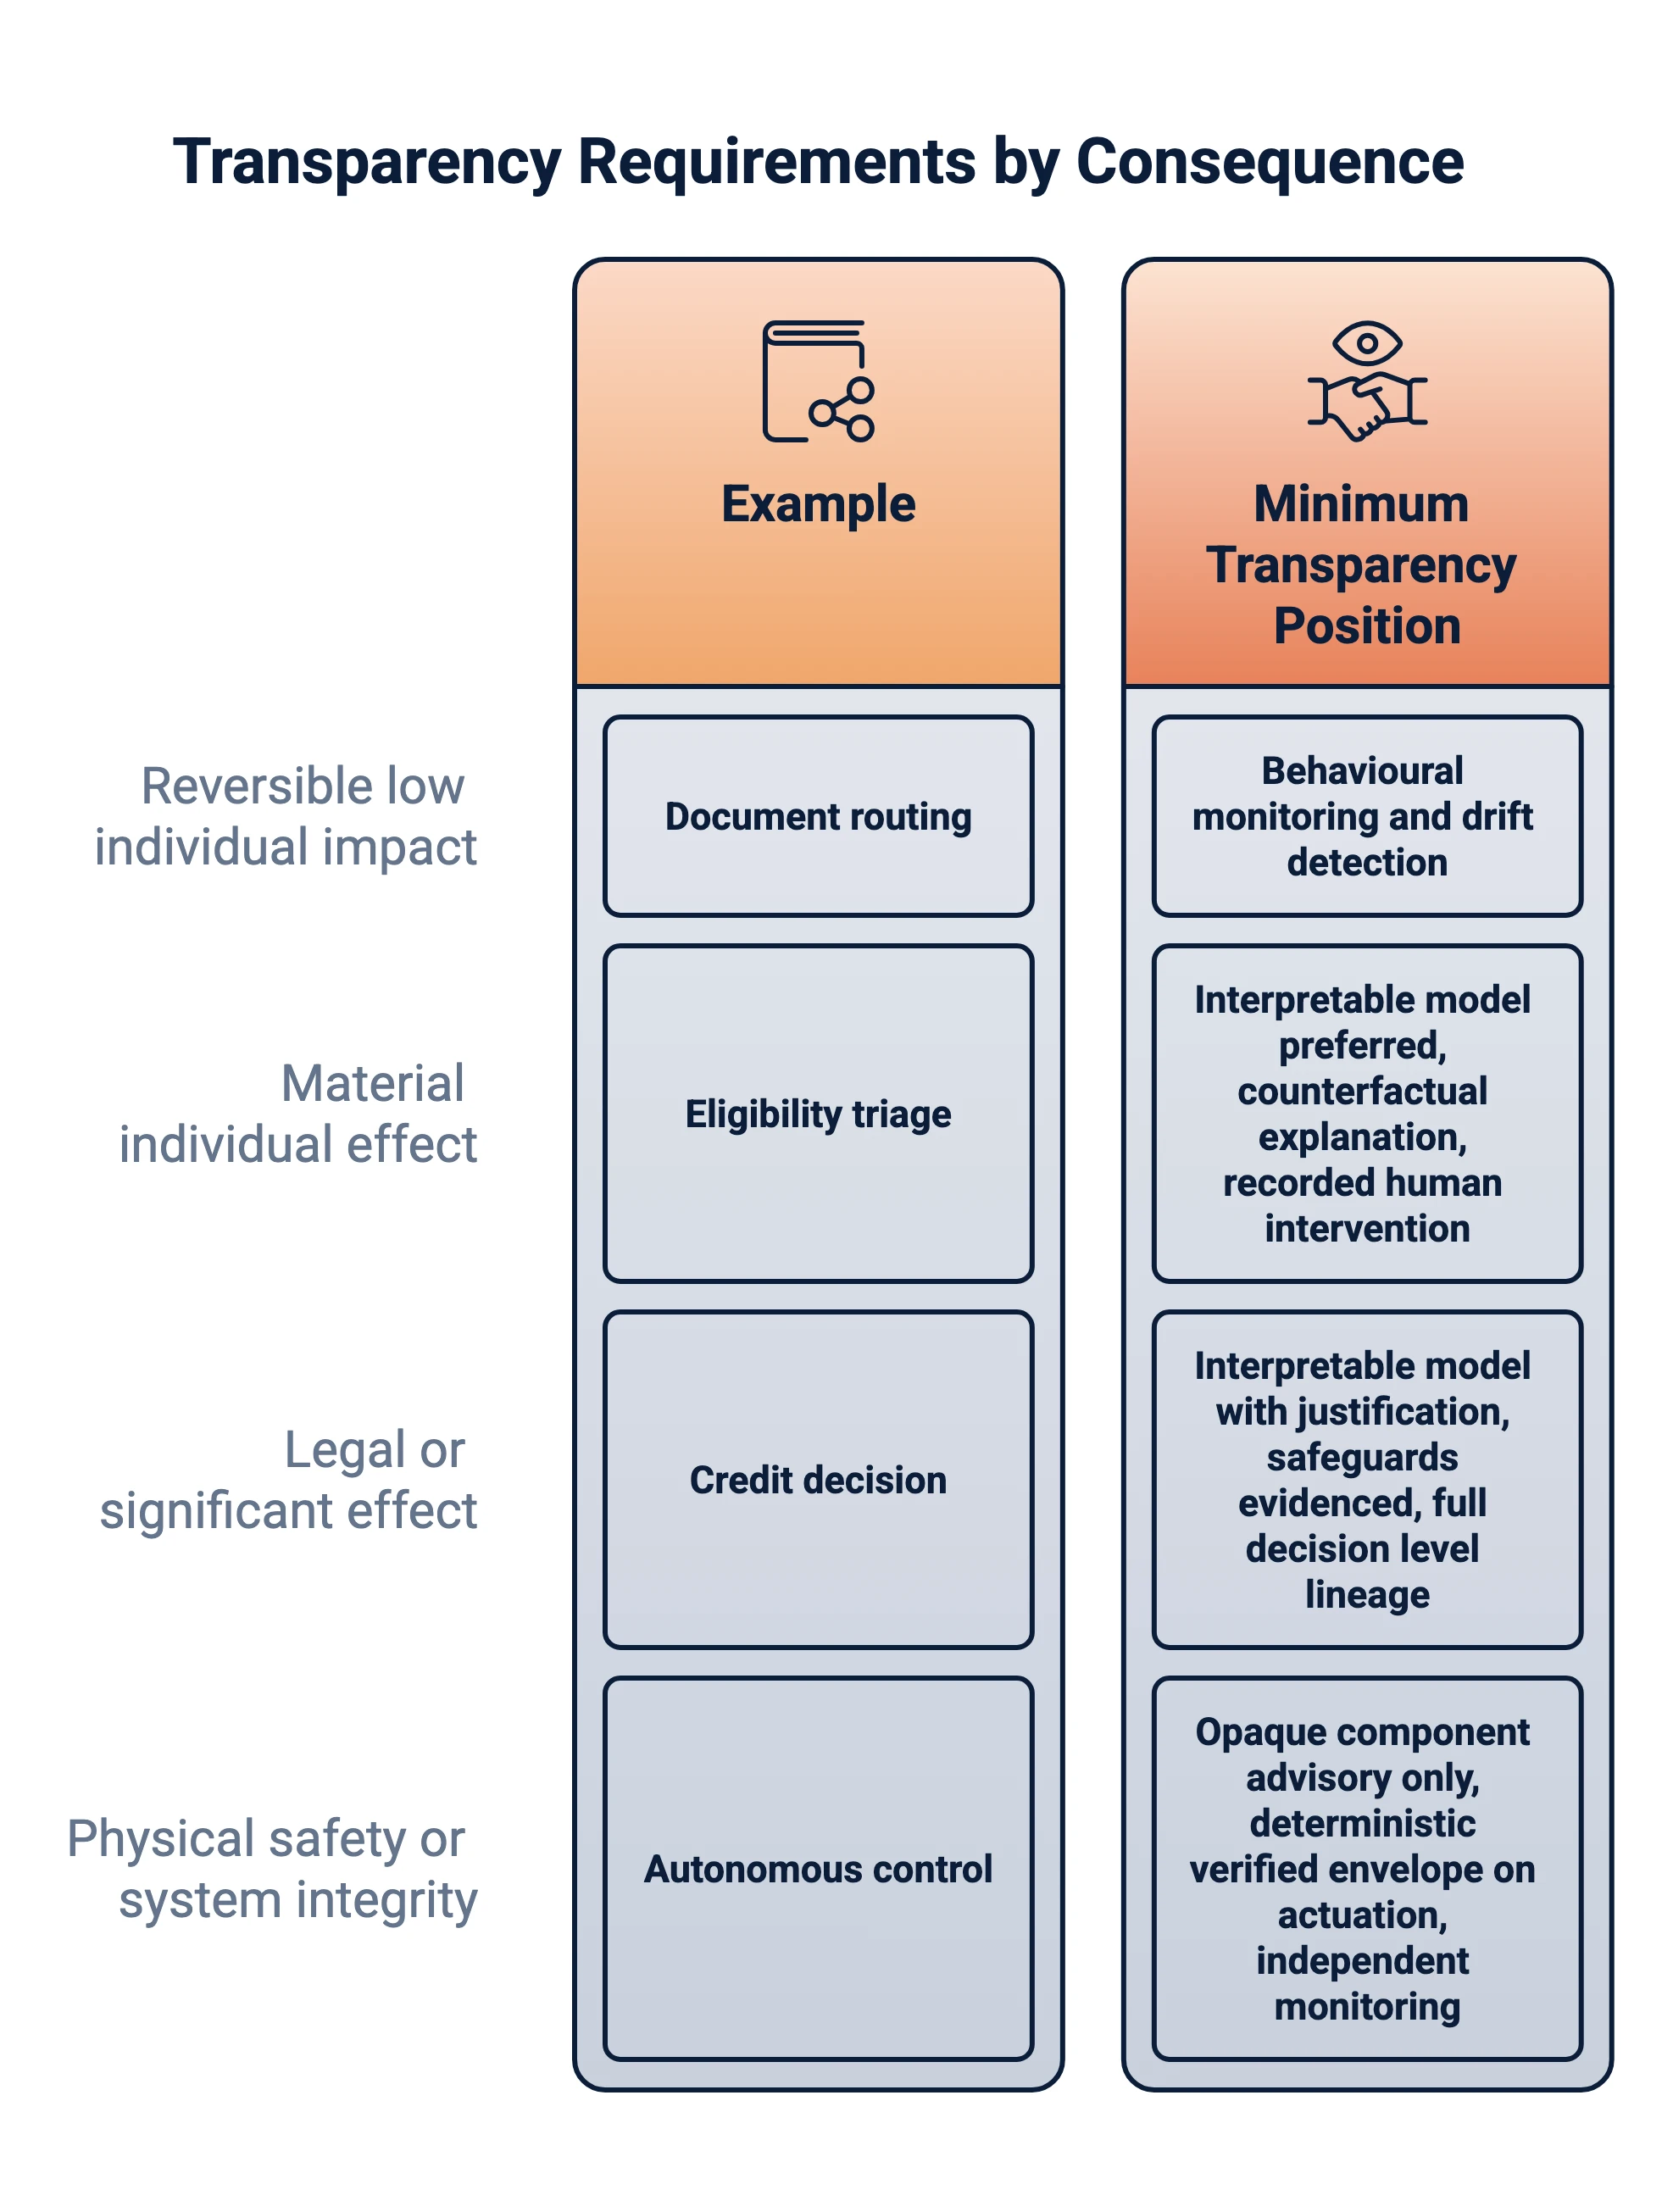
| Consequence class | Example | Minimum position |
|---|---|---|
| Reversible, low individual impact | Document classification for routing, internal search ranking | Behavioural monitoring, drift detection, sampled quality review |
| Material individual effect | Eligibility triage, priority ordering for inspection or service | Interpretable model preferred; counterfactual explanation; recorded human intervention; per-slice fairness testing |
| Legal or similarly significant effect | Benefit determination, enforcement referral, credit decision | Interpretable model with justification if not; Article 22C safeguards evidenced; full decision-level lineage |
| Physical safety or system integrity | Protection settings, dispatch, autonomous control | Opaque component advisory only; deterministic verified envelope on actuation; independent OOD monitoring; documented reversion mode |
8. Residual limits
Full mechanistic explanation of frontier-scale models is not available. No programme plan should assume it as a near-term dependency. The right engineering stance is to design systems whose assurance argument does not need it. That means placing opaque components where their failure is bounded, detected, and recoverable, and keeping unbounded reliance for components that conventional methods can verify.
For the deploying organisation, then, the black box problem is not mainly a research problem. It is a systems architecture problem. The decisions that set exposure are made at the point where the model’s authority within the system is defined.
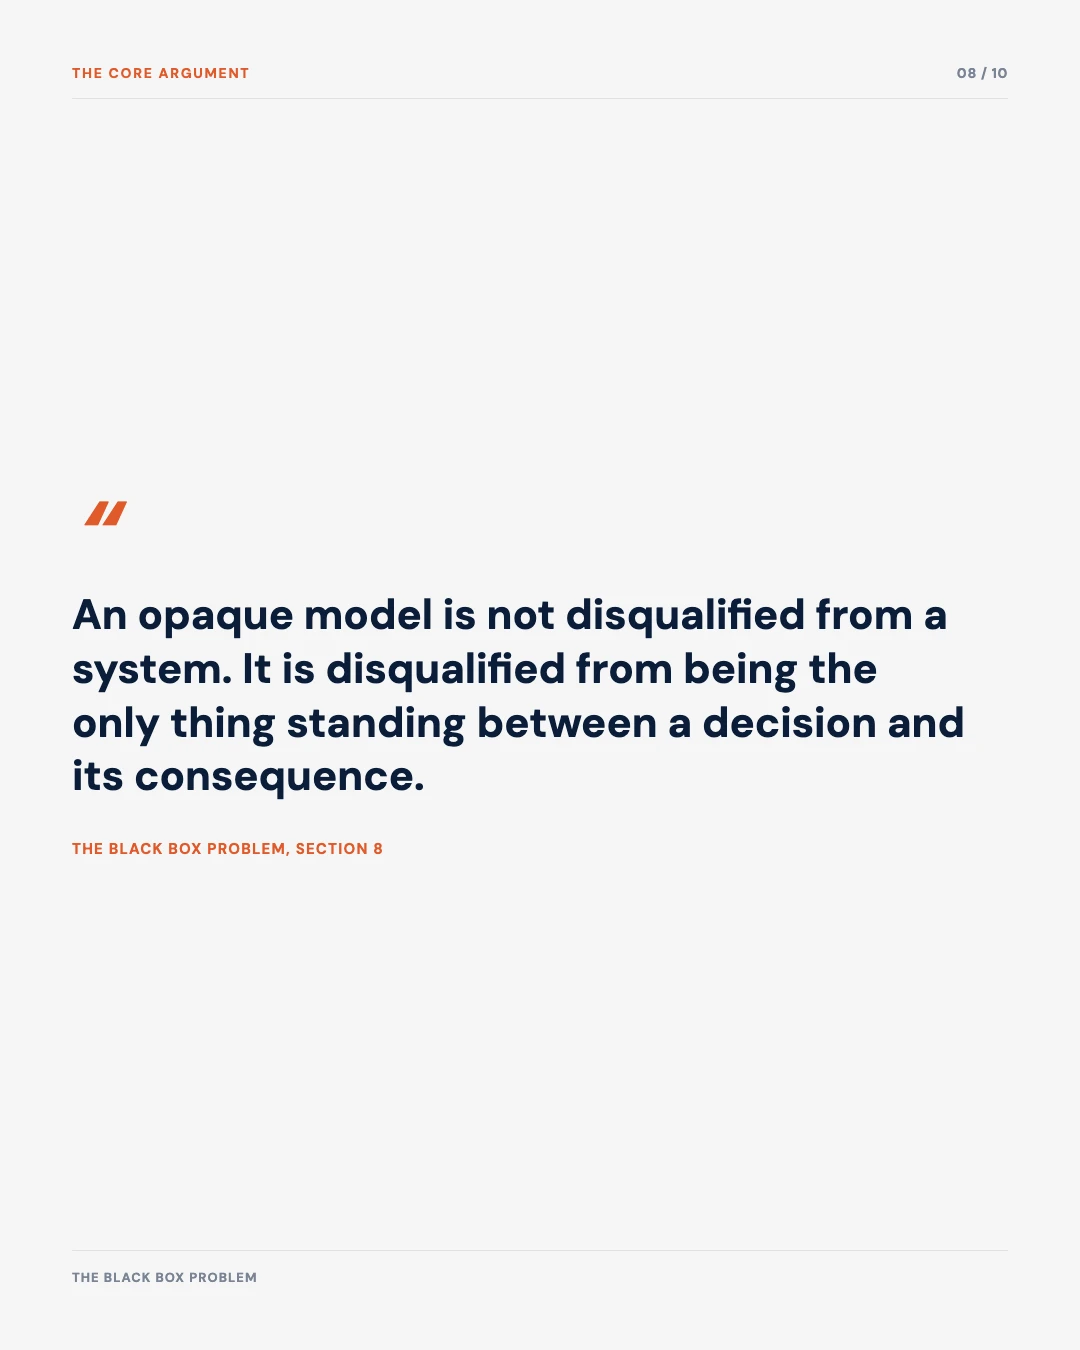
An opaque model is not disqualified from a system. It is disqualified from being the only thing standing between a decision and its consequence.
Evidence & Methodology
Not every number below is doing the same job. One is Anthropic’s own measurement of the limits of its best interpretability tooling. One is a company’s disclosed financial loss. One is an academic taxonomy I’m relying on, not testing. The last is my own engineering call.
| Claim | Source | Grade |
|---|---|---|
| Anthropic’s circuit tracing produced a satisfying explanation for roughly 25% of prompts examined on Claude 3.5 Haiku | Anthropic’s own published interpretability research | Measured |
| Zillow recorded a roughly US$304 million inventory write-down after its valuation model failed under changed market conditions | Zillow’s Q3 2021 financial disclosure | Documented |
| Opacity by construction, not withheld disclosure, is the substantive problem | Jenna Burrell’s 2016 taxonomy, Big Data & Society | Framework |
| The workable response is architectural containment: keep opaque components off the actuation path rather than wait for interpretability to mature | My own engineering recommendation, built on the state of interpretability research above | My call |
Sources
- Burrell, J. (2016). How the machine “thinks”: Understanding opacity in machine learning algorithms. Big Data & Society, 3(1).
- Rudin, C. (2019). Stop explaining black box machine learning models for high stakes decisions and use interpretable models instead. Nature Machine Intelligence, 1.
- Slack, D., et al. (2020). Fooling LIME and SHAP: Adversarial attacks on post hoc explanation methods. AIES 2020.
- Turpin, M., et al. (2023). Language models don’t always say what they think: Unfaithful explanations in chain-of-thought prompting. NeurIPS 2023.
- Elhage, N., et al. (2022). Toy models of superposition. Transformer Circuits Thread.
- Templeton, A., et al. (2024). Scaling monosemanticity: Extracting interpretable features from Claude 3 Sonnet. Transformer Circuits Thread.
- Hubinger, E., et al. Sleeper agents: Training deceptive LLMs that persist through safety training. arXiv:2401.05566.
- Gu, T., et al. BadNets: Identifying vulnerabilities in the machine learning model supply chain. arXiv:1708.06733.
- Guo, C., et al. (2017). On calibration of modern neural networks. ICML 2017.
- Ovadia, Y., et al. (2019). Can you trust your model’s uncertainty? Evaluating predictive uncertainty under dataset shift. NeurIPS 2019.
- Wachter, S., Mittelstadt, B., & Russell, C. (2018). Counterfactual explanations without opening the black box. Harvard Journal of Law & Technology, 31(2).
- Mitchell, M., et al. (2019). Model cards for model reporting. FAT* 2019.
- Gebru, T., et al. (2021). Datasheets for datasets. Communications of the ACM, 64(12).
- Case C-203/22, CK v Dun & Bradstreet Austria GmbH, CJEU judgment of 27 February 2025.
- NJCM et al. v The Netherlands (SyRI), District Court of The Hague, 5 February 2020, ECLI:NL:RBDHA:2020:1878.
- Moffatt v Air Canada, 2024 BCCRT 149.
- UK Parliament. (2025). Data (Use and Access) Act 2025, section 80.
- Council of the European Union. (2026, June 29). Regulation (EU) 2026/1744 (Digital Omnibus on AI), OJ 24 July 2026 [Press release].
- GOV.UK. (n.d.). Algorithmic Transparency Recording Standard Hub.
- ISO/IEC 42001:2023. Information technology — Artificial intelligence — Management system.
- NIST. (2023). AI 100-1: Artificial intelligence risk management framework 1.0.
- EASA. (n.d.). Artificial intelligence concept paper: Learning assurance, W-shaped process.
- Hawkins, R., et al. (n.d.). AMLAS: Assurance of Machine Learning for use in Autonomous Systems. University of York.
Was this useful?