Executive Summary
Voice AI has moved from experimental chat interfaces to production-grade infrastructure. Market researchers project the conversational AI market will more than triple in size between 2024 and 2030. What sets organisations apart now is whether they build it as an operating asset they can measure or leave it as a stand-alone pilot.
Core conclusions
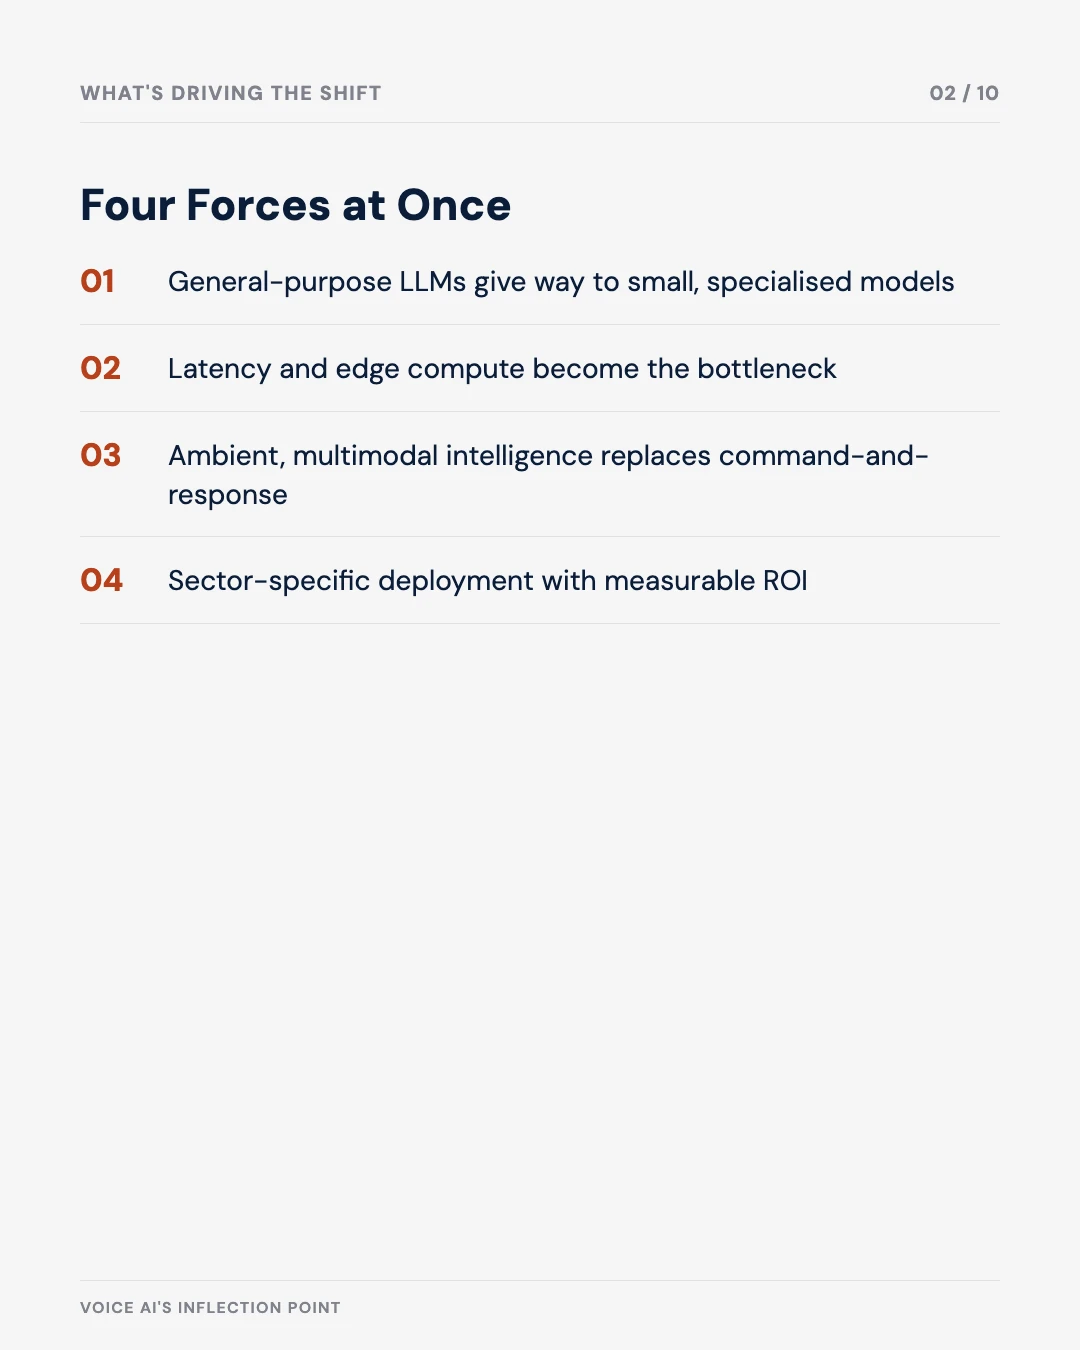
- Latency, not model quality, is what holds adoption back in practice. Human dialogue breaks down past roughly one second of delay. That pushes enterprises toward edge deployment and streaming pipelines to get response times under 100ms.
- The architecture is shifting from general-purpose LLMs to small models built for one domain. These give deterministic, auditable behaviour, which matters most in regulated sectors like healthcare and finance.
- High performers treat voice AI as one joined-up capability tied to CRMs, EHRs, and ticketing systems, with clear governance and KPIs. More and more, they treat responsible-AI guardrails as a way to lift performance.
The inflection point, in ten slides
Save it, share it, or send it to whoever owns your voice AI roadmap.
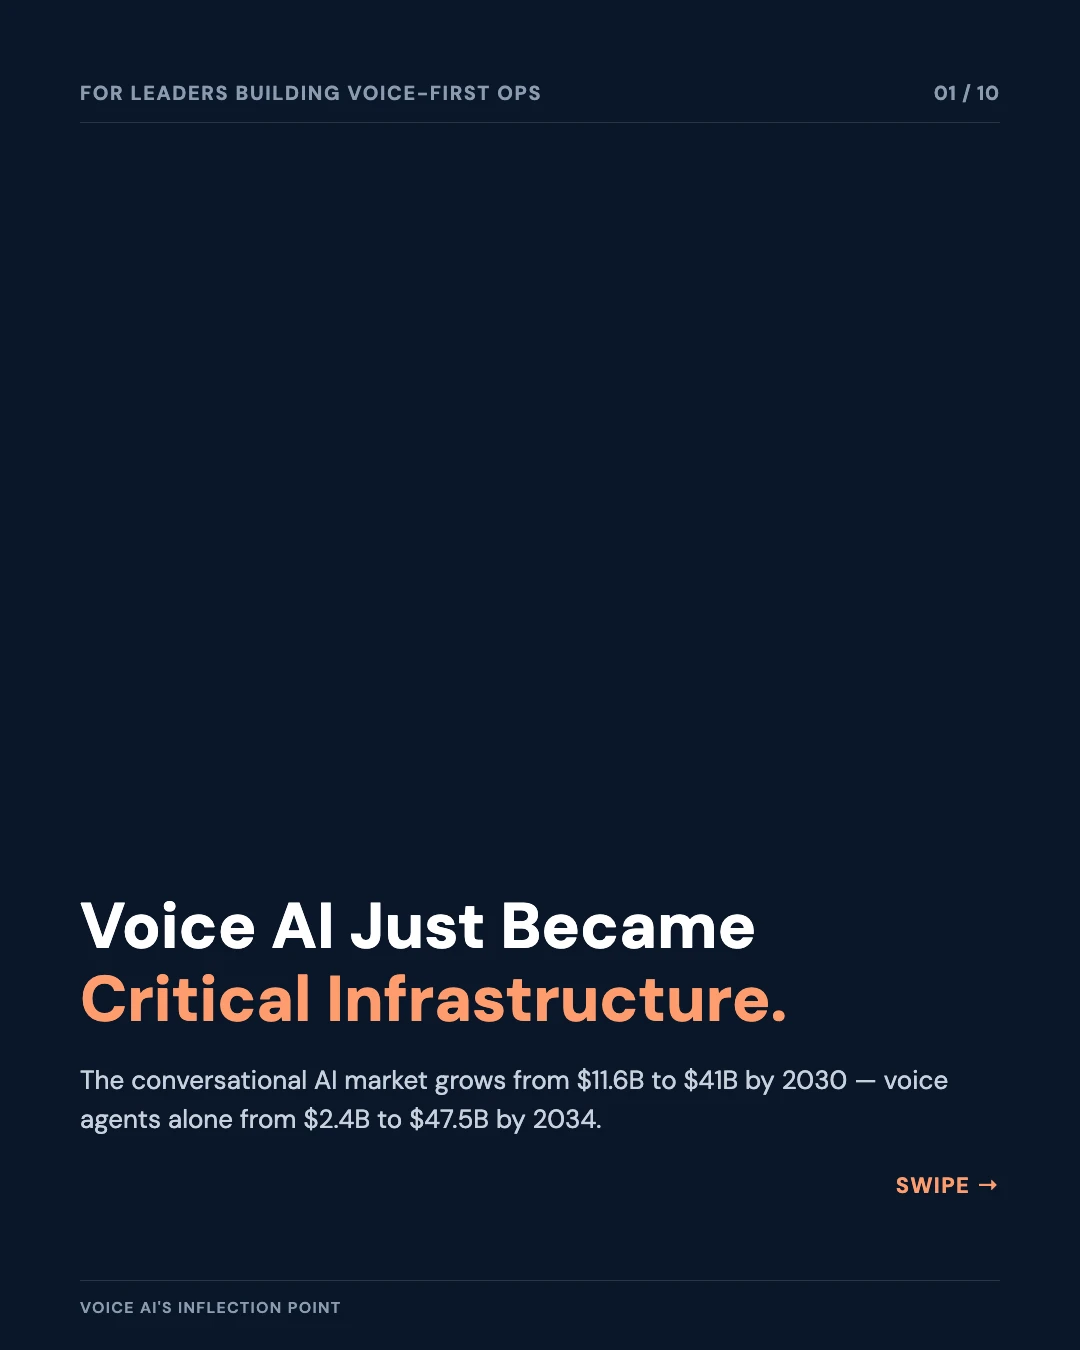
Voice AI is therefore best seen as a basic building block of the next wave of digital infrastructure. In the high-growth regions of Asia and the Middle East, many languages and dialects are spoken. There, robust voice systems that support dozens of languages and variants can widen access to government services, healthcare, and education, without copying old, siloed automation. The inflection point has already been reached. What sets organisations apart now is whether they build voice as a core operating asset they can measure, or let it stay a stand-alone experiment. 2026 marked a decisive inflection point for enterprise voice AI, as the technology moved from experimental conversational interfaces to production-grade infrastructure built into critical operations.
Global spending reflects this shift. Market researchers put the conversational AI market at well over USD 10 billion as of the mid-2020s. Most project it will more than triple by 2030, and separate estimates for voice AI agents alone point to similarly steep growth over several years. This is a structural change in how organisations design the way people and machines interact.
Forward-looking enterprises are moving past consumer assistants such as Siri and Alexa. They are putting voice AI where revenue and safety are at stake. A handful of numbers show the scale of that shift:
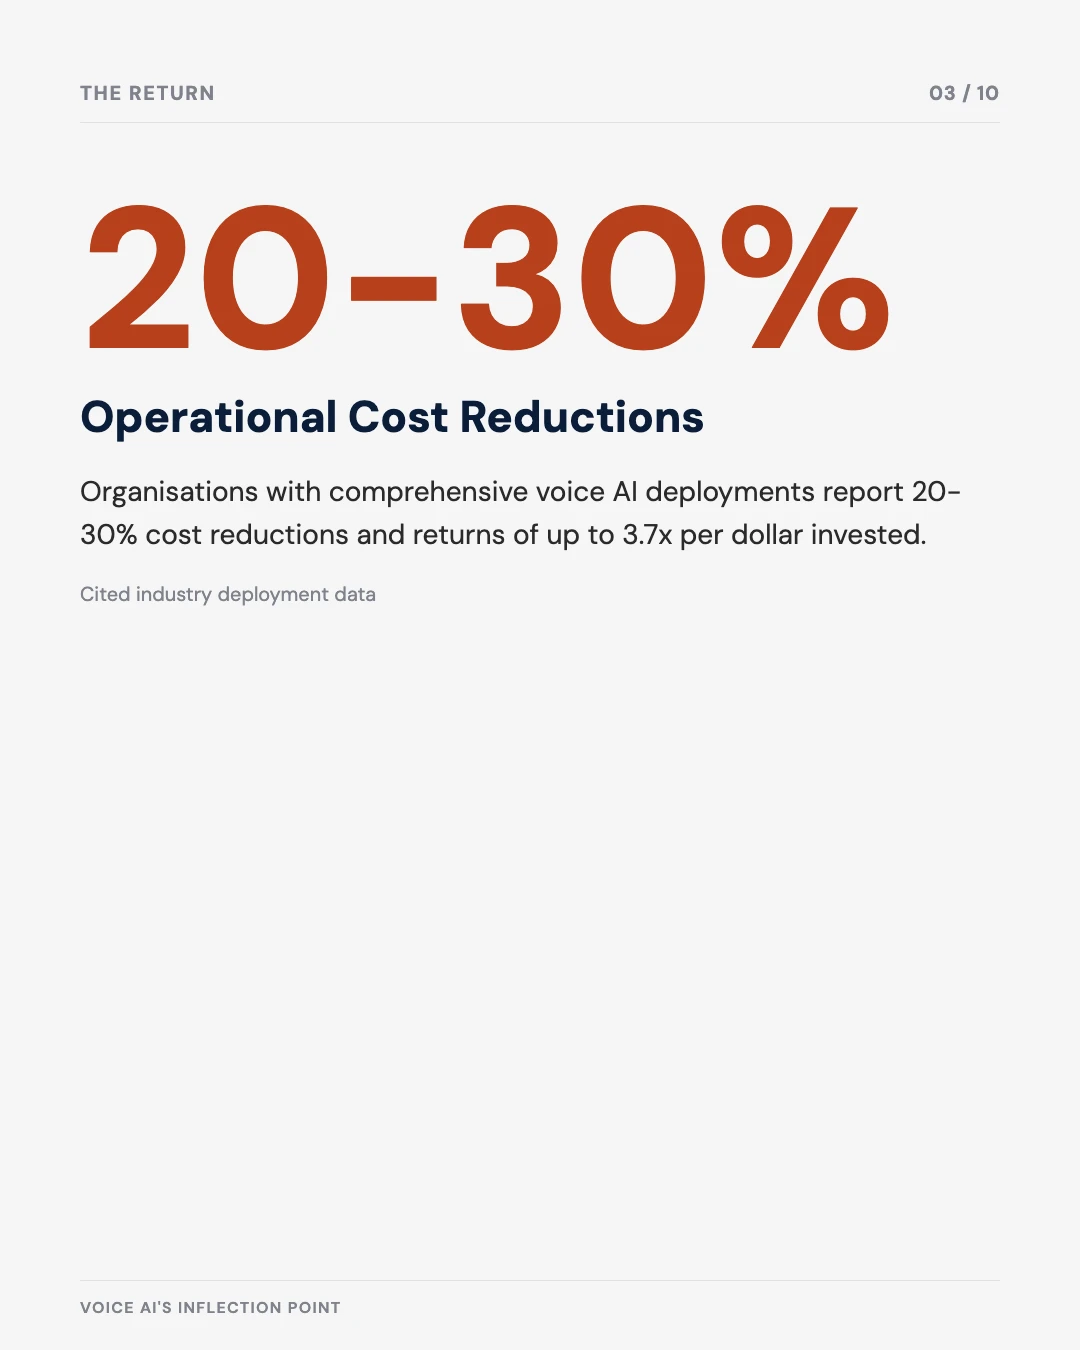
- Organisations that report full-scale deployments achieve 20–30% cuts in operating costs and returns of up to 3.7x per dollar invested.
- Analysts forecast that around 40% of enterprise applications will include task-specific AI agents by the end of 2026, up from single digits in 2025.
- Financial services now makes up roughly one-third of the conversational AI market. Healthcare is close behind and is projected to gain tens of billions a year in efficiency.
From general-purpose LLMs to specialised inference
Model architecture is going through a structural shift. General-purpose large language models (LLMs) with billions of parameters are proving costly to run and fragile in operation for narrow, repetitive enterprise workflows. Senior AI researchers, including Meta’s former Chief AI Scientist Yann LeCun, have argued publicly that LLMs will lose their current dominance within a few years, as more efficient, grounded architectures emerge. It is a case I’ve made in more technical detail elsewhere.
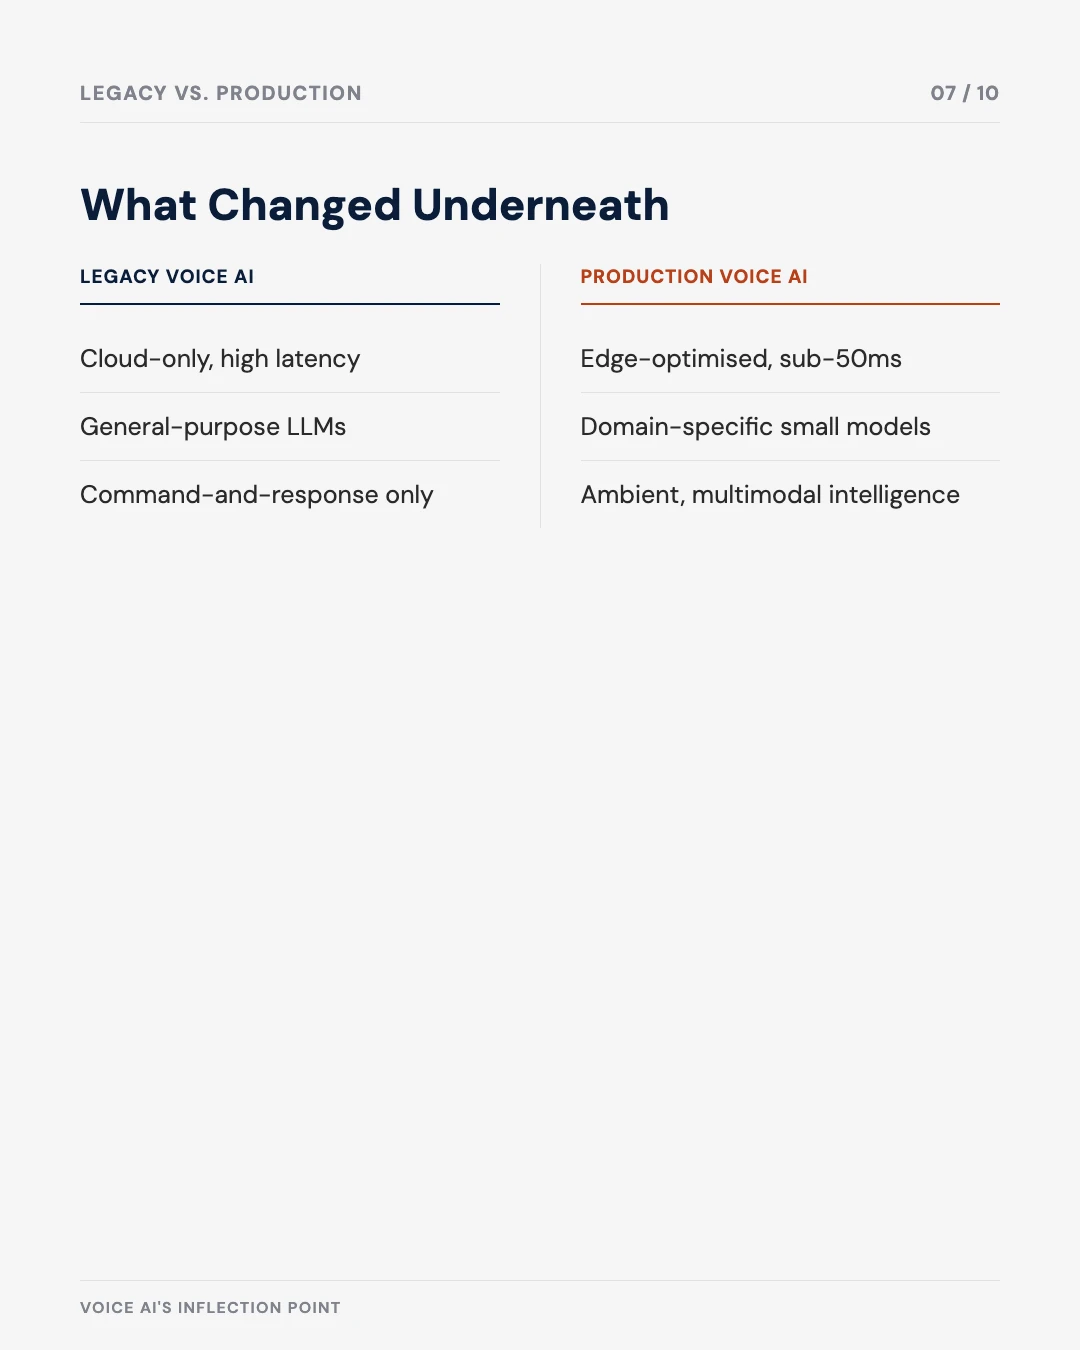
So enterprises are turning to small language models (SLMs) trained on curated data from their own domain. These models give similar task performance while using less compute. That lets them run in hybrid and on-premise environments that meet data sovereignty and regulatory requirements. For heavily regulated sectors such as healthcare and finance, deterministic behaviour (the same consistent, auditable response to the same input) is now a baseline requirement.
At the same time, world foundation models (WFMs) are taking AI beyond text. NVIDIA’s Cosmos platform offers pretrained models that simulate physical environments and generate synthetic data to train autonomous vehicles and humanoid robots. These models combine an understanding of space, vision, and time. They form the base for Physical AI systems such as Boston Dynamics’ Atlas and Tesla’s Optimus, which learn tasks by watching.
The hardware stack is changing to match. GPUs remain central to training. But inference at the edge and inside embedded systems relies more and more on application-specific integrated circuits (ASICs) such as Google’s Tensor Processing Units. These give more performance per watt and lower latency for fixed-function workloads. Companies such as Arm and Broadcom are targeting dedicated Physical AI compute. This includes emerging physics-based ASICs that compute using the dynamics of physical systems, to ease the “compute crisis” caused by rising energy demand and training cost.
Latency, edge, and ambient intelligence
Latency has become the invisible determinant of adoption. Human dialogue breaks down when responses take longer than roughly one second, so many cloud-only architectures do not suit real-time interaction. Vendors such as Cartesia report response times under 100 milliseconds for speech models, close to the threshold for natural conversation.
Latency has become the invisible determinant of adoption.
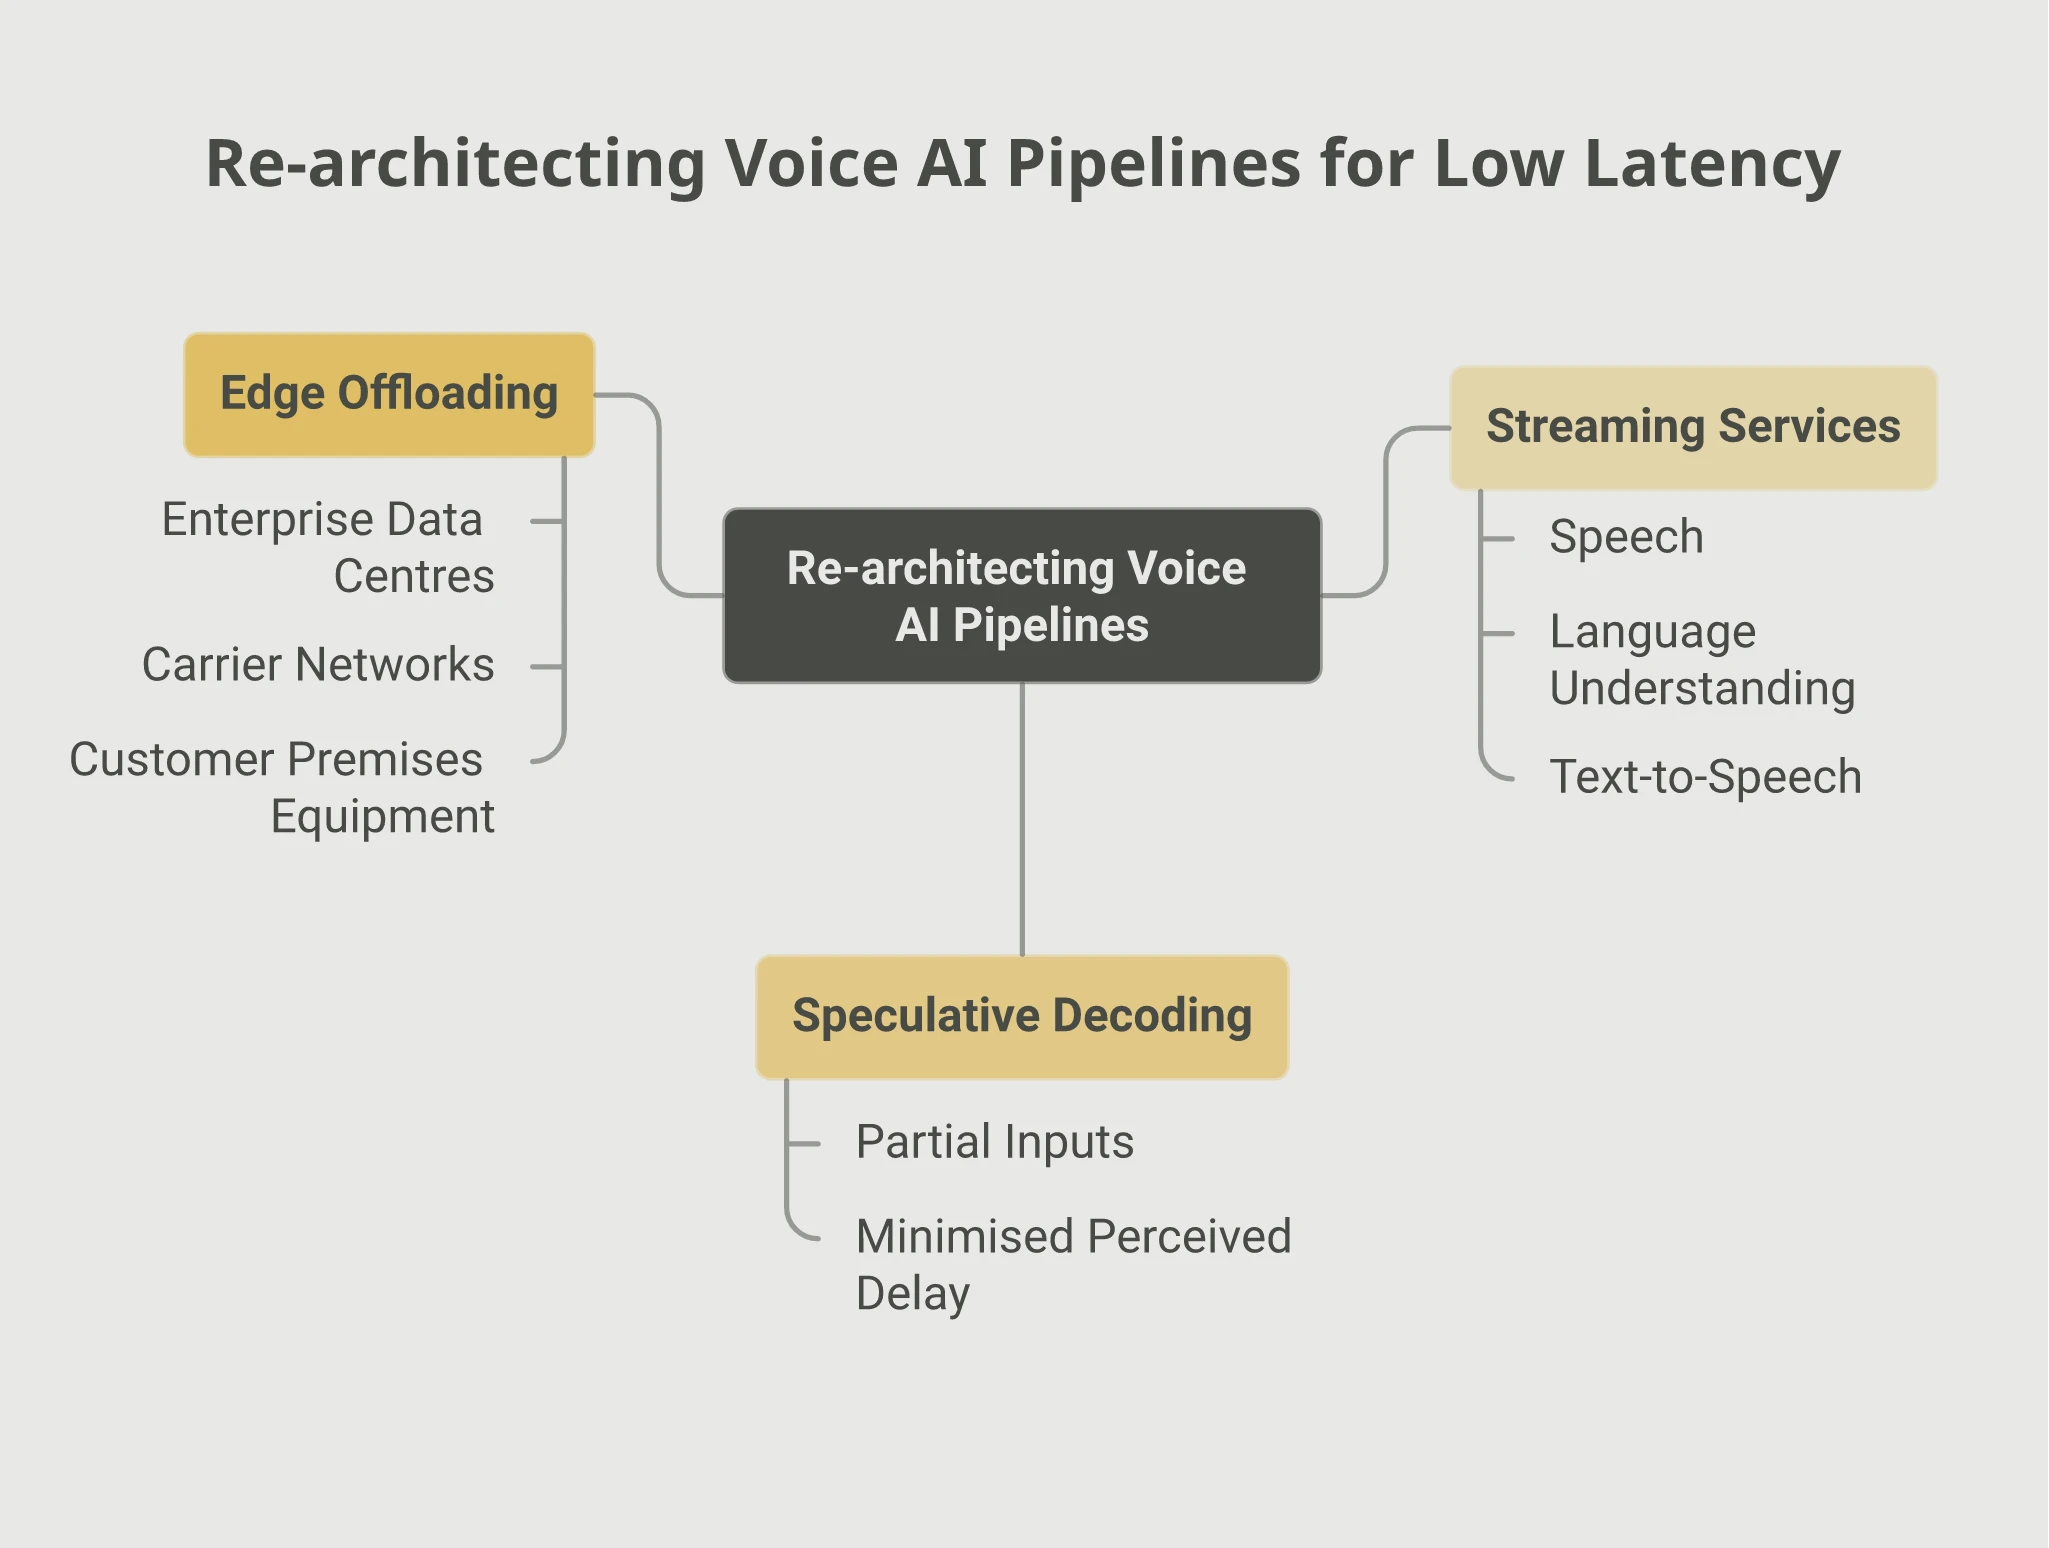
To get there, enterprises are rebuilding their pipelines end to end:
- Running speech, language understanding, and text-to-speech as streaming services that work in parallel.
- Using speculative decoding, and starting a response from partial input, to cut the delay users notice.
- Moving inference to the edge (enterprise data centres, carrier networks, or customer premises equipment) to cut out long internet round trips.
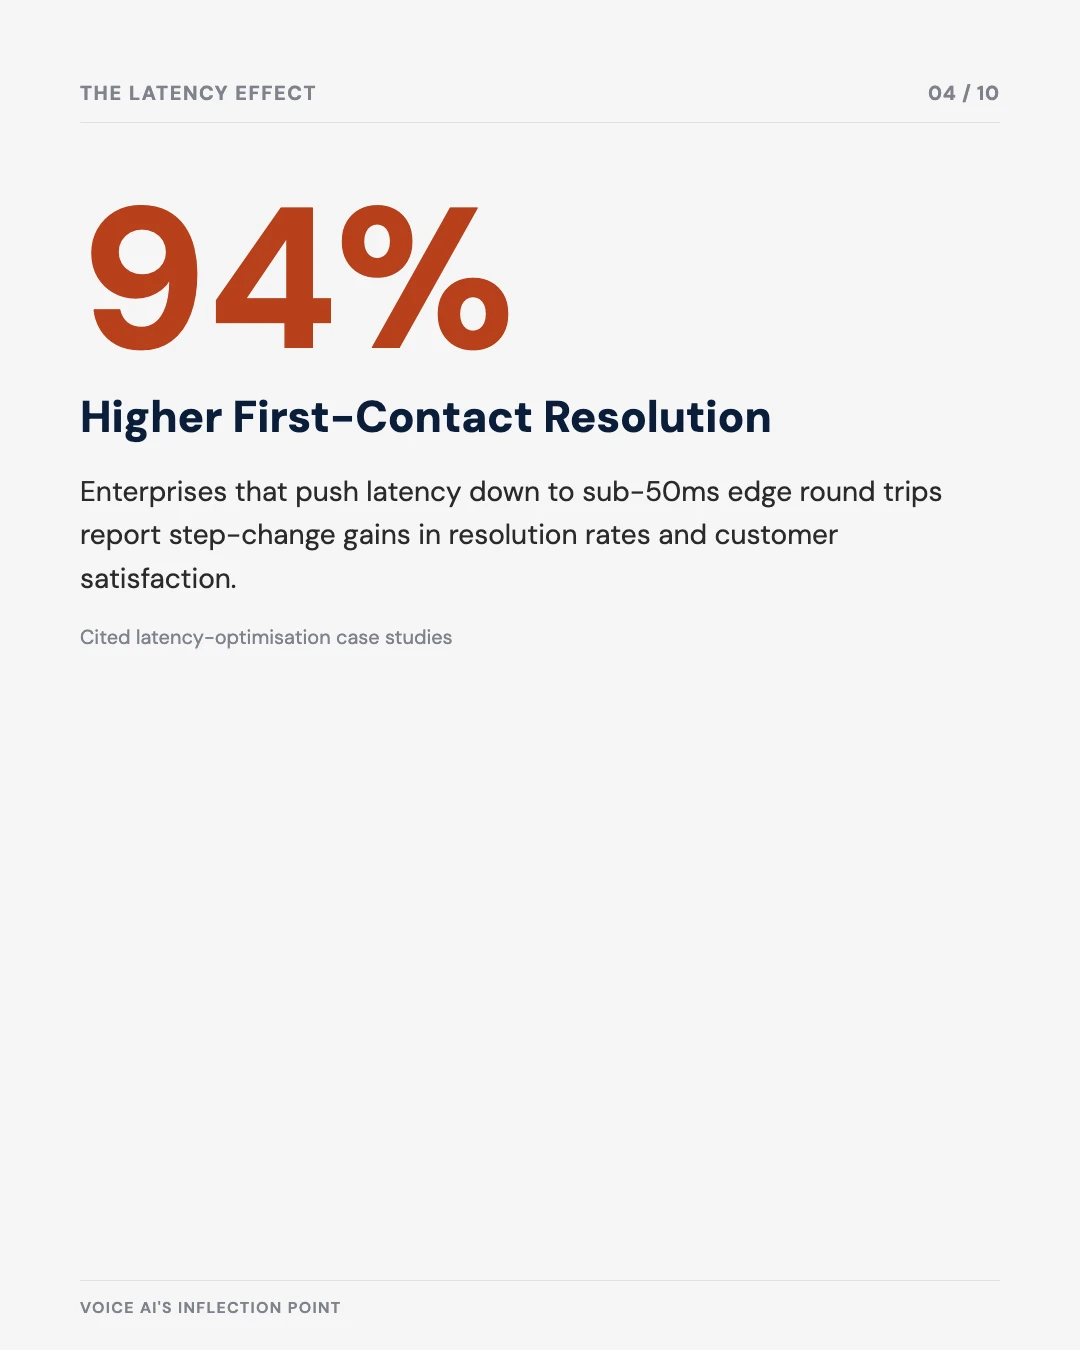
Edge deployment can cut network latency from hundreds of milliseconds to round trips under 50 milliseconds. Combined with 5G and multi-access edge computing, it supports latencies under 10 milliseconds for mission-critical uses. Organisations that have tuned latency across the board report big jumps in first-contact resolution, customer satisfaction, and channel adoption. Some document 94% higher first-contact resolution and double- to triple-digit rises in use of the AI channel.
Voice latency against the one-second limit of conversation
Linear scale in milliseconds. Latencies as cited in this post: the speech-model figure is Cartesia's own benchmark, and the edge figures are upper bounds reported for edge deployment and for 5G with multi-access edge computing (MEC).
At the same time, voice interfaces are moving from explicit command-and-response systems to ambient intelligence. In clinical settings, “ambient clinical intelligence” listens in the background as clinicians and patients talk. It writes structured notes and inserts them into electronic health records automatically. That cuts documentation time from around 12 minutes to roughly 2 minutes per encounter and reduces after-hours admin work by approximately 30%. Hospitals report annual savings in the tens of thousands of dollars per clinician in transcription and documentation costs. They also report measurable falls in adverse events linked to incomplete documentation.
Ambient systems must also cope with complex acoustic environments. One reported industry technique hides inaudible sound watermarks in TV adverts so they do not set off voice assistants by accident. It shows how aware of its surroundings voice AI must be to work reliably in noisy places such as factory floors or emergency departments.
Multimodal and sector-specific deployment
The most advanced platforms are moving past speech-to-text pipelines towards multimodal architectures. Models such as OpenAI’s GPT‑4o‑realtime-preview process audio natively. They read tone and emotion without a text step in between, and they can adjust responses in real time to the user’s emotional state. This cuts needless escalations and makes automation more resilient in sensitive conversations.
Vendors such as ElevenLabs are adding native support for both text and voice in one session, so users can switch between speaking and typing in the same interaction. This mix is especially useful in professional settings. Speech can be efficient for explaining a situation, while typing is better for structured data such as identifiers, medication names, or financial details. Adding computer vision widens what these systems can do. Systems that combine cameras and microphones can merge gestures, facial expressions, and spatial context with speech. That enables uses ranging from surgical assistance to vehicle navigation.
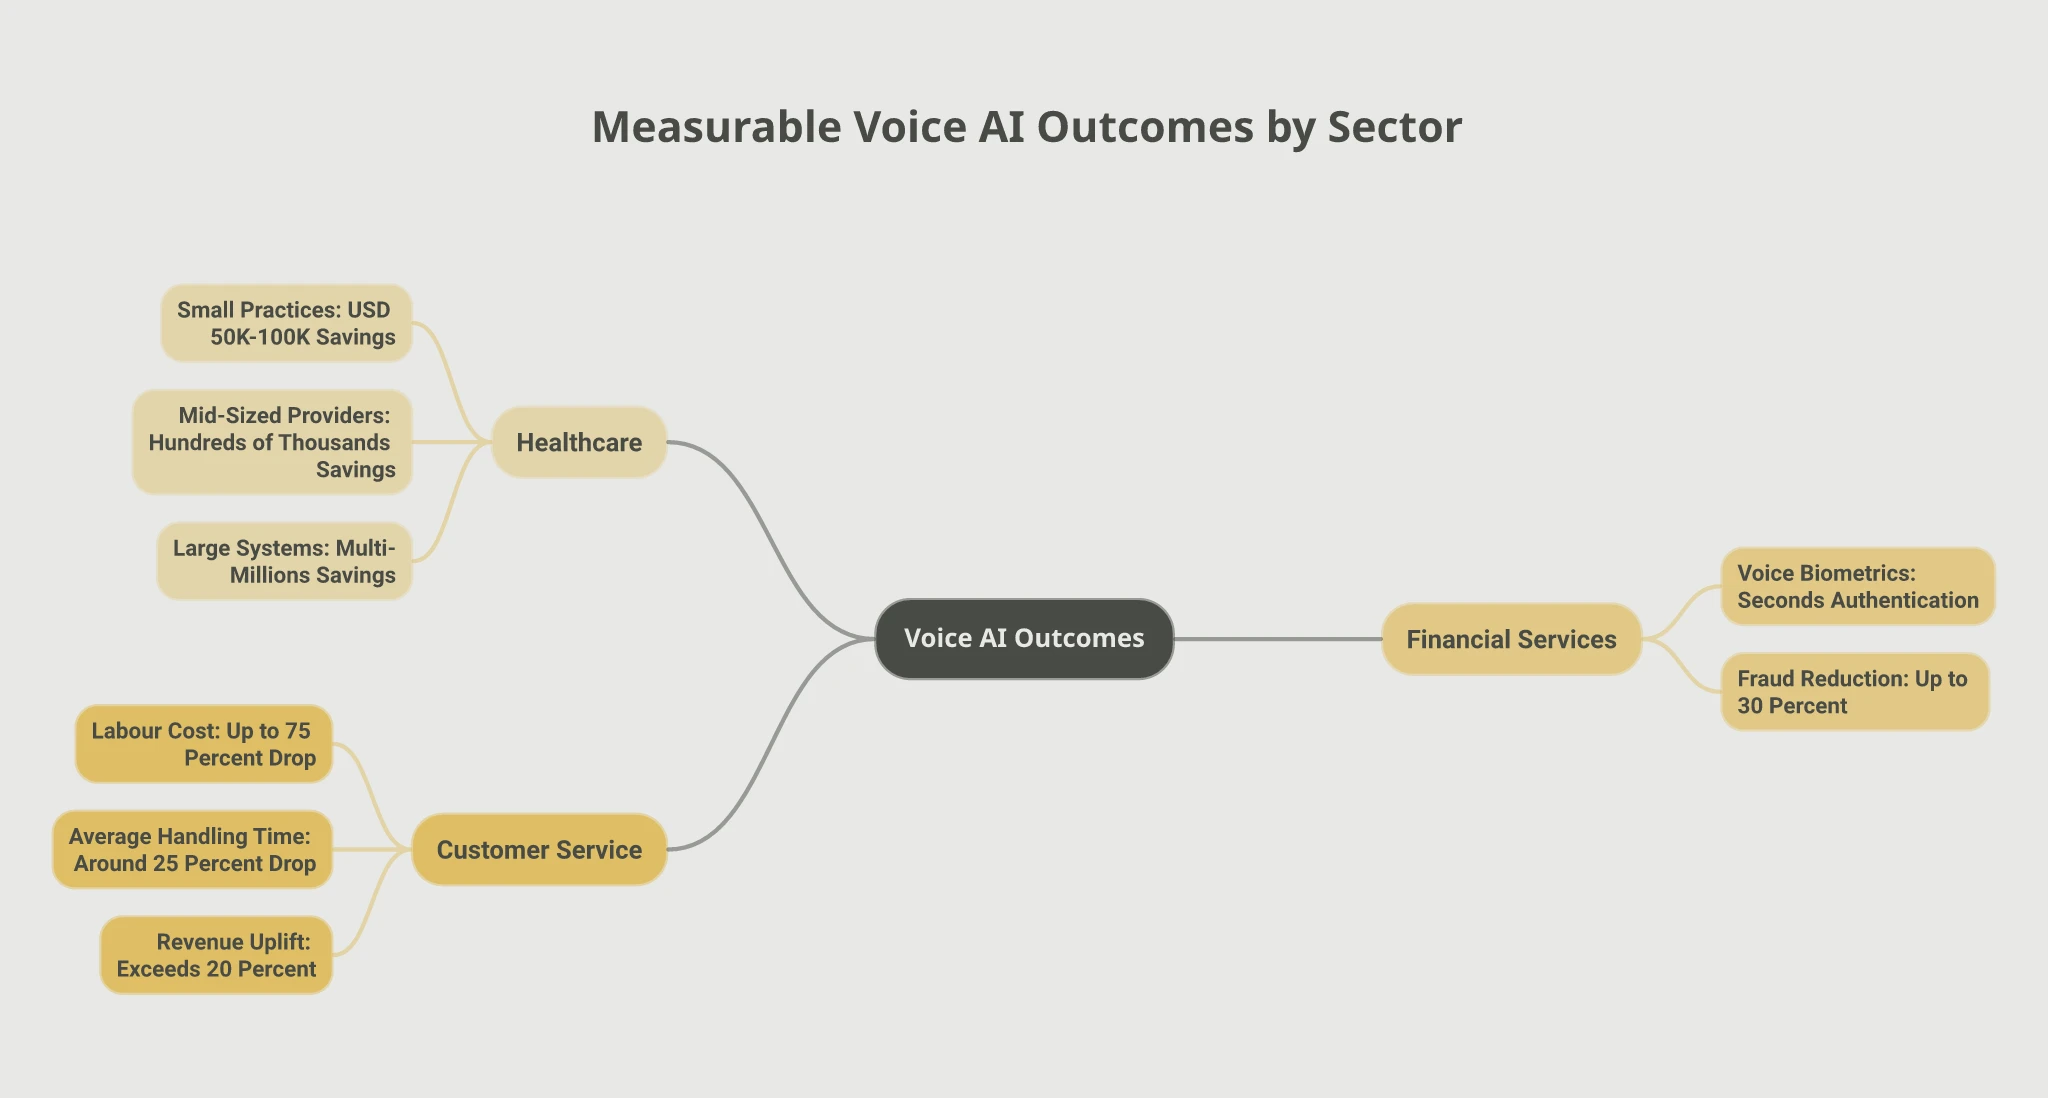
Across sectors, measurable outcomes are emerging:
- Healthcare : Voice tools for clinical notes and patient contact lighten clinicians’ admin load and give hands-free access to records during procedures. Small practices report annual savings of USD 50,000–100,000 from automating scheduling and front‑office queries. Mid‑sized providers report hundreds of thousands of dollars in savings, and large systems report multi-million‑dollar cuts in support and contact centre spending.
- Financial services : Voice biometrics cut authentication to a few seconds and reduce fraud attempts by up to 30% in some implementations. Biometric algorithms that resist deepfakes are becoming mandatory as fraud using generated audio grows.
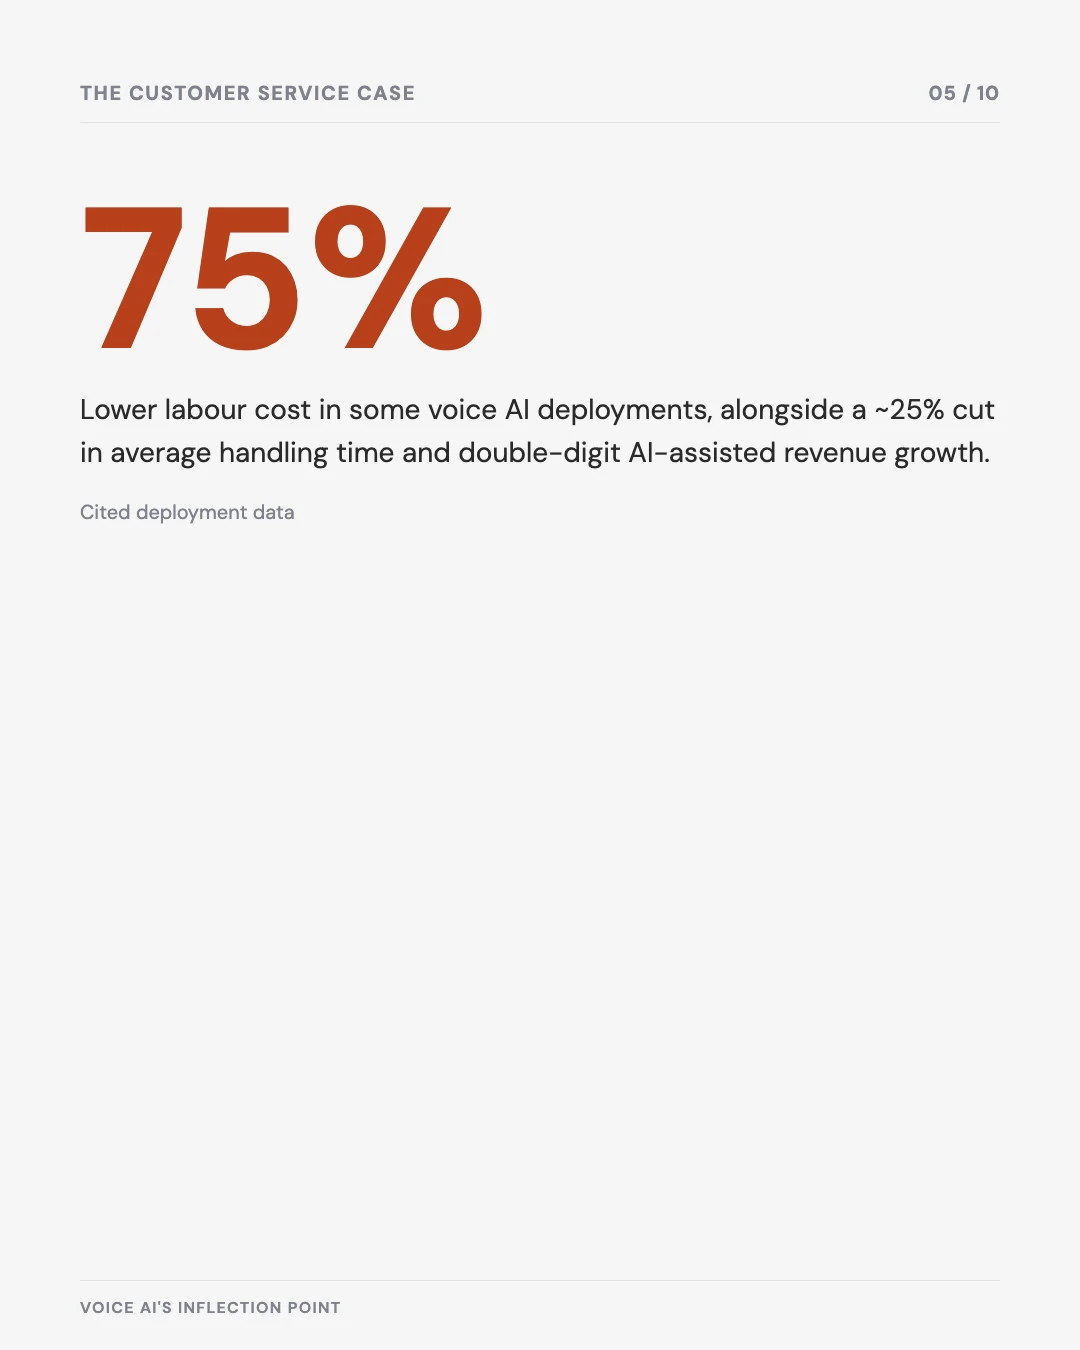
- Customer service : Voice AI is handling high volumes of calls at once. In some deployments it cuts labour cost by up to 75%, cuts average handling time by around 25%, and improves the quality of resolution. Organisations report double-digit revenue growth from AI-assisted sales, with some examples citing over 20% uplift from better targeting and follow-up.
Challenges, governance, and strategic implications
Despite progress, some challenges persist. Many automatic speech recognition systems still handle accents poorly. They are usually trained on a narrow range of standard accents. Research shows accuracy drops sharply for people who speak regional or sociolectal varieties such as Caribbean English or African American Vernacular English. In effect, this creates “accent penalties”. Techniques such as transfer learning, accent embeddings, and federated learning are being used to adapt models to underrepresented accents without pooling sensitive speech data in one place. But these remain active areas of R&D.
Deepfake voice synthesis has become a central security concern. Generative models can make convincing fake audio to trick people or to pose as an executive. That forces enterprises to build real-time deepfake detection into their voice biometric stacks. Leading solutions analyse fine-grained acoustic and behavioural signals. They work regardless of language and can spot synthetic patterns even when the content sounds plausible.
Enterprise trust also depends on data governance. In some cases, staff leaked confidential data by accident by pasting company information into public chatbots. Many organisations have since banned direct use of consumer-grade tools with sensitive material. At the same time, offerings such as ChatGPT‑based health assistants invite users to upload medical records and images. That raises questions about compliance with health data rules and about long-term use of such data to train models. As a result, serious adopters favour architectures that keep data in private clouds or on-premise. They combine this with retrieval-augmented generation and vector databases to give deterministic, auditable responses with low latency.
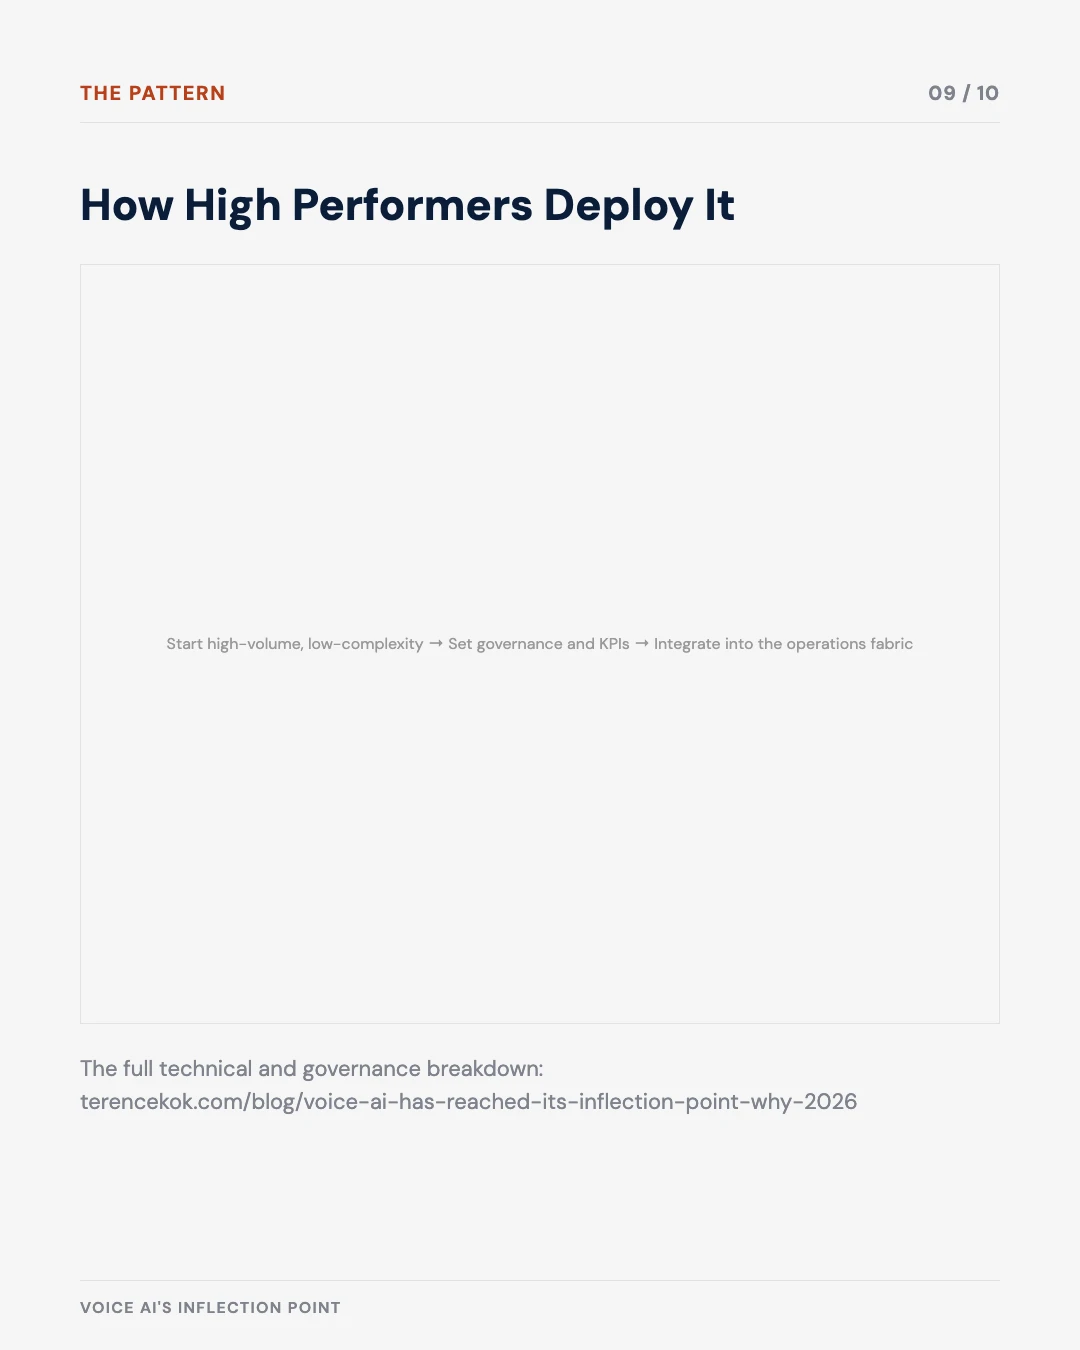
For programme leaders in smart cities and critical infrastructure, the strategic question is shifting. The opportunity is to design voice AI not as a series of pilots but as one joined-up capability that fits existing ICT, OT, and data platforms. High-performing organisations follow a consistent pattern:
- Start with high-volume, low-complexity workflows where you can show ROI quickly: the same selection criteria that apply to any agentic deployment, voice or otherwise.
- Set up governance, measurement baselines, and clear KPIs such as containment rate, average handle time, satisfaction scores, and cost per interaction.
- Connect voice AI tightly to CRMs, EHRs, ticketing, scheduling, and knowledge bases, so agents work as part of one unified set of digital operations.
Responsible AI is emerging as a performance lever rather than a compliance overhead. Surveys indicate that around 60% of executives credit structured responsible AI practices with better ROI and efficiency. Over half report measurable gains in customer experience and innovation when guardrails and transparency are built in by design. In sensitive fields such as healthcare and education, three things are now expected as standard: clear signs that users are dealing with an AI agent, firm safety limits, and a clean handover to human experts.
Responsible AI is emerging as a performance lever.
Evidence & Methodology
This piece leans on a lot of percentages. Some come from a benchmark, some from a forecast, and at least one is a number the whole industry repeats without anyone independently checking it. Here is the honest breakdown.
| Claim | Source | Grade |
|---|---|---|
| Sub-100ms response times are achievable with streaming and edge architectures | Cartesia’s own Sonic latency benchmark | Vendor benchmark |
| 40% of enterprise apps will feature task-specific AI agents by end of 2026 | Gartner’s 2025 forecast | Forecast |
| Ambient clinical intelligence cuts documentation time from 12 minutes to 2 minutes per encounter | Widely repeated across healthcare-AI vendor material, not independently audited in this piece | Unverified |
| Voice AI reduces customer service labour cost by up to 75% in some deployments | Best-case figures from specific implementations, not a general average | Best case, not typical |
Sources
- Cartesia. (2026). Sonic speech model latency benchmark.
- NVIDIA. (2026). “Cosmos: The Open Physical AI Foundation Model,“
- Gartner, Inc. (2025). “Gartner Predicts 40% of Enterprise Apps Will Feature Task-Specific AI Agents by 2026,“
Free tool
AI Trust, Risk & Governance Dashboard
Surface the accent bias, deepfake and data-lineage risks this piece flags before they show up in your voice AI deployment.