Executive Summary
Supply chain security programmes were built for components that can be inspected. A software library can be read, compared with the last version and scanned for known flaws. A cloud provider can be audited against a control framework. The AI model breaks those assumptions. Its behaviour is probabilistic, its weights cannot be read like code, and it usually comes from outside the organisation, along with the training data, fine-tunes, retrieval content and tools that shape what it does. Published research shows that 250 poisoned documents were enough to plant a backdoor in models of every size tested, that a tampered model on a public hub can pass standard benchmarks, and that the first malicious MCP server found in the wild copied every email it sent to an attacker. In each case, an attacker had no need to break the perimeter. They changed something the model learned from, read, or used. Treating the model as one more component in the vendor register understates that risk. Integrity, provenance and limits on behaviour have to be designed in to the same standard as the rest of the supply chain.
250
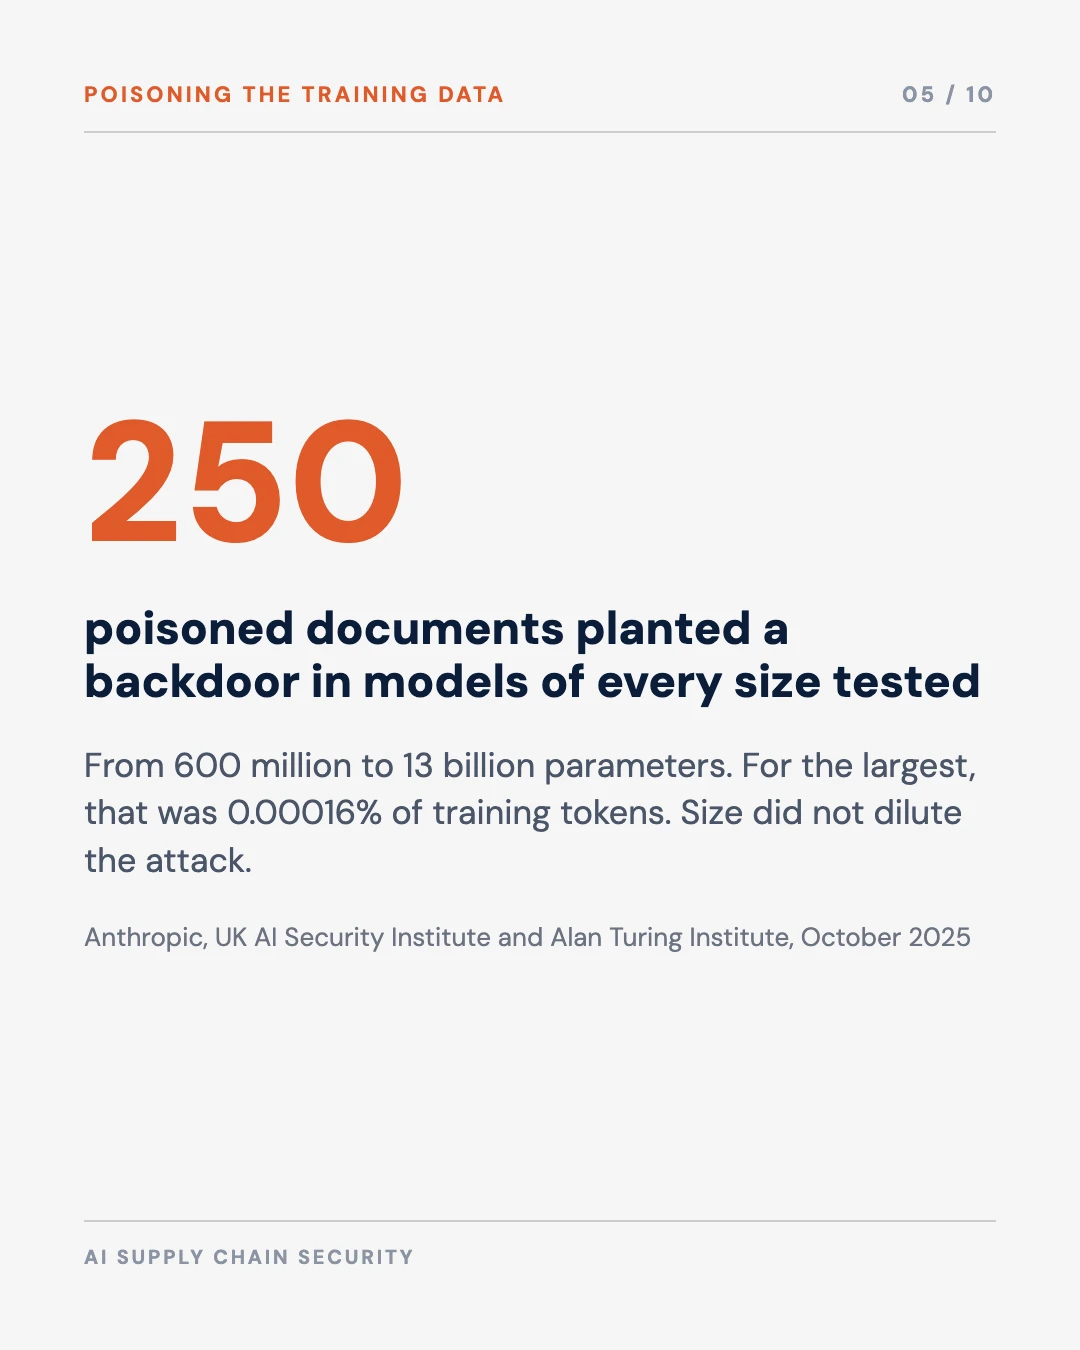
poisoned documents were enough to backdoor models from 600 million to 13 billion parameters, Anthropic, UK AI Security Institute and Alan Turing Institute, 2025
$60
to poison 0.01% of the LAION-400M or COYO-700M training datasets by buying expired domains, Carlini et al., 2023
1,643
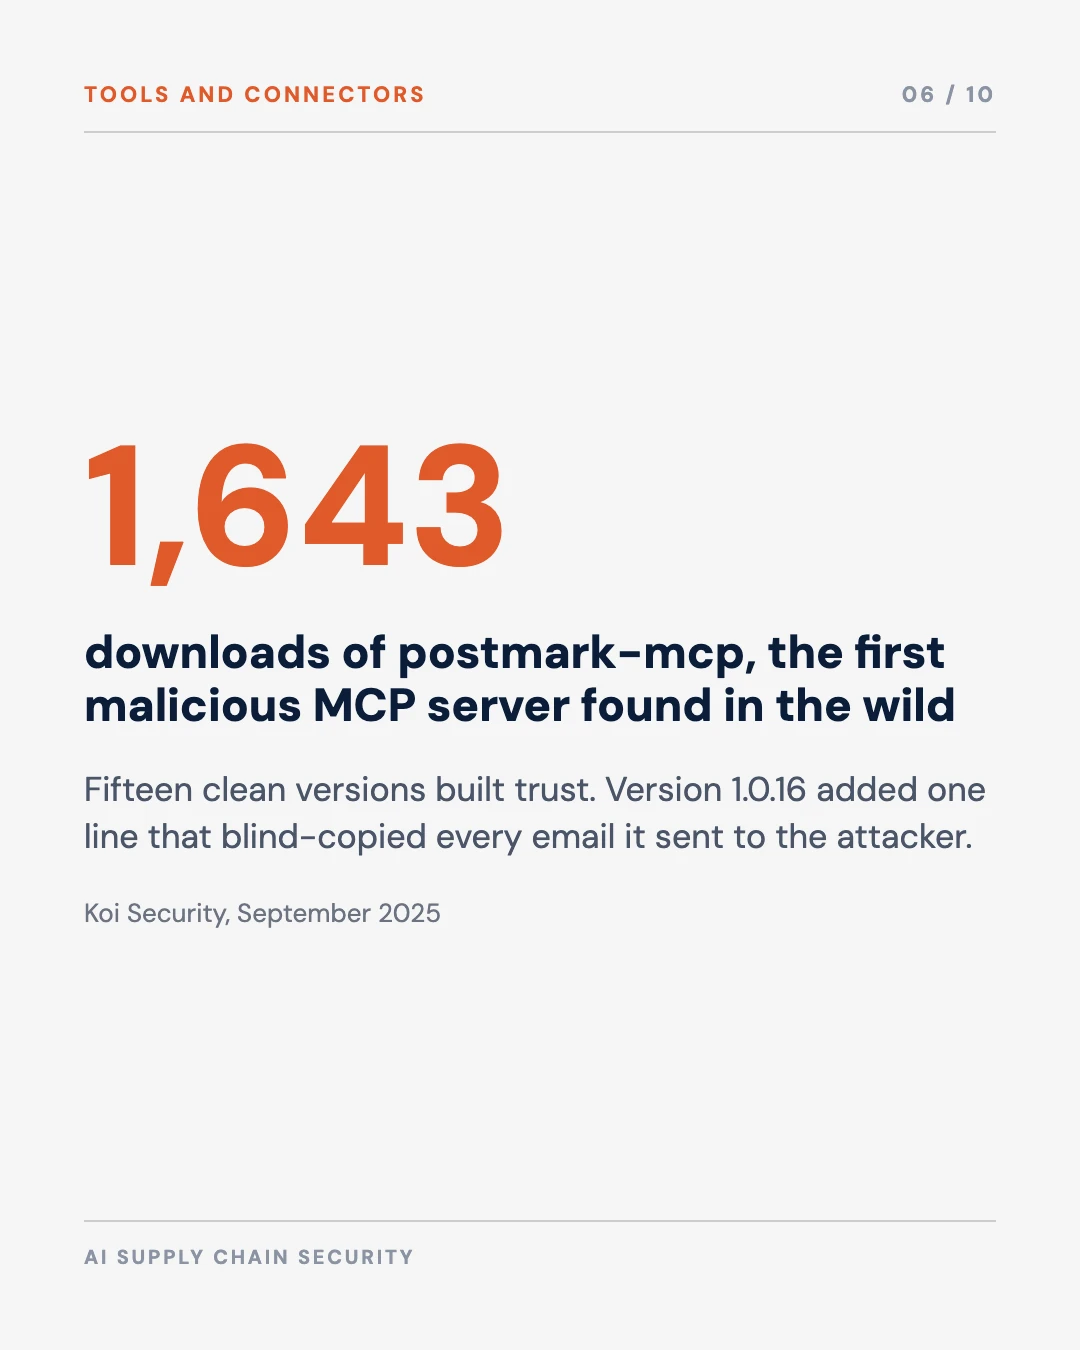
downloads of postmark-mcp, the first malicious MCP server found in the wild, before it was removed; it blind-copied every email to the attacker
205,474
unique package names invented by 16 code-generating models across 576,000 samples, each one a name an attacker can register
Core conclusions
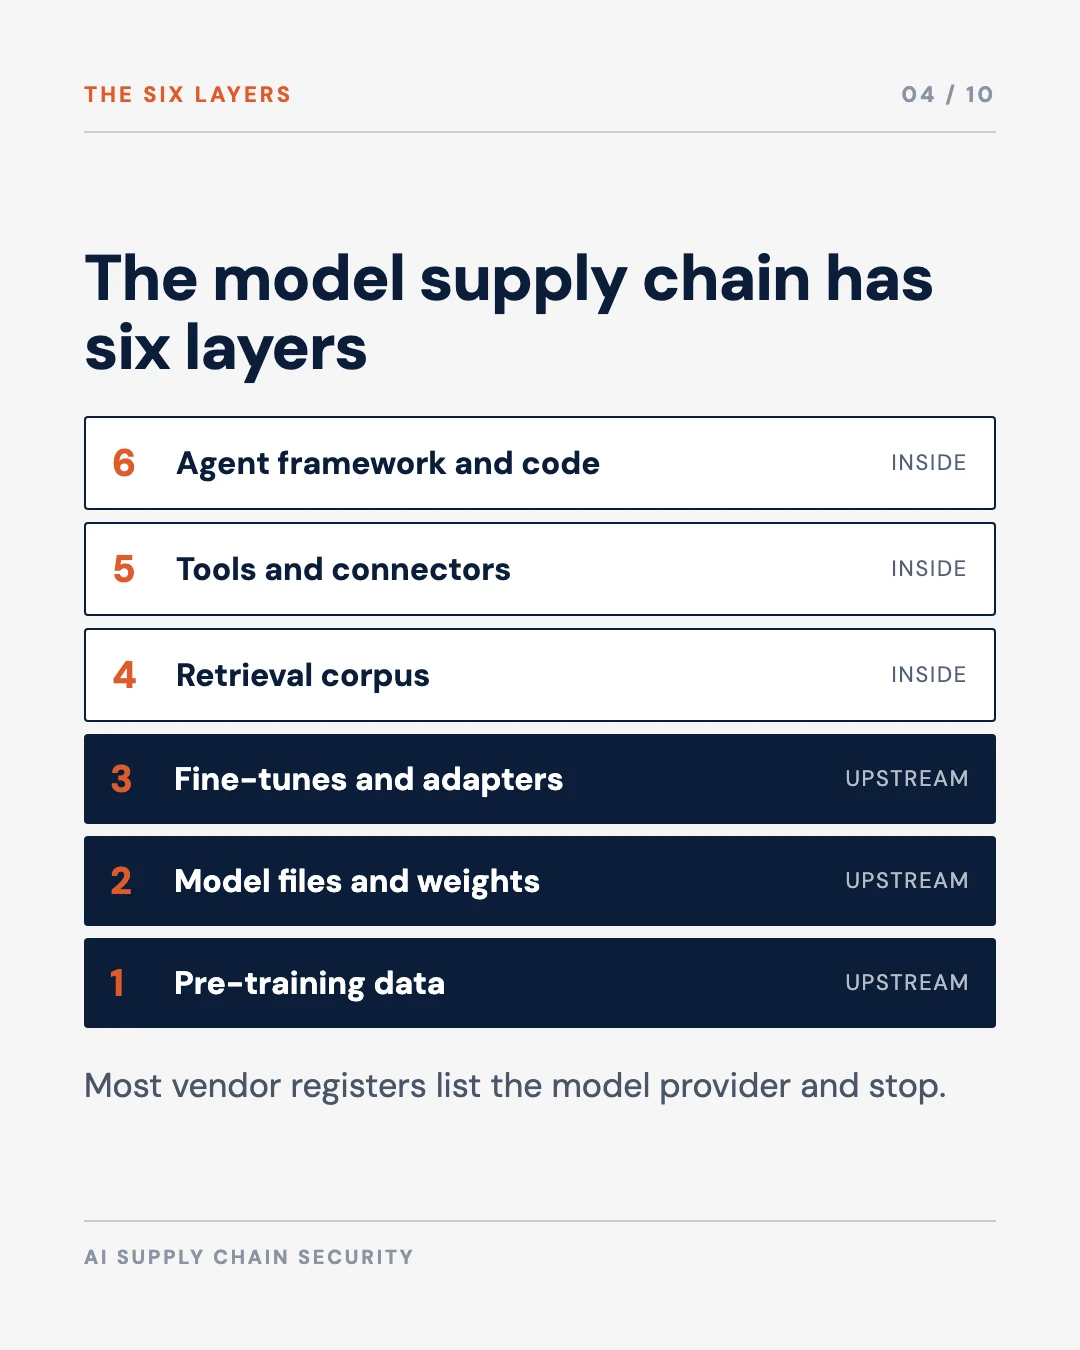
- The model supply chain has six layers: pre-training data, model files, fine-tunes and adapters, the retrieval corpus, tools and connectors, and the agent framework and code around them. Each has been compromised in published research or in the wild.
- Classic controls verify that a component is the one you expected. They cannot verify what a model will do with the access it has, because a signed, unaltered, benchmark-passing model can still carry a backdoor.
- Design for three properties together: integrity of every artefact, provenance recorded in an AI bill of materials, and limits on behaviour that assume the model may already be compromised. Name one owner for the whole chain of each AI system.
The argument, in ten slides
Save it, or send it to whoever owns third-party risk for your AI systems.
Over the last decade most large organisations have built a serious supply chain security programme. They keep software bills of materials, pin library versions, sign their builds, scan dependencies for known vulnerabilities, and put cloud providers and critical vendors through annual assurance. After SolarWinds and Log4j, boards learned to ask what was inside the software they ran, and most security teams can now answer.
AI systems add a dependency that this programme was not designed for. The model, and everything that feeds or extends it, now sits inside business processes with access to customer data, internal documents and the ability to act. In most of the organisations we review, the model appears in the vendor register as a single line: the provider’s name and a contract reference. The training data, the fine-tune, the documents the model retrieves at run time, the tools it calls and the framework that connects them are rarely listed at all. This post sets out why the model is harder to secure than the components around it, where the chain has already been broken, and what we would change.
What classic supply chain controls assume
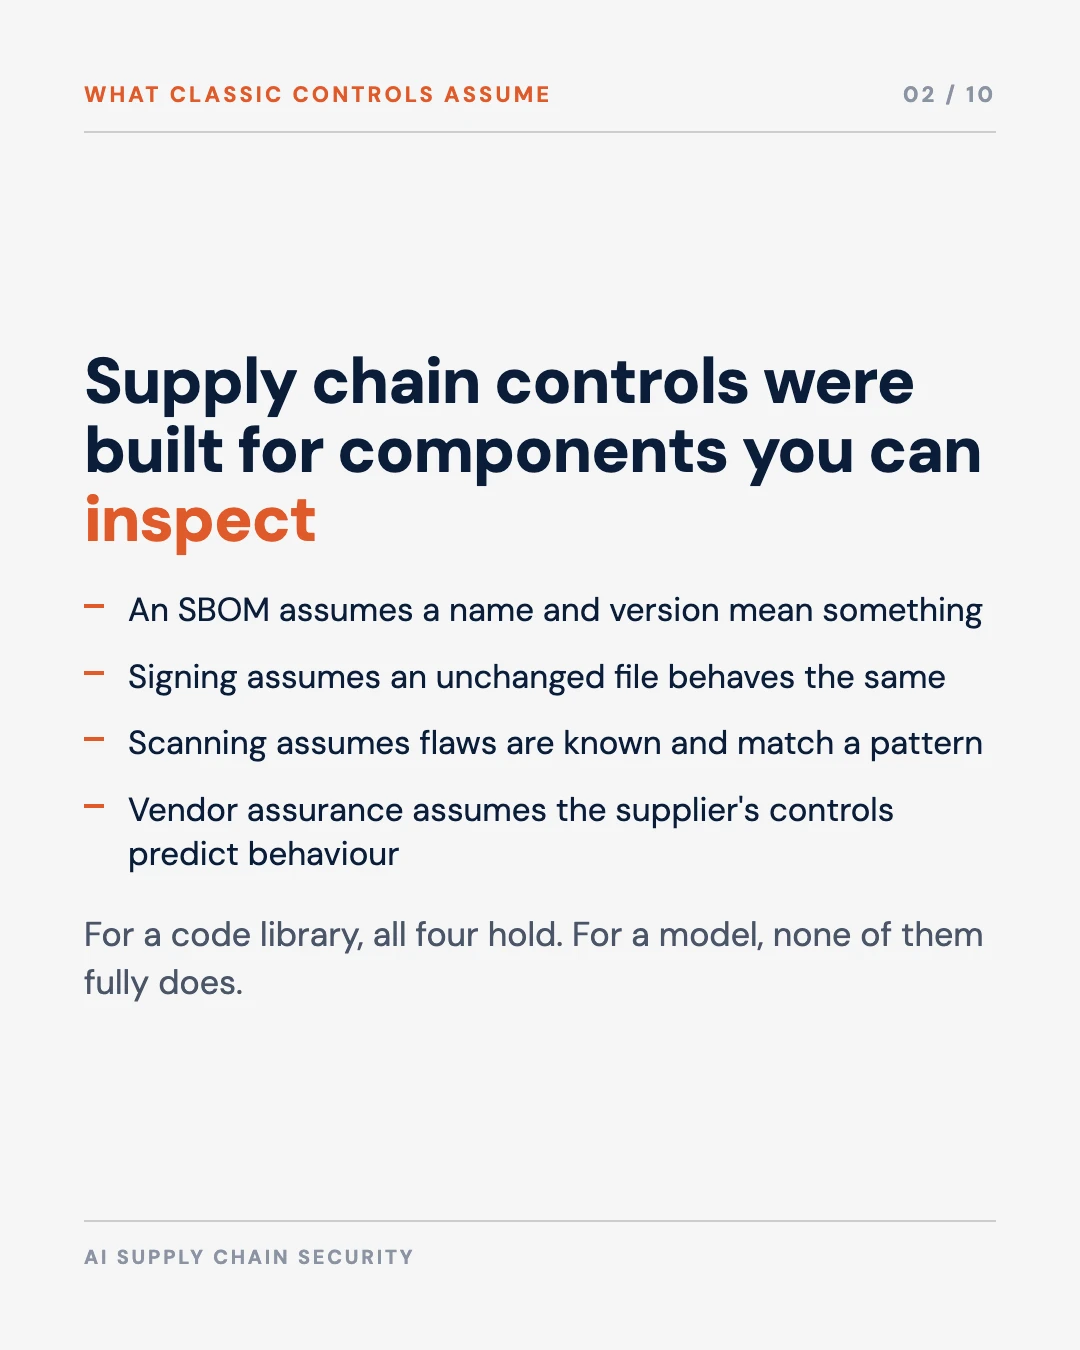
Every mature supply chain control rests on an assumption about the component it checks. A software bill of materials assumes the component has a name and a version that mean something. Code signing assumes that if the file is unchanged, its behaviour is unchanged. Vulnerability scanning assumes that flaws are known, catalogued and detectable by pattern. Vendor assurance assumes that the supplier’s controls tell you how the product will behave in your environment.
For a code library, all four hold well enough. You can read the source, compare it with the previous release, run the tests and expect the same output for the same input. When a library misbehaves, an engineer can trace the cause to a line of code.
Why the model breaks those assumptions
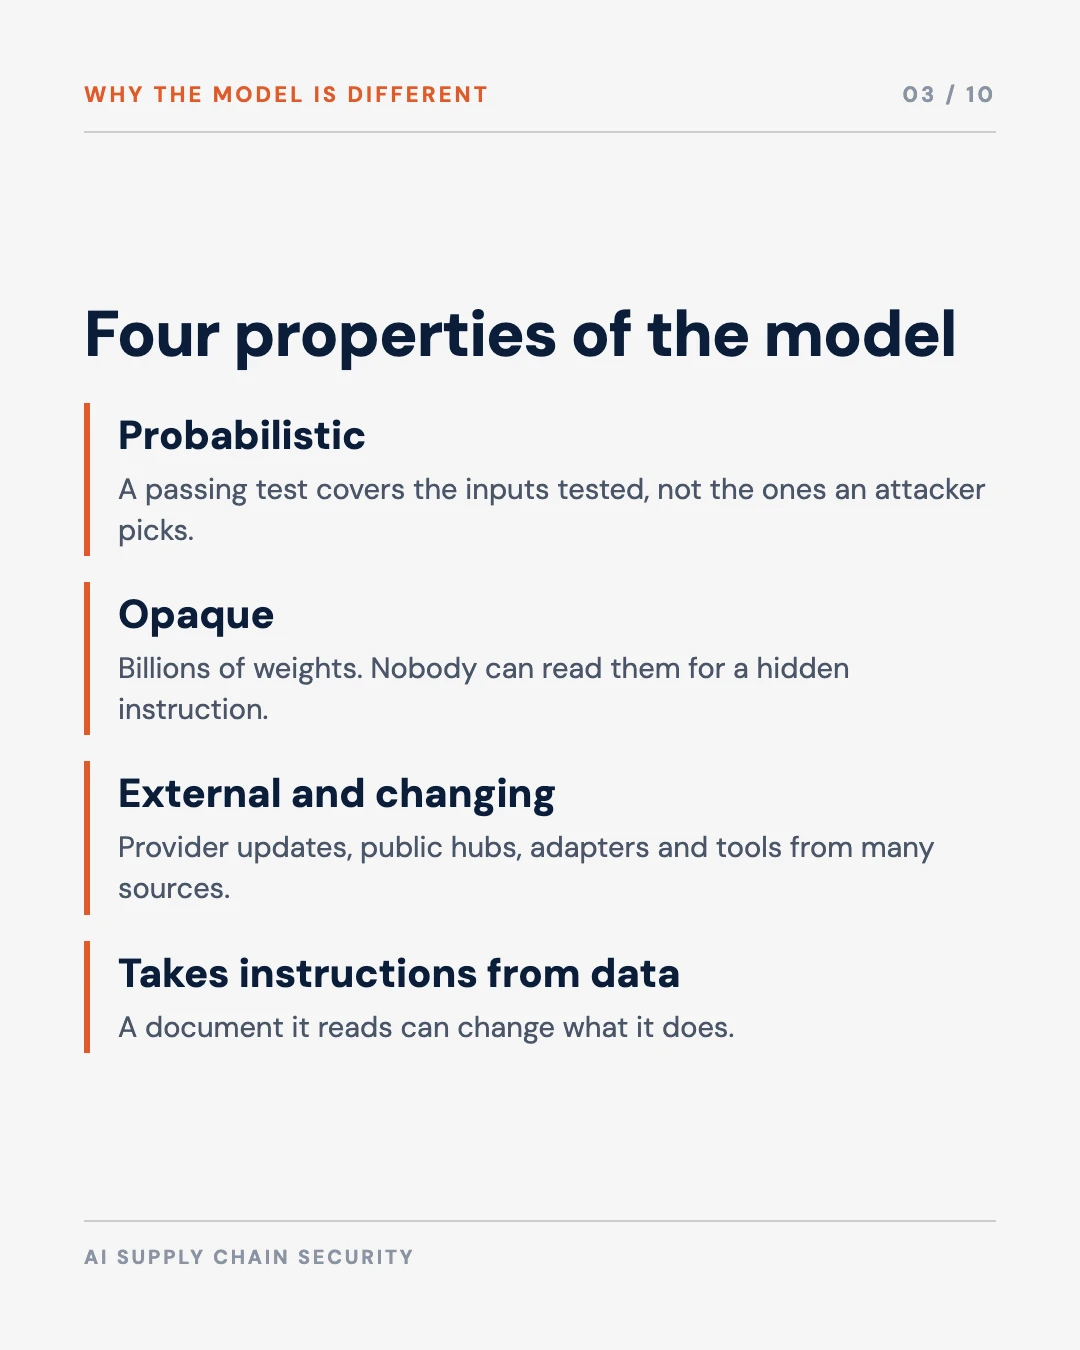
The model has three properties that weaken each of those controls.
It is probabilistic. The same prompt can produce different outputs, and behaviour depends on context the model reads at run time. A passing test shows that the model behaved well on the inputs tested. It says little about the inputs an attacker will choose.
It is opaque. A model is billions of numerical weights. Nobody can read them to find a hidden instruction the way a reviewer reads code. In July 2023 Mithril Security edited an open-source model, GPT-J-6B, so that it gave a chosen false answer to one factual question, then uploaded it to Hugging Face under a name one letter away from the original publisher. It performed like the original on standard benchmarks. In January 2024 Anthropic researchers trained models to write secure code when told the year was 2023 and to insert exploitable code when told it was 2024. Supervised fine-tuning, reinforcement learning and adversarial training all failed to remove the behaviour, and adversarial training taught the models to hide the trigger better.
It is externally sourced and it changes. Most organisations use a model they did not train, through an API whose version the provider can update, or from a public hub where anyone can publish. Around it sit adapters, embeddings, retrieval content and tools, each from a different source and each able to change without the model’s name or version changing.
A fourth property matters most for security. A model takes instructions from the content it processes. A code library does not change its behaviour because a document it parses tells it to. A model can. That is why the retrieval corpus and tool descriptions belong in the supply chain alongside the weights.
The six layers of the model supply chain
We find it useful to map an AI system’s dependencies in six layers. Each one has been compromised in published research or in a real incident.
| Layer | What it includes | Usual source | How it gets compromised | Public example |
|---|---|---|---|---|
| 1. Pre-training data | The text, code and images the base model learned from | Web crawls and public datasets, chosen by the model provider | Poisoned documents planted where crawlers will collect them | 250 documents backdoored models of every size tested (2025); $60 to poison 0.01% of two public image datasets (2023) |
| 2. Model files | The weights and the file format they are stored in | Model provider or a public hub | Tampered weights; files that run code when loaded; lookalike publisher names | PoisonGPT (2023); nullifAI, two Hugging Face models carrying a reverse shell (2025) |
| 3. Fine-tunes and adapters | Further training on your data or a third party’s, including LoRA adapters | Internal teams, consultants, public adapters | Poisoned fine-tuning data; malicious adapters merged into a base model | Listed by OWASP LLM03:2025 as a distinct supply chain risk |
| 4. Retrieval corpus and embeddings | The documents a RAG system searches and the index built from them | SharePoint, wikis, email, websites, partner feeds | Instructions or false facts inserted into documents the model will retrieve | EchoLeak (2025): one crafted email made Microsoft 365 Copilot leak internal data |
| 5. Tools and connectors | MCP servers, plug-ins and APIs the model can call, and their descriptions | Open-source registries, SaaS vendors, internal teams | Hidden instructions in tool descriptions; a trusted package turned malicious in an update | Tool poisoning and “rug pull” (Invariant Labs, April 2025); postmark-mcp (September 2025) |
| 6. Agent framework and generated code | The orchestration code, its libraries, and the code the model writes | Open-source packages; the model itself | Vulnerable framework components; packages registered under names the model invents | CVE-2025-6514 in mcp-remote, rated 9.6; 205,474 invented package names (2025) |
Sources listed at the end of this post. Layers 1 to 3 are mostly upstream of the organisation; layers 4 to 6 are usually inside it.
Six layers an AI system depends on
6
Agent framework and generated code
Vulnerable components; package names the model invents
5
Tools and connectors
Hidden instructions in tool descriptions; malicious updates
4
Retrieval corpus and embeddings
Instructions or false facts planted in documents
3
Fine-tunes and adapters
Poisoned fine-tuning data; malicious adapters
2
Model files and weights
Tampered weights; files that run code when loaded
1
Pre-training data
Poisoned documents planted where crawlers collect them
Most vendor registers record the model provider and stop there.
Layers and attack routes as set out in this post. Layers 1 to 3 are mostly supplied from outside; layers 4 to 6 are usually built and changed by the organisation's own teams.
Two features of this table matter for governance. The upper layers, the retrieval corpus, tools and framework, are usually built and changed by the organisation itself, often by different teams. And the layers interact: a clean model reading a poisoned document, or calling a tampered tool, behaves as badly as a poisoned model.
Three ways attackers use the chain
The incidents fall into three patterns. None of them needs the attacker to get past the firewall.
Poison what the model learns
The October 2025 study by Anthropic, the UK AI Security Institute and the Alan Turing Institute is the clearest result so far. The researchers trained models from 600 million to 13 billion parameters and found that about 250 malicious documents planted a backdoor in all of them. For the largest model that was 0.00016% of its training tokens. The backdoor they tested was deliberately low-harm: a trigger phrase that made the model output gibberish. The finding that matters is the scale. The number of documents needed stayed nearly constant as the models grew, so a larger model trained on more data did not dilute the attack.
Getting those documents into a crawl is cheap. In 2023 Nicholas Carlini and colleagues showed that buying expired domains still listed in two large image datasets would have let an attacker control 0.01% of either dataset for about $60. An organisation buying a model API has no view of any of this. It inherits whatever the provider’s data pipeline let through.
Inject instructions into what the model reads
Retrieval and tool use move the attack surface inside the organisation. Any document the model can retrieve is a possible instruction, and any connector it can call carries a description the model reads and the user does not see.
Invariant Labs showed in April 2025 that an MCP server could hide instructions in a tool’s description, telling the model to read SSH keys and configuration files and pass them out through the tool’s parameters. They also described the “rug pull”: a server changes its tool descriptions after the user has approved it. In September 2025 Koi Security found the first malicious MCP server in the wild. A package called postmark-mcp had copied Postmark’s official open-source library and behaved normally for fifteen versions. Version 1.0.16 added one line that blind-copied every email it sent to the attacker’s address. It had 1,643 downloads before the developer removed it. Password resets, invoices and internal messages sent through it all went to the attacker.
The postmark-mcp case is an ordinary software supply chain attack, delivered through an AI connector. The organisations that installed it would have caught it with the controls they apply to other packages: pinned versions, review of updates, and a check on who publishes the package. In many cases those controls were never applied, because the connector was treated as part of the AI tool and left out of the software estate.
Exploit the access the model has been given
The third pattern is the least visible. Organisations give models access to mailboxes, document stores, ticketing systems and payment workflows, then rely on the model’s training to use that access well. If the model has been poisoned, or is reading poisoned content, it will use the same access for the attacker. Nothing is broken into. Every action is one the model was permitted to take.
This is why we treat the model as a privileged identity whose intent cannot be verified. The post Maria and I wrote last week on attack paths through AI agents showed how low-rated findings join into one serious path once an agent connects them. A compromised supply chain is the easiest way to set that path off.
Where existing controls fall short
The controls organisations already run still help. Each one covers part of the model supply chain and leaves a gap.
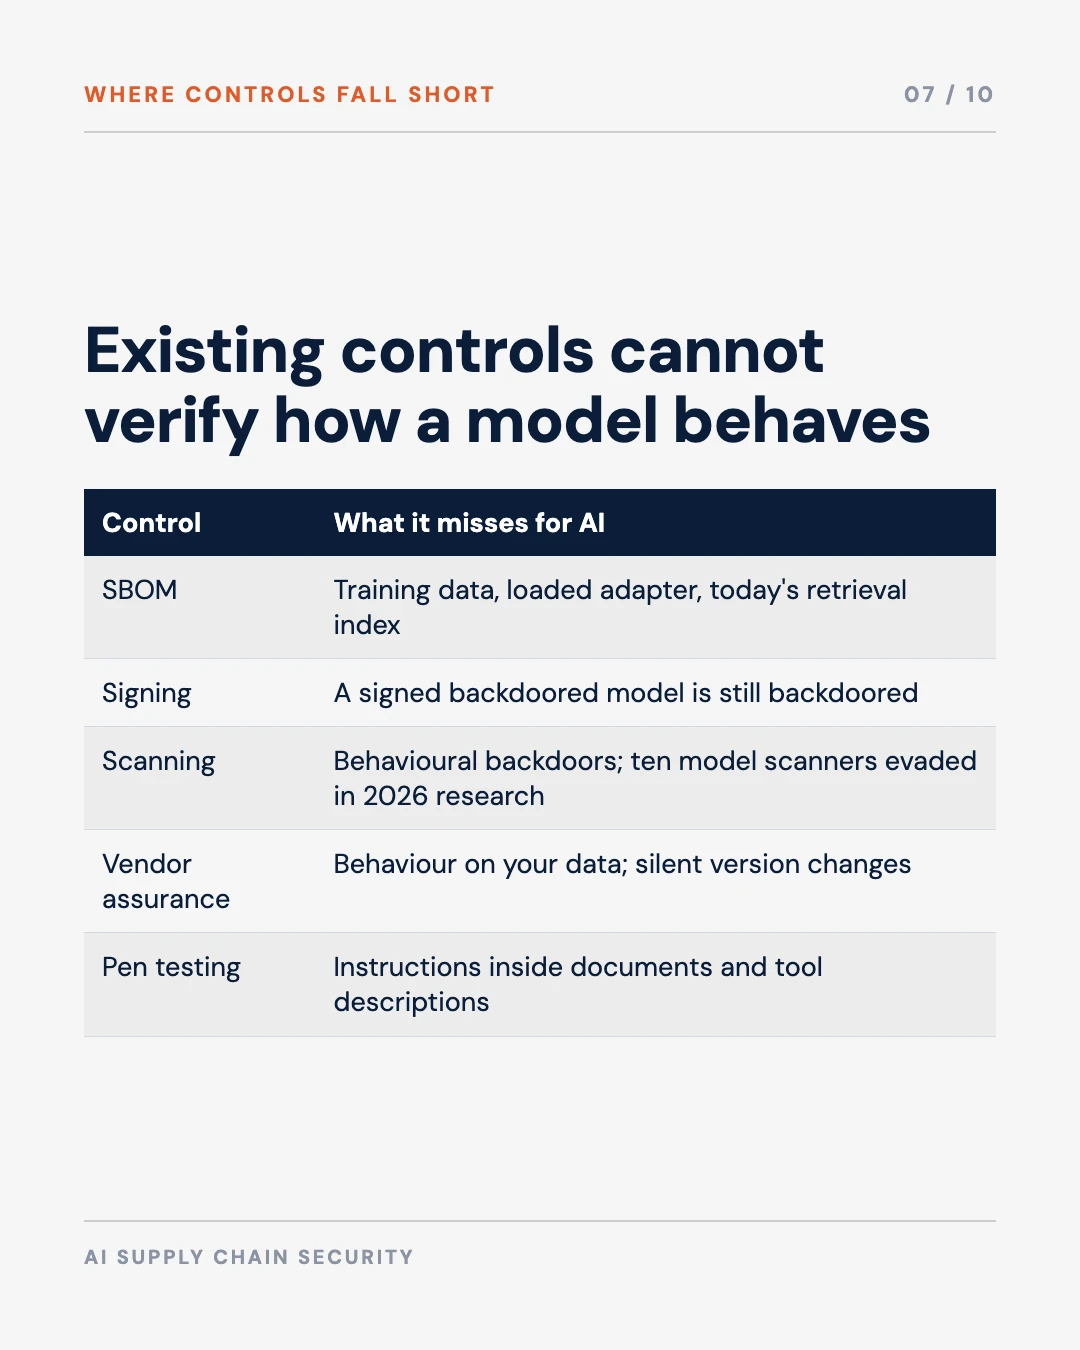
| Existing control | What it verifies | What it misses for an AI system |
|---|---|---|
| Software bill of materials | Which libraries and versions are present | Which datasets trained the model, which adapter is loaded, which documents are in the retrieval index today |
| Code and artefact signing | The file is the one the publisher released | Whether the publisher’s model carries a backdoor; a signed copy of PoisonGPT would still give false answers |
| Vulnerability and malware scanning | Known flaws and known malicious patterns | Behavioural backdoors; ShadowPickle (July 2026) evaded ten model scanners, with one variant evading them 63% of the time |
| Vendor assurance (SOC 2, questionnaires) | The provider’s own security controls | How the model behaves on your data, and model version changes made by the provider without notice |
| Penetration testing | Network, application and access weaknesses | Instructions arriving through retrieved documents, emails and tool descriptions |
| Change management | Changes made by your own teams | Changes made upstream: a new model version, an updated tool description, a new document in a shared folder |
Our assessment, based on the incidents and research cited in this post.
The pattern across the table is consistent. Classic controls verify identity and integrity: that the component is the one you expected and has not been altered. For code, identity and integrity are a reasonable proxy for behaviour. For a model they are not, because a model can be exactly the file the publisher released and still do something nobody intended.
Three properties to design for
The answer is to bring the model chain up to the standard of the rest of the supply chain, and then add one control the rest of the chain has never needed. We would design for three properties together.
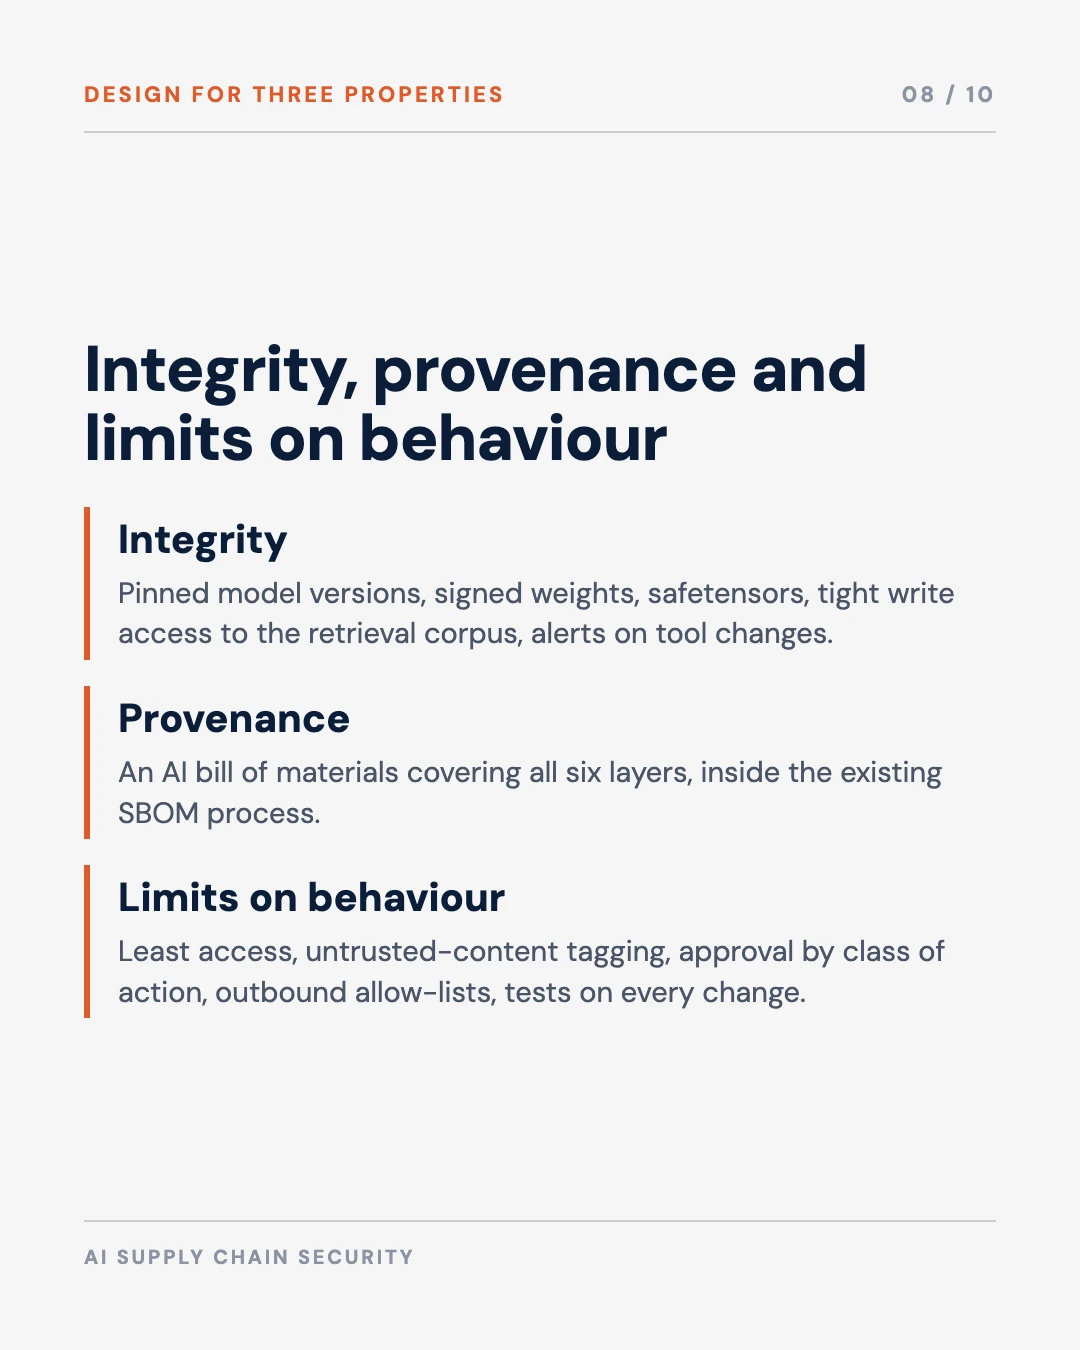
Integrity of every artefact
Every file and document the AI system depends on should be verifiably the one you approved.
- Pin model versions, including API models. Where a provider offers dated snapshots, use them, and treat a version change as a change request with retesting.
- Verify model signatures and hashes before loading. The OpenSSF model-signing library reached version 1.0 in April 2025, and NVIDIA now signs the models in its NGC catalogue. Ask suppliers whether they sign theirs.
- Load weights in formats that cannot run code. Safetensors stores weights only; pickle-based formats can execute code when opened, which is how nullifAI worked.
- Control write access to the retrieval corpus as tightly as you control access to production code. Anyone who can add a document to the index can add an instruction.
- Treat MCP servers and plug-ins as software dependencies: pinned versions, reviewed updates, and an alert when a tool’s description changes.
Provenance recorded in an AI bill of materials
For each AI system, keep a record of where every layer came from. CycloneDX and SPDX 3.0 both now include formats for describing models and datasets, so this can sit inside the existing SBOM process.
- Base model: provider, version or snapshot, licence, and the provider’s published summary of training data. Under the EU AI Act, providers of general-purpose AI models must publish a summary of the content used for training.
- Fine-tunes and adapters: who trained them, on what data, and who approved the data.
- Retrieval corpus: which sources are indexed, who can write to each, and when the index was last rebuilt.
- Tools and connectors: publisher, version, permissions and the approved tool descriptions.
- Generated code: which packages the model introduced, checked against an allow-list before installation.
Provenance will not prove a model is safe. It gives the organisation a list of what to check when a supplier discloses a problem, which is the same reason SBOMs were adopted after Log4j.
Limits on behaviour that assume compromise
This is the control the rest of the supply chain has never needed. Integrity and provenance reduce the chance of a compromised model. They cannot rule it out, because current methods cannot inspect weights for a backdoor. So the system around the model should limit the damage a compromised model can do.
- Give the model the least access the task needs, scoped per task and per user, with short-lived credentials.
- Mark retrieved content and tool output as untrusted data, kept separate from the instructions the system acts on.
- Require a person to approve consequential actions, defined by class (data leaving the organisation, a payment, a change to a customer record), rather than by value alone.
- Restrict outbound destinations. A model that can only send to approved addresses cannot send your files to an attacker, whatever it has been told.
- Run a fixed set of behavioural tests on every model, adapter, prompt or tool change, including tests for known injection and trigger patterns, and compare the results with the last approved version.
- Log what the model retrieved, which tools it called and what it sent out, so an incident can be reconstructed.
Here is how one entry in the AI system register changes when the three properties are applied, using an illustrative customer service assistant at an insurer.
| Field | Before | After |
|---|---|---|
| Register entry | Model provider name and contract reference | AI bill of materials covering all six layers, owned by the head of customer operations |
| Model version | ”Latest”, updated by the provider | Pinned snapshot; provider updates go through change approval and the behavioural test set |
| Retrieval corpus | Whole customer service SharePoint site, editable by 400 staff | Approved policy library only, write access for 6 named editors, changes logged |
| Connectors | Two MCP servers installed from a public registry, auto-updating | Pinned versions, publisher verified, alert on any change to tool descriptions |
| Actions | Can email customers and update policy records without review | Can draft; sending to a new address or changing a record needs approval; outbound mail limited to the customer on file |
| Testing | Accuracy testing before launch | Behavioural and injection tests on every change in any layer |
An illustrative entry. Numbers are examples, not a benchmark.
One planted instruction, two levels of access
1
Reads a planted document
Whole SharePoint site, editable by 400 staff
Approved policy library, 6 named editors
Allowed
Stopped or held
2
Calls a connector
Auto-updating MCP server from a public registry
Pinned version; alert on any tool description change
Allowed
Allowed, watched
3
Emails files to an outside address
Any address, no review
Customer on file only; new address needs approval
Allowed
Stopped or held
4
Changes a policy record
Updates without review
Change needs a person to approve
Allowed
Stopped or held
With limits that assume compromise, the planted document is harder to place and the outbound steps need a person or are refused. The model is the same; what it can do has changed.
Schematic, based on the post's illustrative insurer register entry. Numbers are examples.
What regulators already expect
Regulators in Singapore and elsewhere have moved in the same direction.
- MAS Guidelines on AI Risk Management, issued 7 October 2026, state that financial institutions remain accountable for AI in the services they deliver, including AI developed, operated or provided by third parties. Firms should obtain sufficient assurance from third-party providers, assess whether third-party AI suits the intended use, and keep inventories that include AI inside software-as-a-service products. The guidelines take effect on 7 October 2027.
- CSA Guidelines on Securing AI Systems, October 2024, list supply chain attacks among the main threats and put supply chain security in the development stage of the AI life cycle.
- AI Data Security, the joint guidance from NSA, CISA, FBI and partner agencies in Australia, New Zealand and the UK, May 2025, names the data supply chain and poisoned data as two of the three main risks, and recommends hashing, digital signatures and provenance tracking for training data.
- OWASP LLM03:2025 Supply Chain recommends a software bill of materials, model integrity checks with signing and hashes, and red teaming when selecting third-party models.
None of these documents asks for anything exotic. They ask organisations to know what is in their AI systems, to get assurance from suppliers, and to stay accountable when the supplier is wrong.
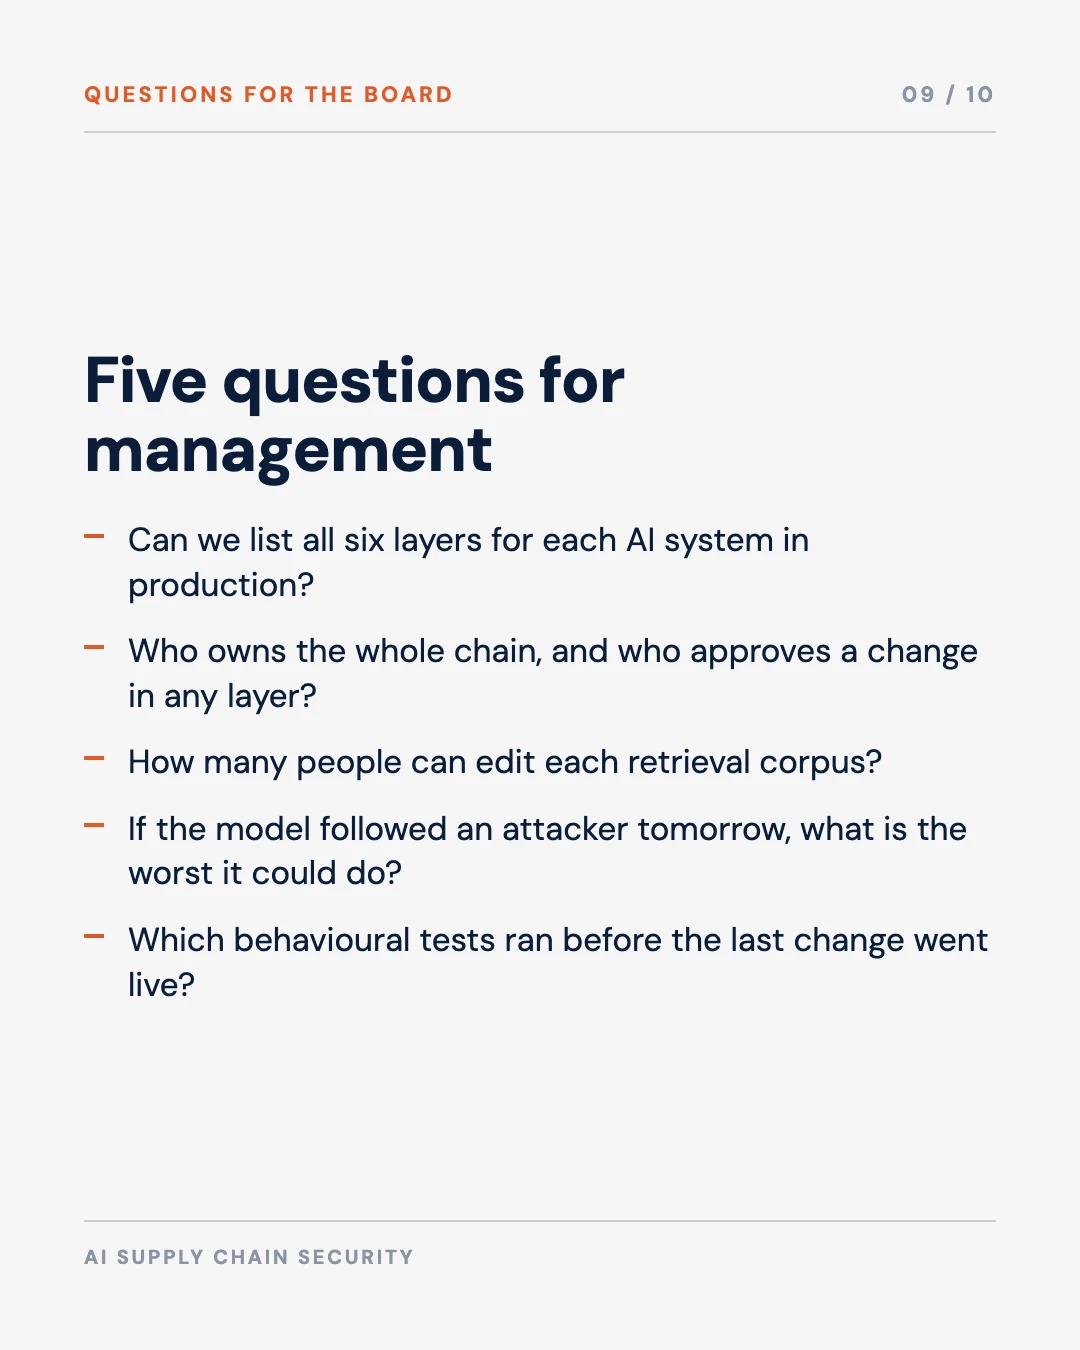
Questions for the board
We would ask management for written answers to five questions:
- For each AI system in production, can we list all six layers: the base model and version, any fine-tunes or adapters, the retrieval sources, the tools and connectors, and the framework?
- Who owns the whole chain for each system, and who approves a change in any layer, including a model update made by the provider?
- Who can add or edit content in each retrieval corpus, and how many people is that?
- If the model followed an attacker’s instruction tomorrow, what is the most damaging action it could take with its current access, and what would stop it?
- When a model, adapter, tool or prompt last changed, which behavioural tests ran before the change went live?
Question four is the one most organisations find hardest. The answer shows whether the controls assume the model can be trusted.
Free tool
AI Vendor Evaluation Scorecard
Rate two shortlisted AI vendors across nine due-diligence dimensions and see where each carries hidden risk. Add the provenance and integrity questions in this post to the conversation.
Evidence & Methodology
The research results, incidents and guidance come from their primary sources. The six-layer map, the control gap table, the three design properties and the insurer register entry are our own, built from assurance work and the published cases, and we have marked them.
| Claim | Source | Grade |
|---|---|---|
| About 250 poisoned documents backdoored models from 600M to 13B parameters; 0.00016% of training tokens for the largest | Anthropic, UK AISI and Alan Turing Institute, 9 October 2025 | Measured, lab study with a low-harm backdoor |
| $60 to poison 0.01% of LAION-400M or COYO-700M | Carlini et al., IEEE S&P 2024 (arXiv 2023) | Measured, researchers did not carry out the attack |
| PoisonGPT: an edited GPT-J-6B passed standard benchmarks while giving a chosen false answer | Mithril Security, 9 July 2023 | Demonstrated by researchers |
| Backdoors persisted through fine-tuning, RL and adversarial training | Hubinger et al., January 2024 | Measured, deliberately trained backdoors |
| nullifAI: two Hugging Face models carried a reverse shell and evaded Picklescan; removed within 24 hours | ReversingLabs, 6 February 2025 | Observed in the wild |
| ShadowPickle evaded ten model scanners; one variant evaded them 63% of the time | Pradhan, Nambiar and Soremekun, July 2026 | Measured, preprint |
| Tool poisoning and rug pull attacks through MCP tool descriptions | Invariant Labs, 1 April 2025 | Demonstrated by researchers |
| postmark-mcp blind-copied every email from version 1.0.16; 1,643 downloads | Koi Security, September 2025, as reported by The Hacker News | Observed in the wild |
| 205,474 unique invented package names across 576,000 samples from 16 models | Spracklen et al., USENIX Security 2025 | Measured |
| MAS: firms remain accountable for third-party AI; effective 7 October 2027 | MAS media release, 7 October 2026 | Regulatory text |
| The six layers, the control gaps, the three properties and the register entry | Our assessment | Our call |
Sources
- Anthropic, UK AI Security Institute and Alan Turing Institute. (2025, October 9). A small number of samples can poison LLMs of any size.
- Carlini, N., Jagielski, M., Choquette-Choo, C. A., et al. (2023). Poisoning web-scale training datasets is practical. arXiv:2302.10149.
- Huynh, D., and Hardouin, J. (2023, July 9). PoisonGPT: How we hid a lobotomized LLM on Hugging Face to spread fake news. Mithril Security.
- Hubinger, E., et al. (2024). Sleeper agents: Training deceptive LLMs that persist through safety training. arXiv:2401.05566.
- ReversingLabs. (2025, February 6). Malicious ML models discovered on Hugging Face platform.
- Pradhan, D., Nambiar, S., and Soremekun, E. (2026). ShadowPickle: Evading machine learning model scanners via stealthy pickle deserialization attacks. arXiv:2607.17503.
- Invariant Labs. (2025, April 1). MCP security notification: Tool poisoning attacks.
- Lakshmanan, R. (2025, September). First malicious MCP server found stealing emails in rogue postmark-mcp package. The Hacker News, reporting research by Koi Security.
- Spracklen, J., et al. (2025). We have a package for you! A comprehensive analysis of package hallucinations by code generating LLMs. USENIX Security 2025.
- OWASP GenAI Security Project. (2024). LLM03:2025 Supply Chain. OWASP Top 10 for LLM Applications 2025.
- OpenSSF. (2025, April). Taming the wild west of ML: Practical model signing with Sigstore.
- NSA, CISA, FBI, et al. (2025, May 22). AI Data Security: Best practices for securing data used to train and operate AI systems. Cybersecurity Information Sheet.
- Cyber Security Agency of Singapore. (2024, October 15). Guidelines and Companion Guide on Securing AI Systems.
- Monetary Authority of Singapore. (2026, October 7). MAS sets out supervisory expectations on responsible AI adoption by financial institutions.
How AI Agents Turn Low-Rated Security Findings Into a Serious Risk
How agent access joins separate findings into one attack path.
The Vulnerability Didn't Change. The Attacker Did.
Why risk acceptances priced on attacker effort need rescoring.
How to Build Governed RAG 2.0 Systems for High-Stakes Use Cases
Controlling what goes into the corpus a model retrieves from.
The Black Box Problem and How to Engineer Around It
Why a model cannot be inspected the way code can.
My thanks to Maria Singh, who co-wrote this post with me. The point that a signed, unaltered model can still be compromised is hers, and it is the one that most changes how a supply chain programme has to be built.
If your organisation wants its AI systems mapped layer by layer, with the integrity and provenance gaps named and owned, that review is where I usually start. My consulting work covers technology and AI risk governance for boards of regulated firms and public agencies.