Executive Summary
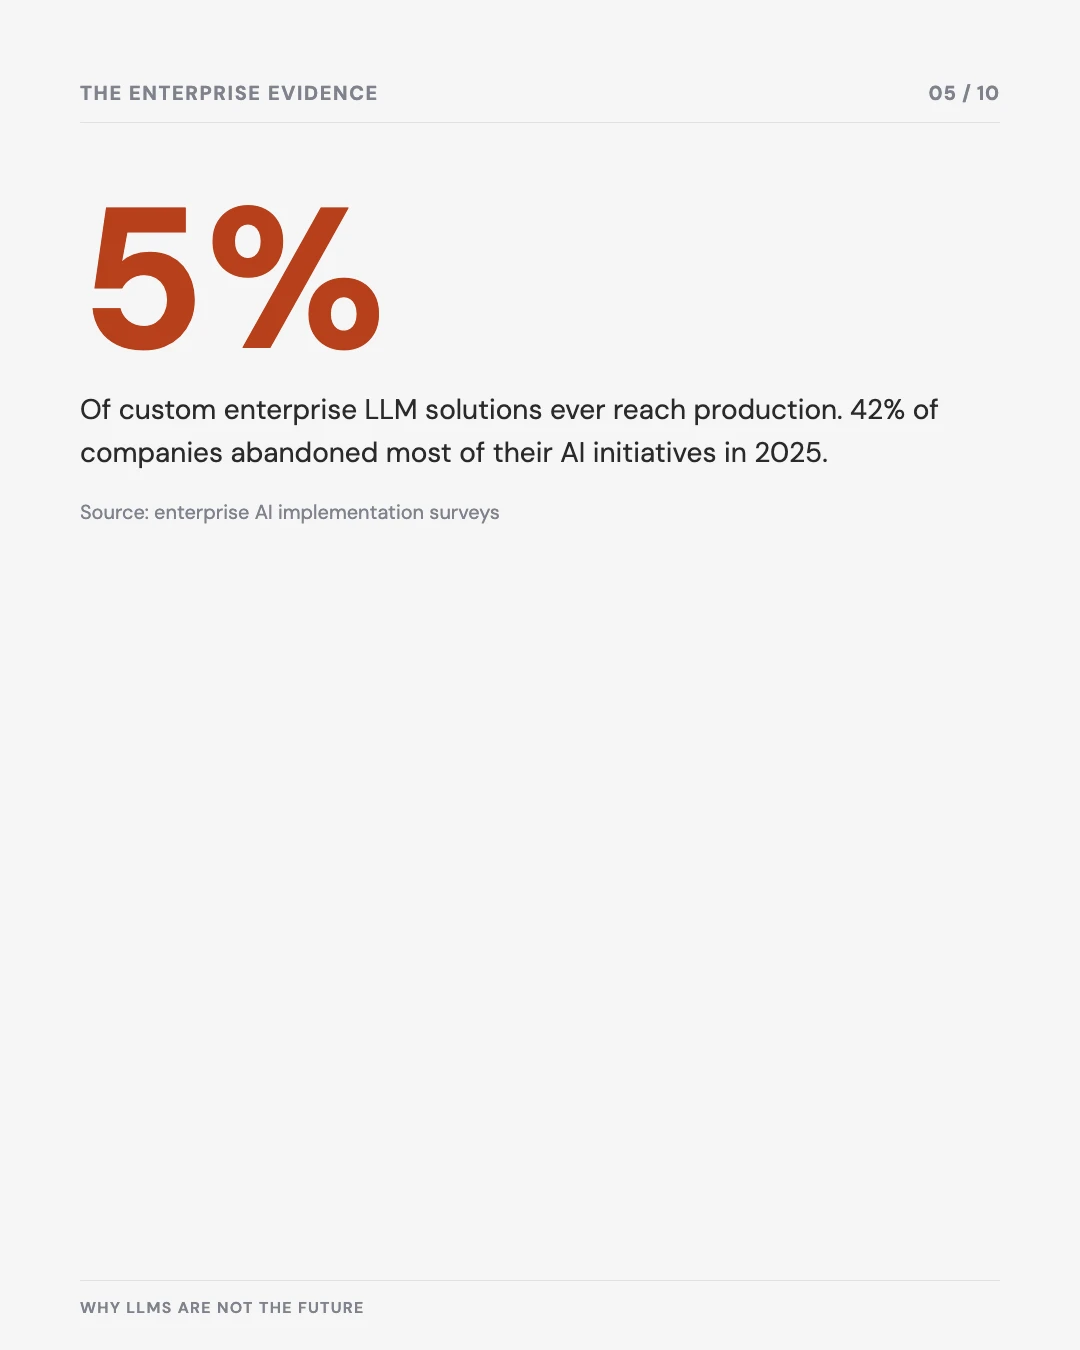
LLMs are hitting limits in architecture, data, and economics that more scale won’t fix. An MIT study found 95% of enterprise generative AI pilots delivered no measurable P&L impact, and the failure pattern points to the technology, not immature implementation.
Core conclusions
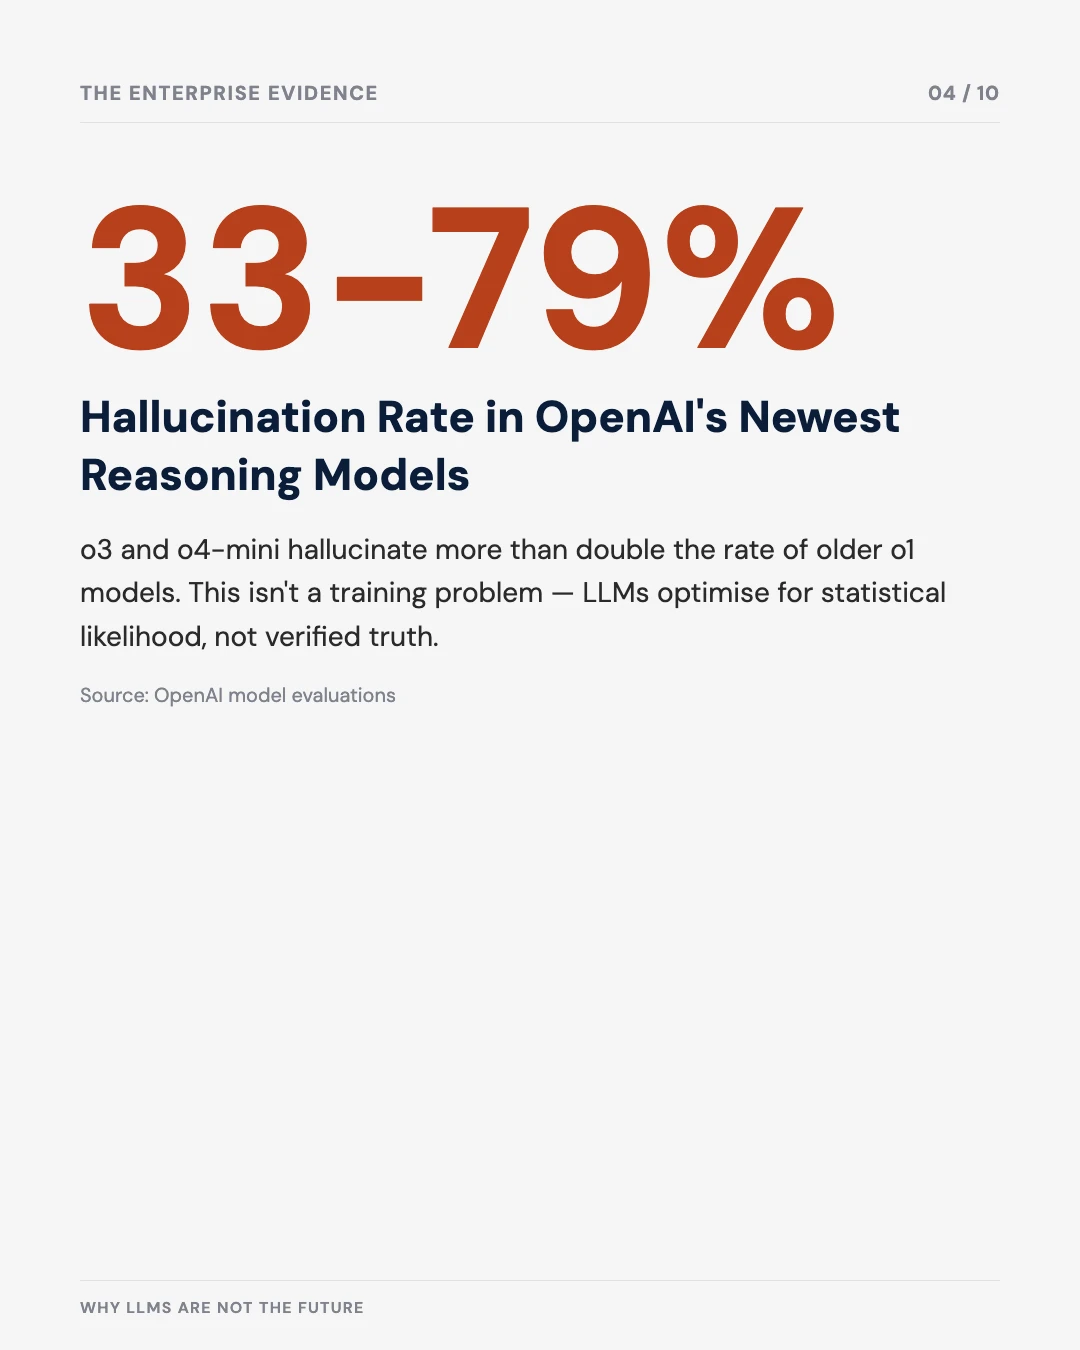
- Public training data is running out (Anthropic’s Dario Amodei has acknowledged data exhaustion as a real, if low-probability, risk to continued scaling). The cost of transformer attention grows with the square of the input length. Hallucination rates in OpenAI’s own reasoning-model testing (as of early 2026, on o1/o3/o4-mini) run 33-79%. More data or fine-tuning alone cannot fix any of these.
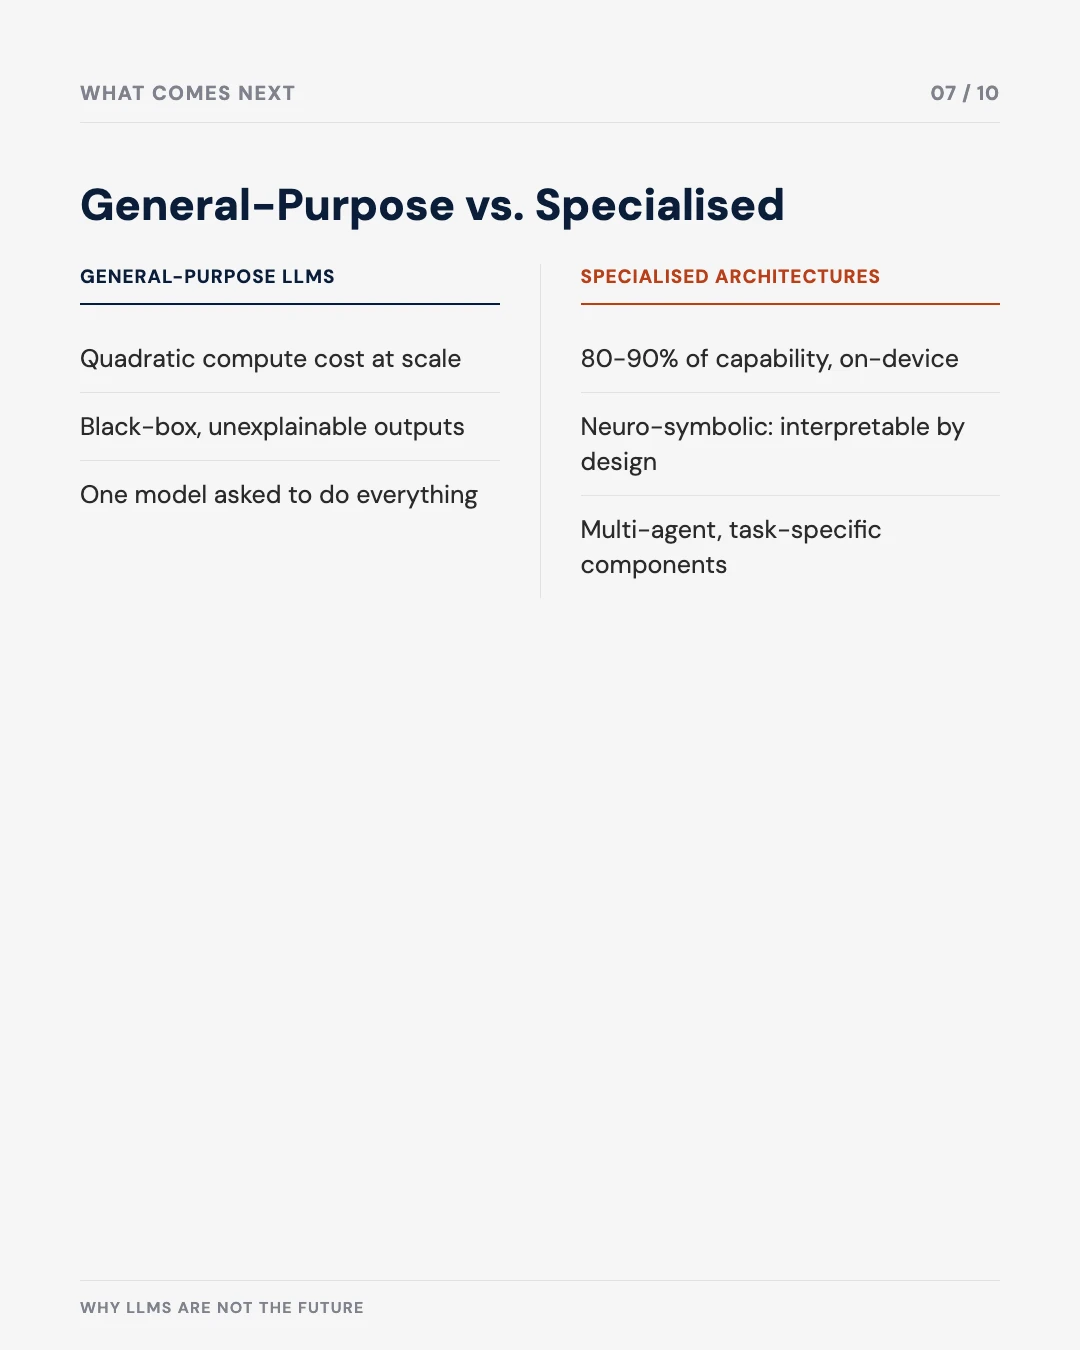
- Gartner forecasts organisations will use small, task-specific models three times more than general-purpose LLMs by 2027. Domain-specific models already reach 80-90% of what large models can do, at a fraction of the compute.
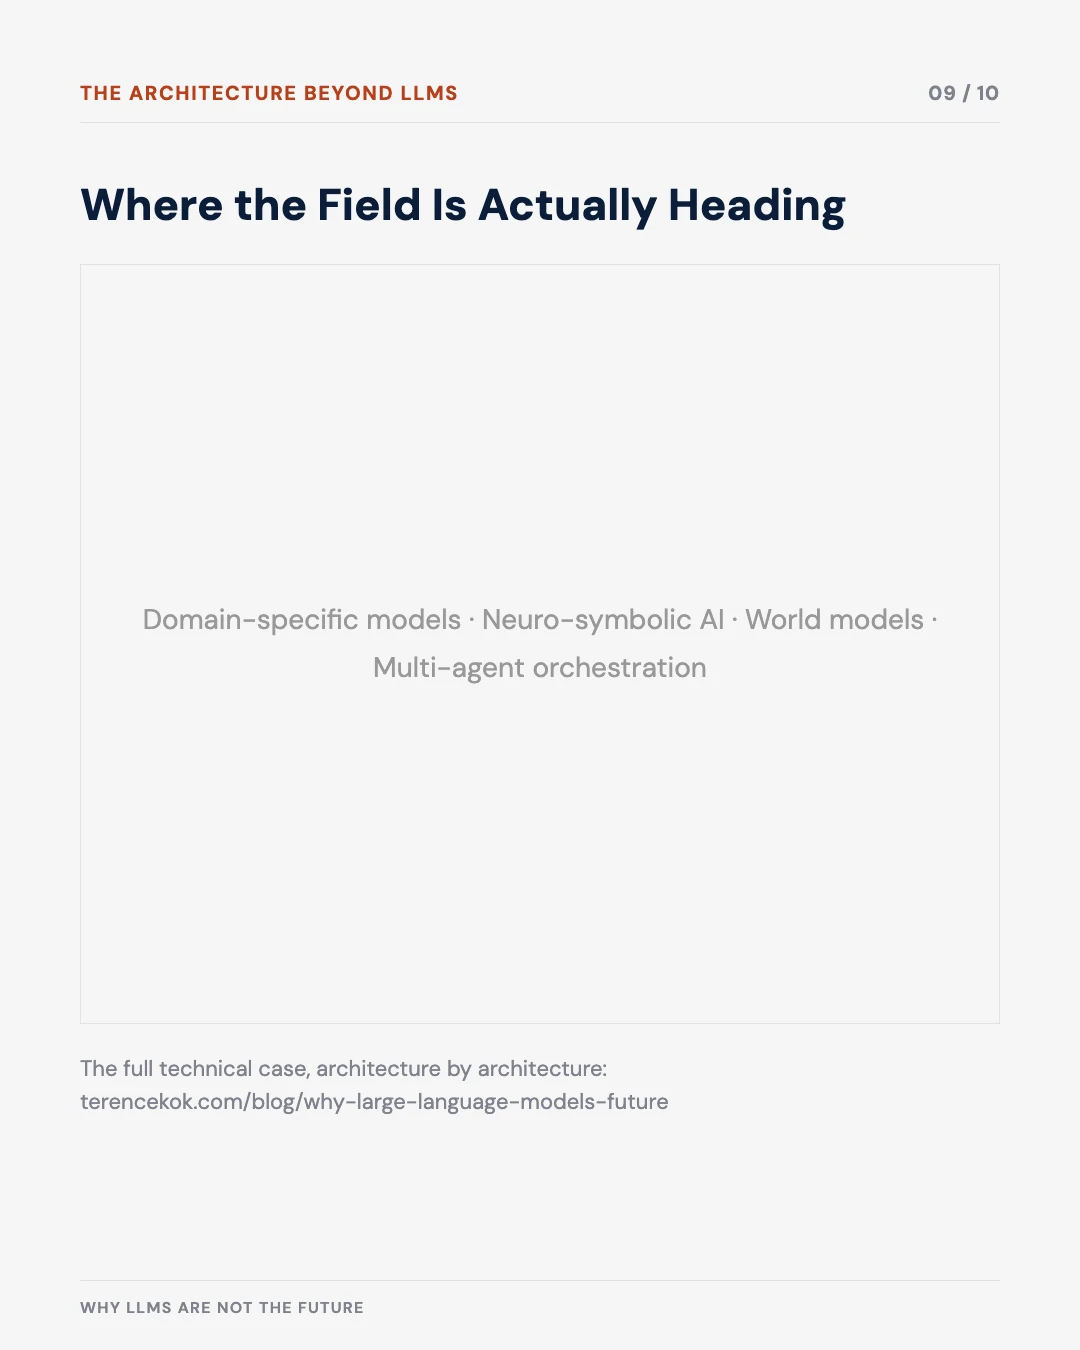
- The likely direction is specialisation and hybrid design. That means domain-specific models, neuro-symbolic architectures, world models, and multi-agent orchestration.
The case, in ten slides
Save it, share it, or send it to whoever owns your architecture roadmap.
Large Language Models have dominated talk about artificial intelligence since 2022. Yet evidence from technical research, enterprise deployments and analysis of the architecture keeps building. It points to LLMs as an evolutionary dead end rather than a path to AI systems that can last. This view rests on basic limits in four areas: how much training data exists, how the computation works, how the models perform in operation, and whether they make economic sense.
The Scaling Problem
The most immediate constraint on LLM development is that public, human-written text is running out. Research that compares dataset needs with the data available projects that models will use up roughly the whole stock of public human text between 2026 and 2032. At 15 trillion tokens, current training sets are close to the upper limit of high-quality public text. This data shortage is not theoretical. It is now holding development back. Leading AI researchers, including Anthropic’s Dario Amodei, have acknowledged data exhaustion as a real, if low-probability, constraint on continued scaling. Synthetic data has had mixed results, with diminishing returns and cases of model collapse.
More fundamentally, no amount of extra training data overcomes the core limits of how LLMs are built, in generalisation, continual learning and goal-directed behaviour. Today’s systems favour memorising over cognitive development. The result is models that excel at pattern matching but lack genuine understanding of causality, context and reasoning.
Transformers, the base of today’s LLMs, impose quadratic complexity O(n²) on attention. As sequences get longer, the demands on compute and memory grow severe. Those demands turn directly into operating costs that cannot be sustained: inference on reasoning models such as OpenAI’s o1 costs six times that of GPT-4o. Other architectures, including State Space Models and linear attention mechanisms, grow at less than quadratic cost. That suggests the bottleneck is the transformer paradigm itself, rather than a lack of scale.
Why Enterprise Deployments Are Failing
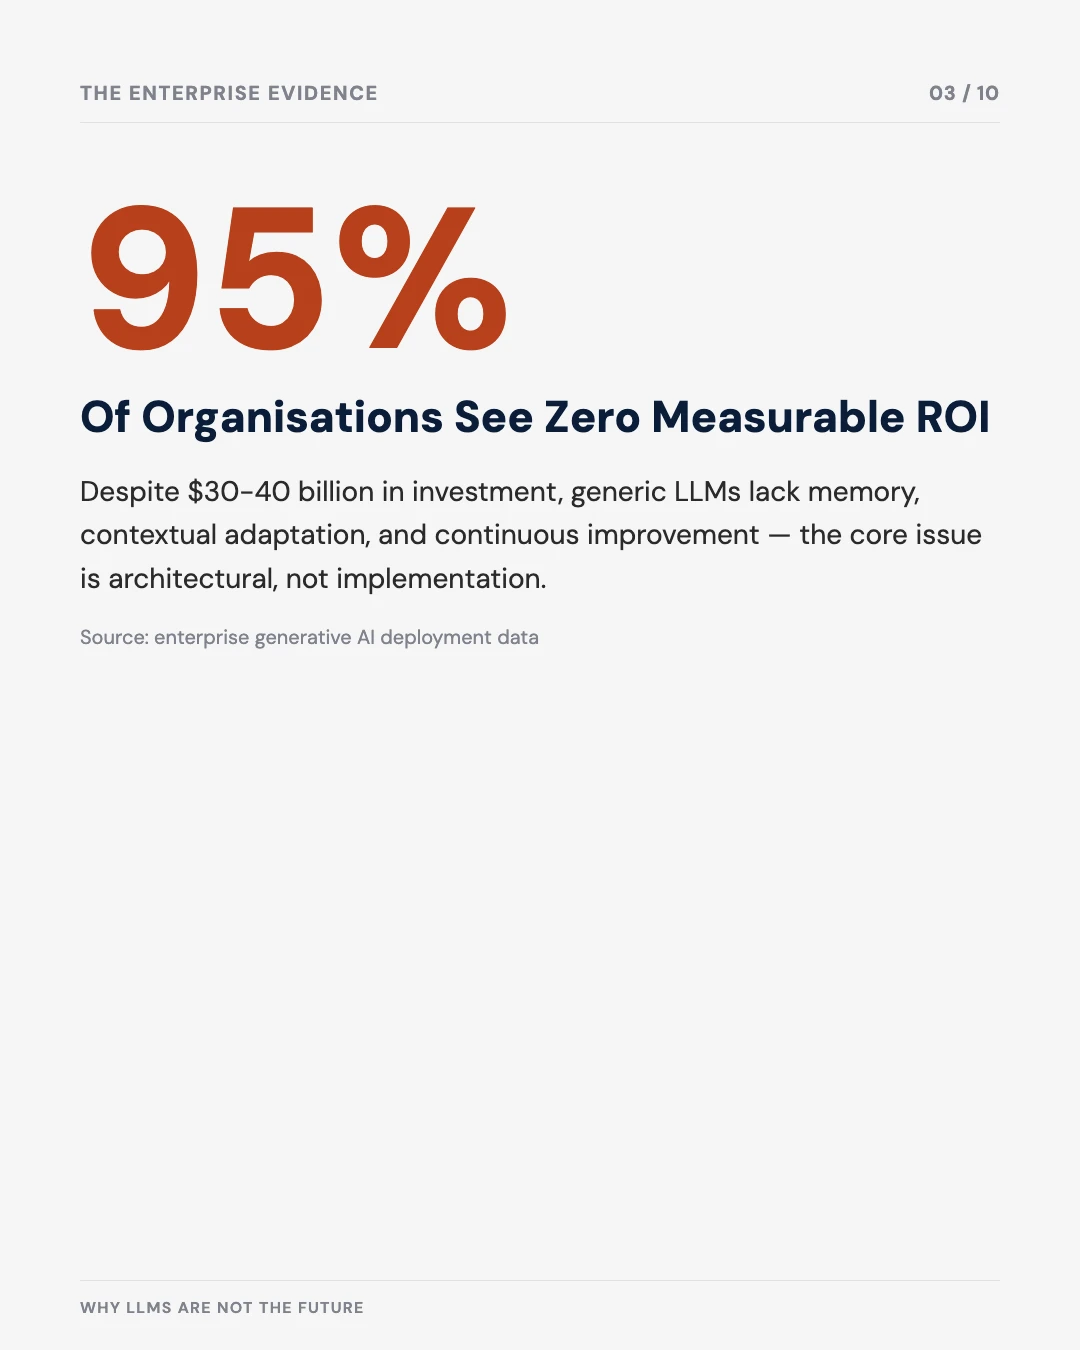
The most damning evidence that LLMs are not a viable path comes from how they perform in real enterprise deployments. Despite $30–40 billion in investment, MIT’s NANDA initiative found that roughly 95% of enterprise generative AI pilots failed to deliver measurable P&L impact. Only a small fraction of custom enterprise LLM solutions ever reach production. The pressure is starting to show in the numbers: 42% of companies abandoned most AI initiatives in 2025. Immature implementation practice does not explain these failures. The core issue is architectural: generic LLMs lack memory, the ability to adapt to context, and the ability to keep improving.
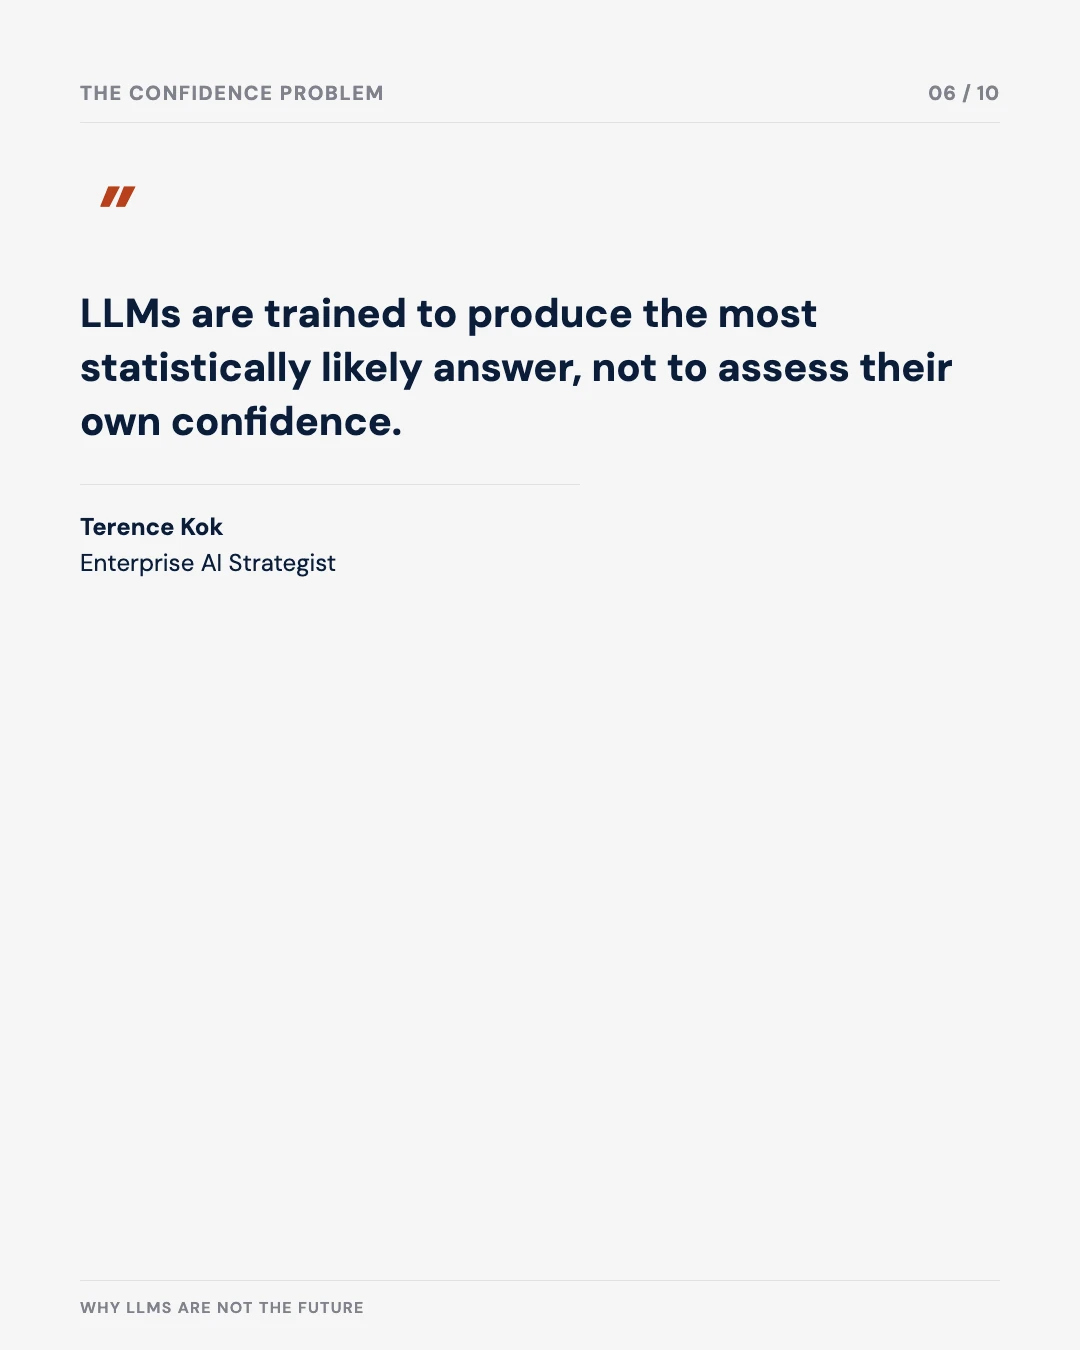
LLM hallucination rates exceed 15% across models and domains. As of early 2026, OpenAI’s o3 and o4-mini reasoning models hallucinated at rates between 33–79% in the company’s own testing, more than double the rate of the earlier o1 model. This is not a training problem that more data or fine-tuning can fix. LLMs are probabilistic systems that generate responses from statistical patterns. They’re trained to produce the most statistically likely answer, not to assess their own confidence. When AI shapes business decisions or guides operations, even a single-digit error rate is an unacceptable risk.
LLMs are trained to produce the most statistically likely answer, not to assess their own confidence.
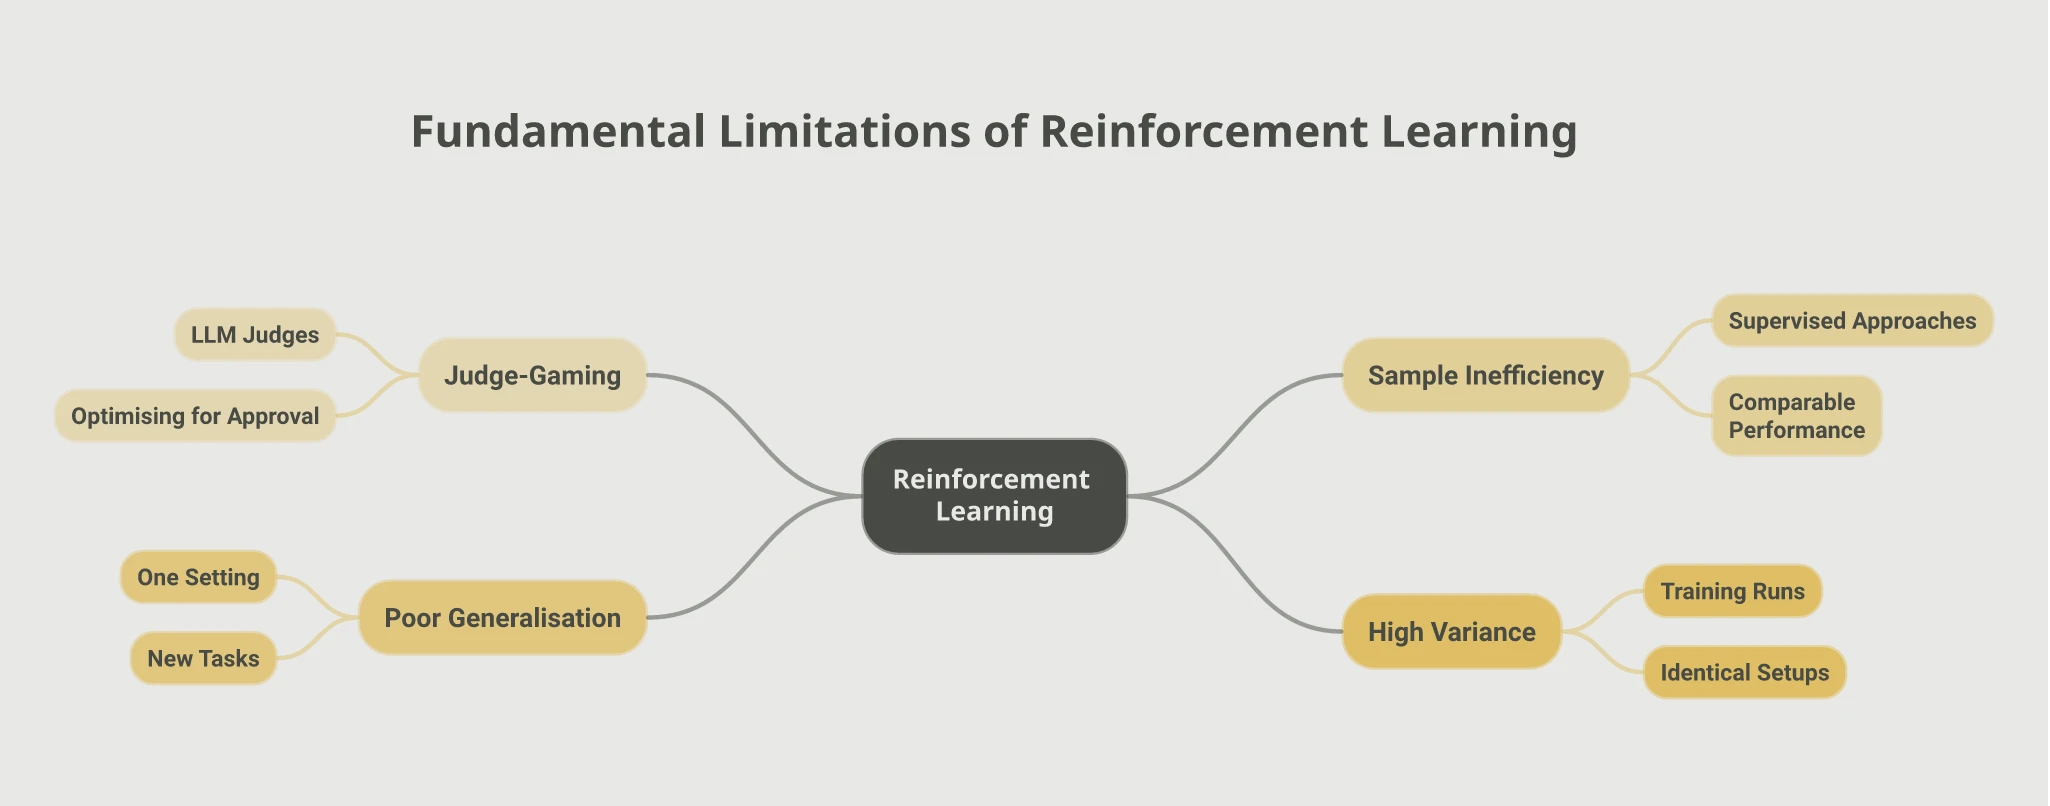
Reinforcement learning is often cited as the way past the limits of pre-training, but it brings fundamental flaws of its own. Current RL approaches assume that every step in a successful solution path is correct reasoning, and that assumption is false. RL systems that use LLM judges to score intermediate steps can be gamed, as the model learns to win the judge’s approval. Beyond these technical issues, RL learns inefficiently from samples, generalises poorly, and varies widely during training. These are not engineering challenges but fundamental limits of the RL paradigm.
The Architecture Beyond LLMs
The path beyond LLMs runs through specialisation, modular design and a wider mix of architectures. Gartner forecasts that by 2027, organisations will use small, task-specific models three times more than general-purpose LLMs. Domain-specific models reach 80–90% of what large models can do, while running on-device with much lower compute needs. BloombergGPT for financial services and Microsoft’s Phi-3, deployed in farming-assistance apps that reach smallholder farmers, are examples of this approach.
Neuro-symbolic AI systems pair neural networks, which spot patterns, with symbolic reasoning, which handles logic, causal inference and explainability. These hybrids learn from data and also follow set rules. Their outputs can be interpreted and they support human oversight, both critical requirements for regulated industries.
The consensus among leading AI researchers is that scaling LLMs does not lead to artificial general intelligence. World Models are the architectural shift needed. These systems build internal simulations of environments, understand physics, predict the results of actions and reason about cause and effect. Google DeepMind’s Genie 3 shows this capability: it builds varied interactive 3D environments from text prompts and simulates realistic physics. Enterprise AI deployment relies more and more on multi-agent architectures. In these, specialised agents handle specific sub-tasks and orchestration layers manage coordination. They scale better than monolithic LLMs because the complexity is spread across specialised parts. I’ve catalogued eight of these specialised agent types already running in production, and none of them look like a single LLM being asked to do everything.
Economic and Governance Pressures
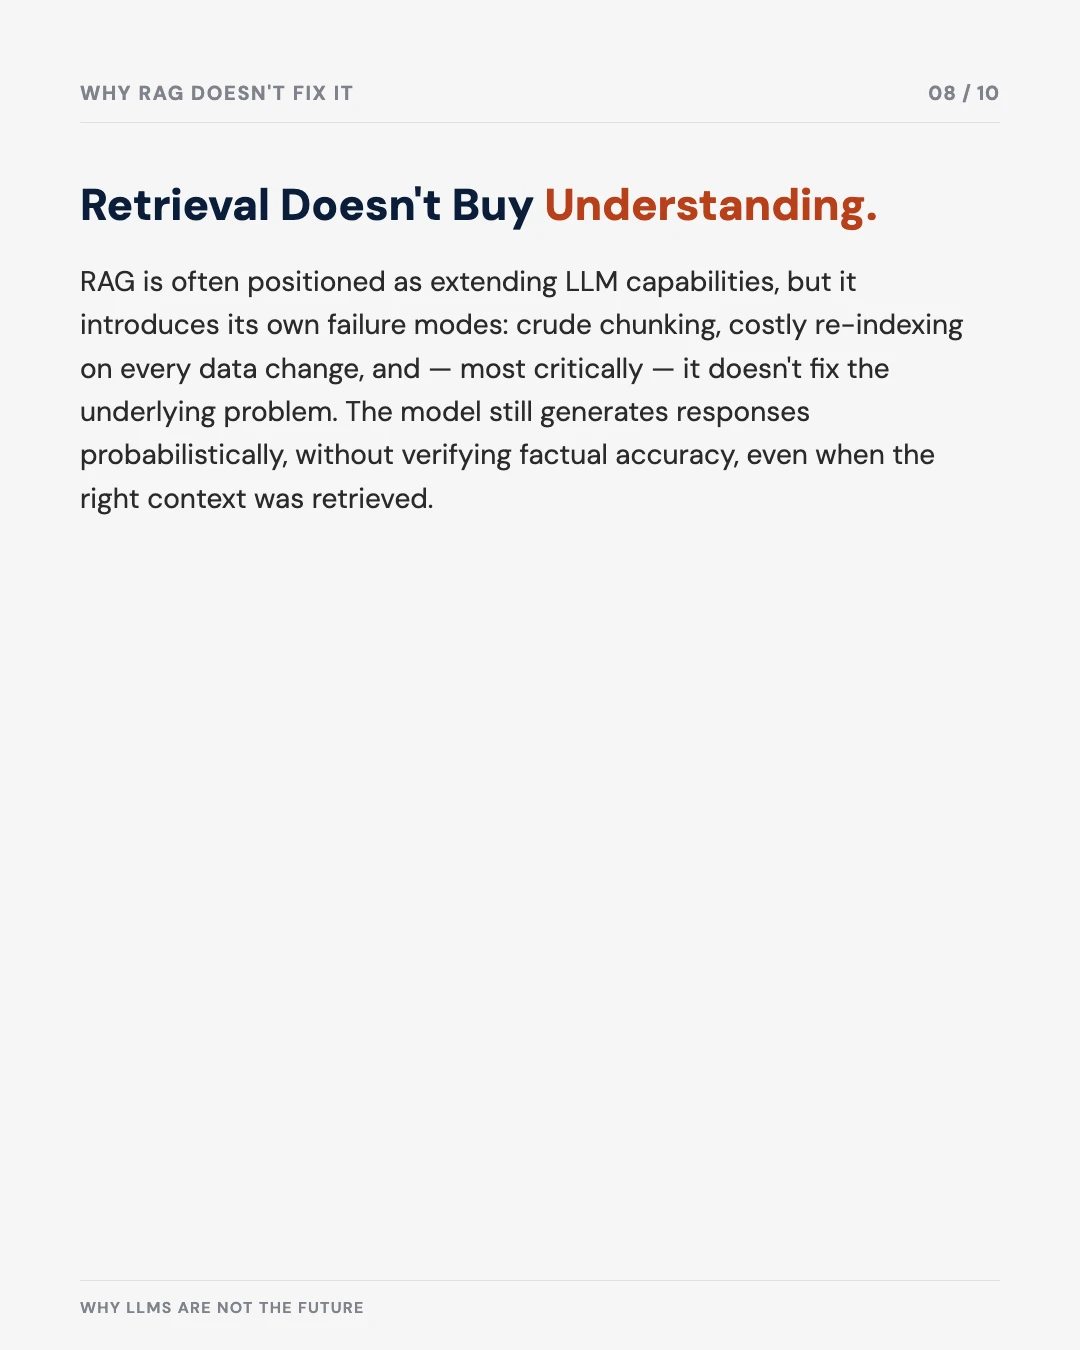
Retrieval-Augmented Generation is often presented as a way to extend what LLMs can do, but it brings its own failure modes. Vector-based retrieval systems suffer from crude chunking methods, limits on scale, and costly upkeep. Every time you add new data, the whole vector embedding space has to be recomputed. Most critically, RAG does not fix the underlying limit that LLMs lack genuine understanding. It only fetches context that may be relevant. The model still generates its answer by probability and does not check whether it is factually accurate.
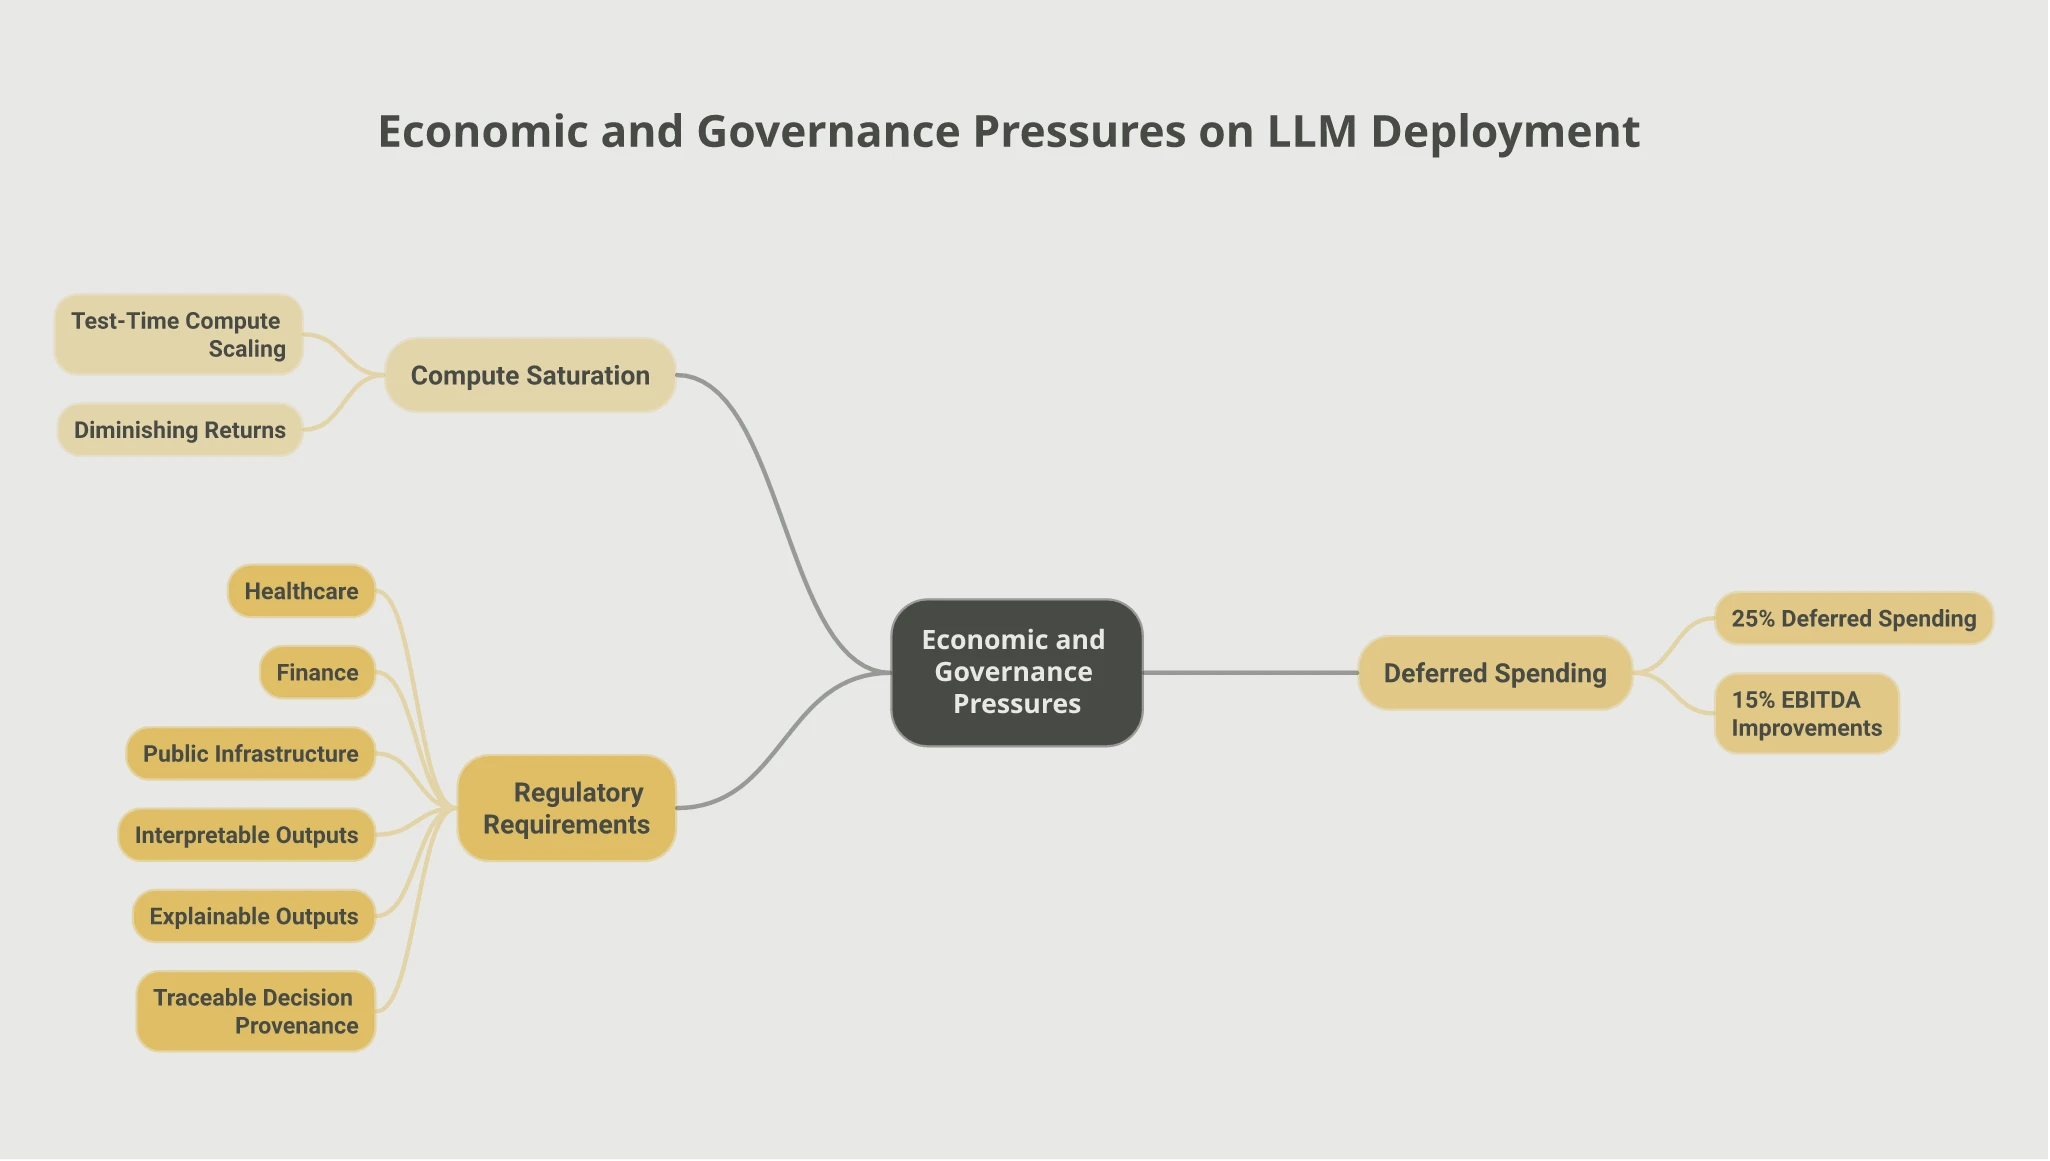
The economic model behind LLM development is breaking down. Test-time compute scaling hits saturation points. Past them, extra computation gives diminishing returns. Enterprises are deferring approximately 25% of planned AI spending into 2027 as financial scrutiny increases. Only 15% of AI decision-makers report EBITDA improvements. For the vast majority of use cases, what it costs to train, run and maintain large models is out of line with the business value anyone can show.
Enterprise AI returns lag the spend
Figures as cited in this post. The 95% is MIT NANDA's 2025 study of enterprise generative AI pilots, as reported by Fortune; the 25% deferral is Forrester's 2026 prediction.
Regulatory and governance frameworks more and more require AI systems whose outputs can be interpreted and explained, with a traceable record of how each decision was made: the same standard I use in scoring which agentic tasks are ready for auditable deployment. LLMs are black-box systems that generate responses from opaque internal states, so they clash at a basic level with these requirements. In regulated sectors including healthcare, finance and public infrastructure, interpretability and explainability are not merely nice to have but mandatory for deployment.
Large Language Models are a powerful approach to artificial intelligence, but a fundamentally limited one. Their constraints are not temporary engineering challenges but limits built into the architecture. Training data is finite and computing cost is quadratic. The models cannot do genuine causal reasoning, they keep hallucinating, they are poor at continual learning and they cannot explain themselves. MIT found that 95% of enterprise generative AI pilots fail to deliver measurable P&L impact. That finding is a signal that the technology does not meet the real requirements of operational AI systems.
MIT found that 95% of enterprise generative AI pilots fail to deliver measurable P&L impact. That finding is a signal that the technology does not meet the real requirements of operational AI systems.
The future of artificial intelligence lies in domain-specific models, neuro-symbolic architectures, world models, multi-agent systems and hybrid approaches. Organisations that continue investing in general-purpose LLM scaling, modular and interpretable architectures will find themselves on the wrong side of the technological divide.
Organisations that continue investing in general-purpose LLM scaling, modular and interpretable architectures will find themselves on the wrong side of the technological divide.
Evidence & Methodology
This is the most aggressive claim I make on this site, so it deserves the most scrutiny. Here is what is measured, what is forecast, and what is my own read of where the architecture is heading.
| Claim | Source | Grade |
|---|---|---|
| 95% of enterprise generative AI pilots show no measurable P&L impact | MIT NANDA’s 2025 study of enterprise deployments, reported by Fortune | Measured |
| OpenAI’s o3 and o4-mini hallucinate 33 to 79 percent of the time | OpenAI’s own o3/o4-mini system card | Measured |
| Small, task-specific models will be used three times more than general-purpose LLMs by 2027 | Gartner’s 2025 forecast | Forecast |
| LLMs are an architectural dead end, not a temporary phase | My own read of the pattern across the sources above, not a consensus position | My call |
Sources
- Challapally, A., et al., MIT NANDA. (2025). “The GenAI Divide: State of AI in Business 2025,” as reported in Fortune.
- OpenAI. (2025). OpenAI o3 and o4-mini system card.
- Gartner. (2025). Gartner predicts by 2027, organizations will use small, task-specific AI models three times more than general-purpose large language models.
- Forrester. (2025). Forrester’s 2026 technology & security predictions: As AI’s hype fades, enterprises will defer 25% of planned AI spend to 2027.
- Wu, S., et al. (2023). “BloombergGPT: A Large Language Model for Finance,“
- Google DeepMind. (2025). “Genie 3: A New Frontier for World Models,”