Executive Summary
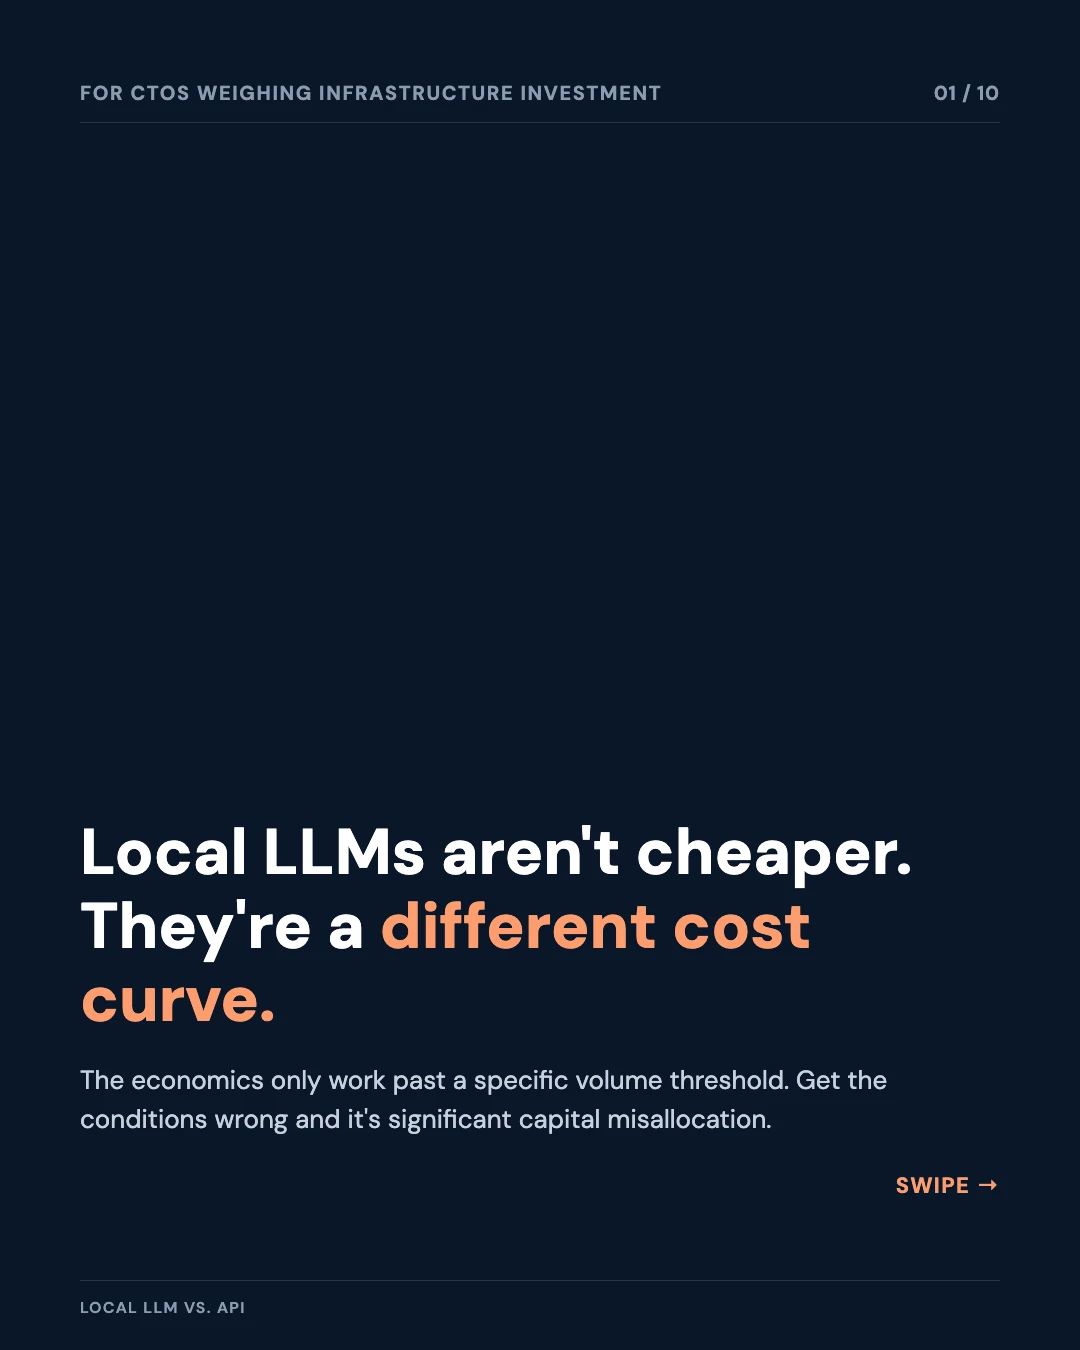
Running an LLM on your own hardware is the right call only under specific conditions. It should not be the default. Where you break even depends on how many tokens you use, what the regulations require, and whether your own team can run the models (MLOps). Get the conditions wrong and a lot of capital goes to the wrong place.
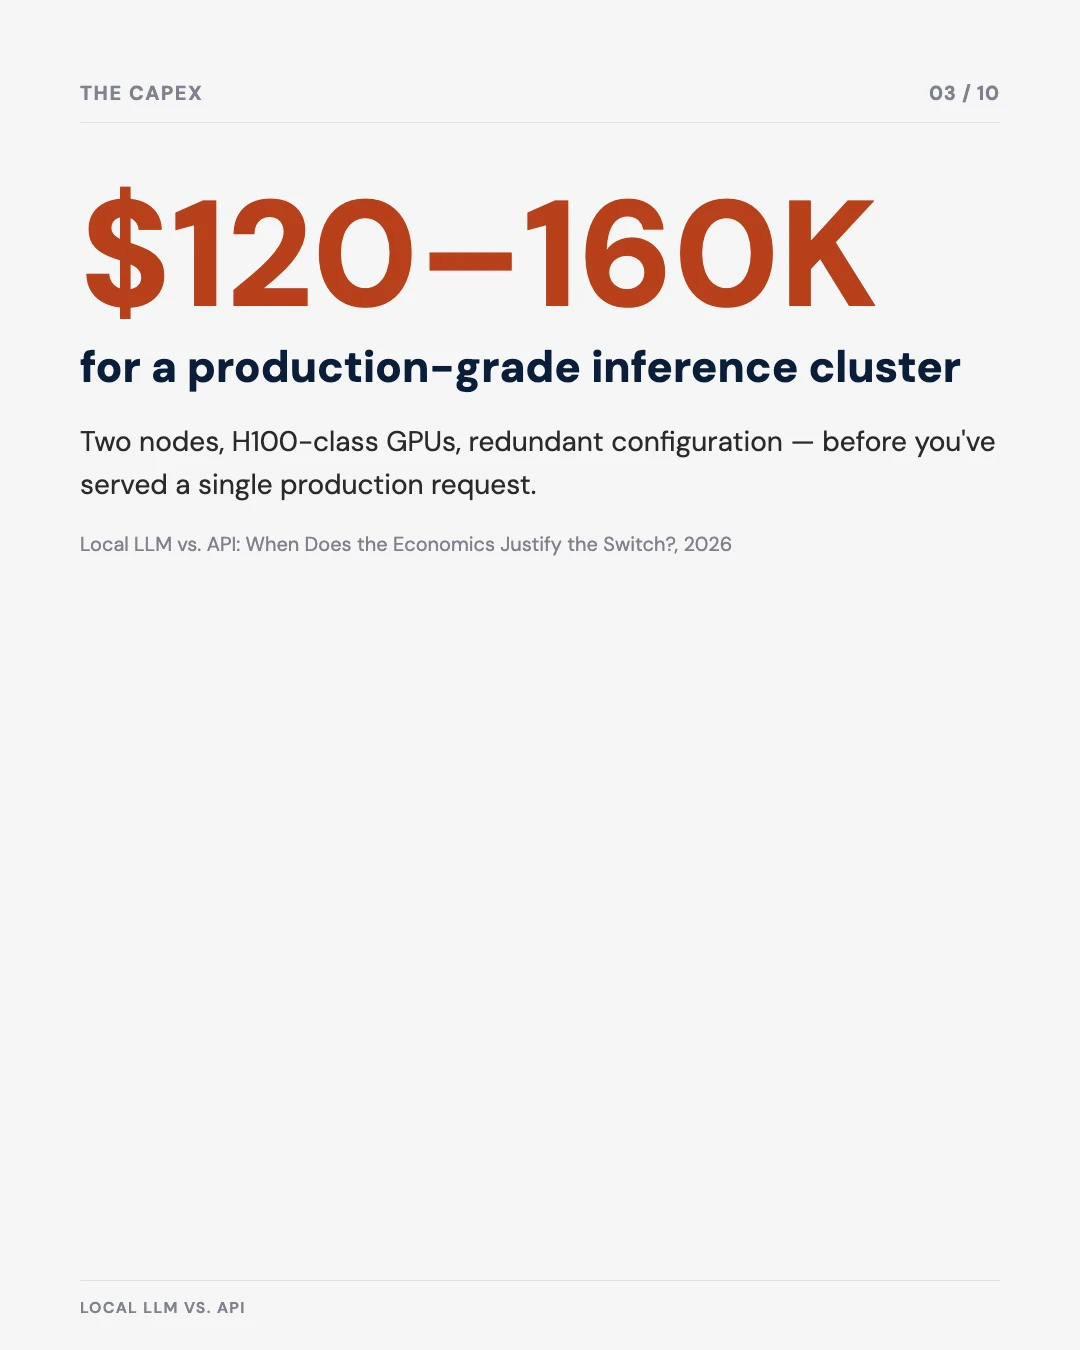
$120–160K
capital cost for a production-grade two-node, H100-class cluster running a 70B-parameter model
$40K/yr
approximate operational overhead on top of that capital cost
$0.003
per 1,000 tokens, the mid-tier API price this break-even math is compared against
Core conclusions
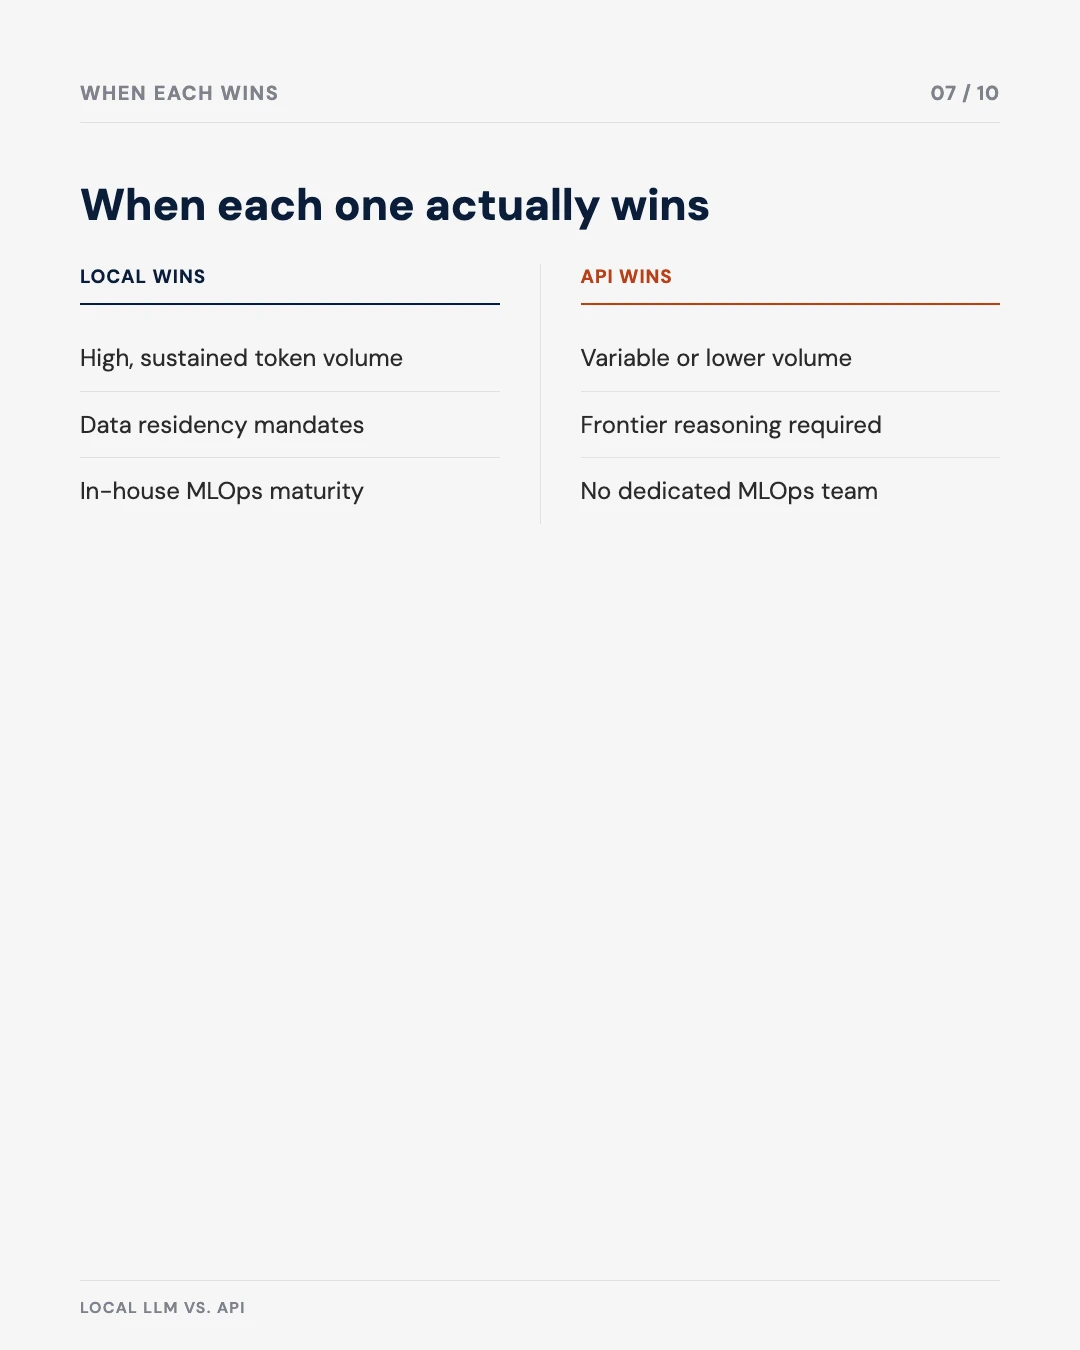
- Running models locally makes sense only when several signs appear together: high token use that lasts, rules that require data to stay in the country, a loss of capability you can live with, and a team in-house that can run the models.
- A tiered set-up sends each task to a local model or an API based on how complex and how sensitive it is. You get the cost savings and keep full capability on the tasks that need frontier models.
- Local LLM hardware is an infrastructure investment, not an AI strategy. Below the volume threshold, managed API tiers give you more capability per dollar.
“The move towards locally hosted large language models is gathering pace across government and enterprise. The economic argument sounds compelling, but the break-even point is more conditional than most procurement conversations acknowledge.”
As AI becomes part of everyday operations, we are starting to question how much it relies on frontier API providers. The conversation usually starts with cost. It soon widens to data sovereignty, speed of response (latency) and control.
Running LLMs locally is the right call under specific conditions. It should not be the default. The conditions are specific, and getting them wrong sends a lot of capital to the wrong place.
When the Local Deployment Argument Holds
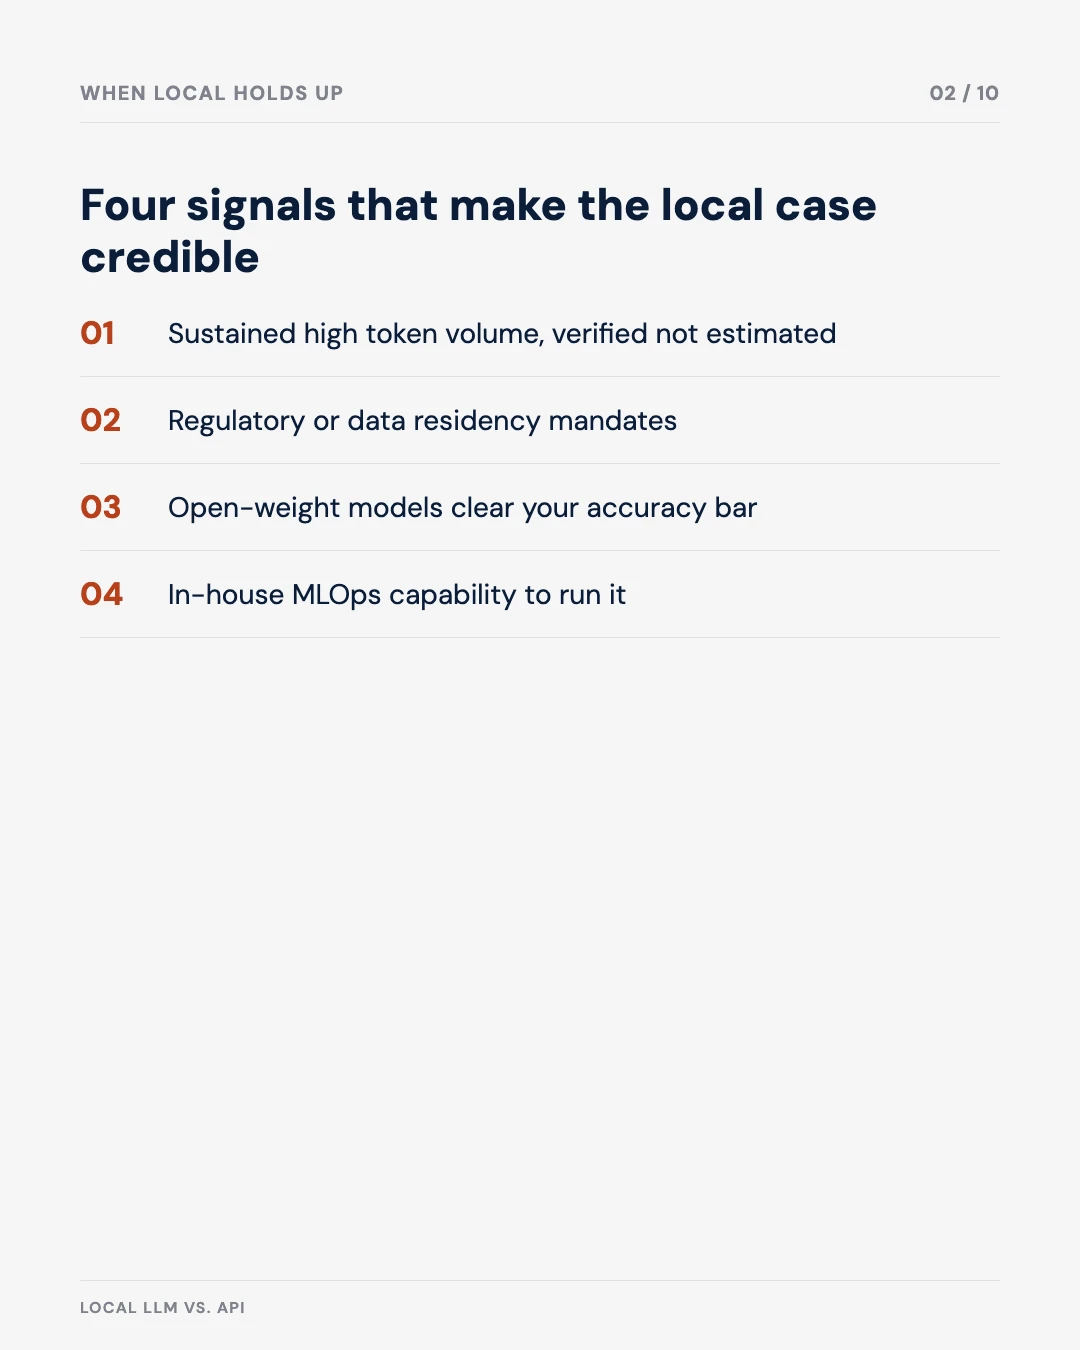
When the following signs appear together, there is a credible case for running models on your own infrastructure:
- Sustained high token volume: Live workloads above several million tokens per day, checked against real operating data.
- Regulatory or data classification requirements: Sector rules or national laws on where data must be held that stop you sending sensitive data through third-party APIs.
- Acceptable capability trade-off: Open-weight models are accurate enough for the specific task, within the error rate you can accept. This is confirmed by testing on real operating tasks, not general benchmarks.
- MLOps capability in-house: Your team can keep up the work of running, monitoring and maintaining the model servers on a set schedule.
The Cost Structure Is Volume-Dependent, With a Clear Break-Even Point
Take a cluster good enough for live use that can run a 70-billion parameter model for many users at once at an acceptable speed (two nodes, H100-class GPUs with backup built in). It costs USD 120,000 to 160,000 up front, plus about USD 40,000 a year to run. Against mid-tier API pricing, where you break even depends on volume.
These figures assume mid-tier API pricing of about USD 0.003 per 1,000 tokens, and hardware written off over three years. Prices vary by provider and model tier. The ratios show how the costs relate; they are not exact quotes.
“The local LLM is not cheaper in the short term. It carries a lower marginal cost at scale, with higher fixed cost and operational complexity.”
Interactive · Break-Even Calculator
Drag the slider to your own daily token volume — local infrastructure only wins on cost past a very high threshold
View the numbers as a table
| Daily tokens | Local cluster, 3-yr | API spend, 3-yr | Cheaper option |
|---|---|---|---|
| 10M | ~$260,000 | ~$32,850 | API |
| 25M | ~$260,000 | ~$82,125 | API |
| 50M | ~$260,000 | ~$164,250 | API |
| 79M | ~$260,000 | ~$259,515 | API |
| 100M | ~$260,000 | ~$328,500 | Local |
| 150M | ~$260,000 | ~$492,750 | Local |
Assumes a $120–160K capital, $40K/yr opex two-node H100-class cluster and $0.003/1,000-token mid-tier API pricing over a three-year horizon, as set out above. Illustrative of the structural relationship, not a procurement quote — and cost is only one of the four conditions the post lays out for going local.
The Practical Path Is Tiered Rather Than All-Or-Nothing
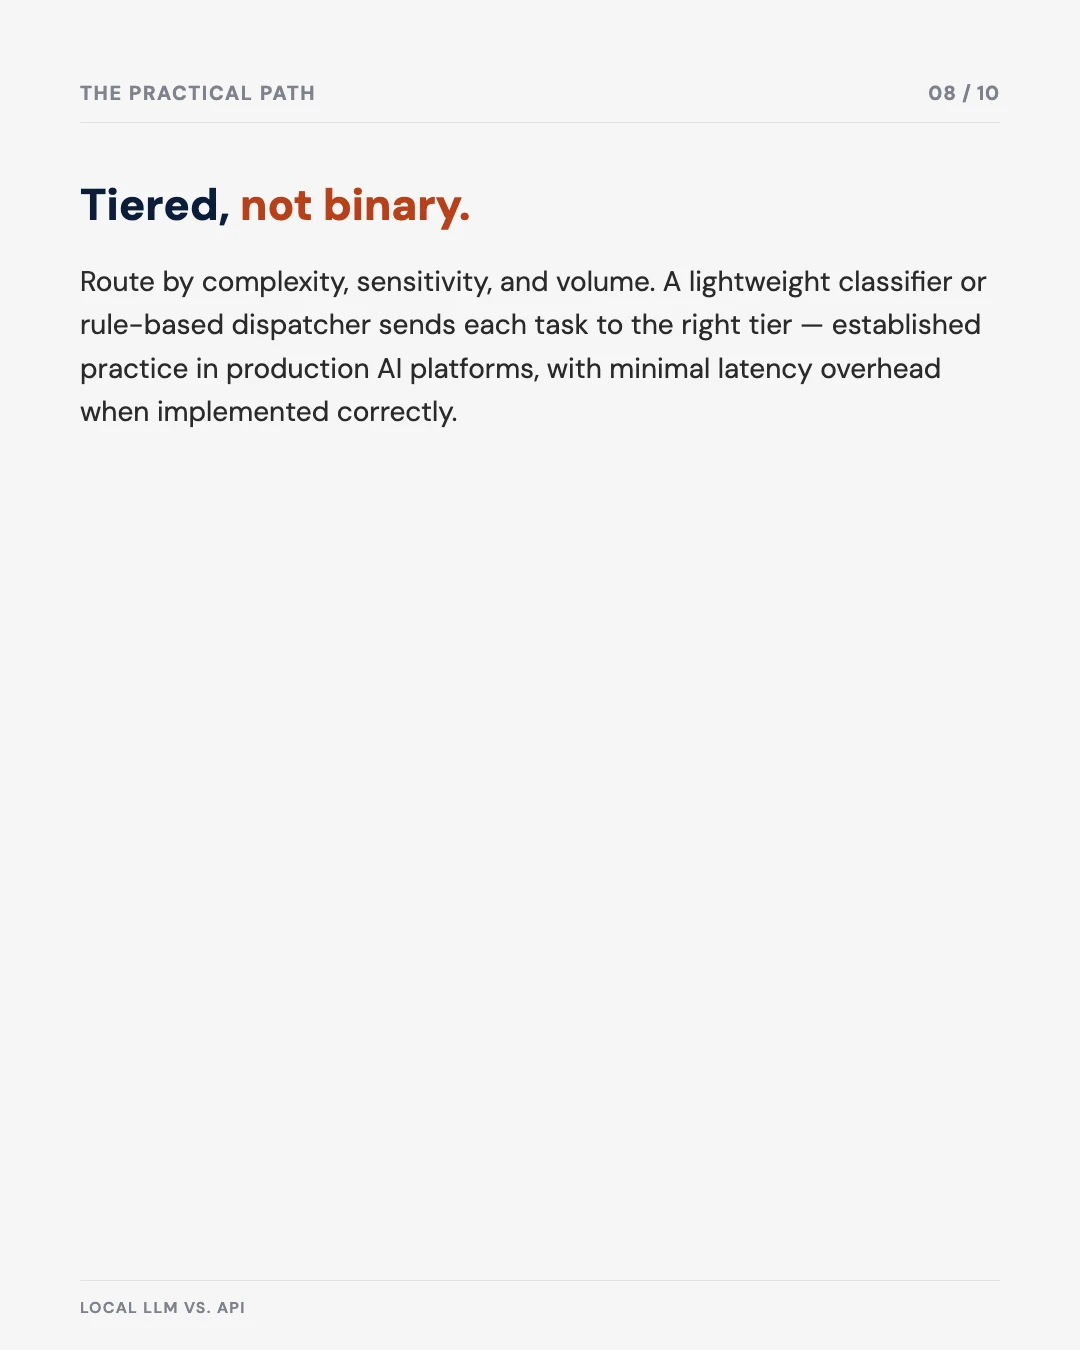
Organisations running AI at scale rarely gain from using only one mode. A tiered set-up (where each task is sent to the right tier based on how complex it is, how sensitive the data is, and how much volume it has) gives you the lower cost of local models and keeps full capability for the tasks that need it.
A small classifier or a set of rules can decide which tier gets each task. This is standard practice in live AI platforms, and when it is done well it adds very little delay.
The Model Capability Gap Is Real and Task-Specific
Open-weight models at the 70-billion-parameter scale, from current families such as Llama, Qwen, and Mistral, come close to frontier models on a range of tasks. They fall short in three places: long chains of complex reasoning, producing reliable structured output under constraints, and using tools over many steps in agent set-ups.
The question that matters is whether the open-weight model is accurate enough for this task, at the volume you need and the error rate you can accept, rather than whether it is “good enough” in general. Test this on real operating tasks before you start buying hardware.
Quantisation further complicates the picture. Running Q4 or Q8 quantised models, which compress the original model weights so they fit in less memory (VRAM) at some cost to accuracy, cuts the VRAM needed and lets the hardware do more. But it makes structured tasks measurably worse. Check the trade-off for each use case.
Decision Checklist Before Committing to Local Inference Infrastructure
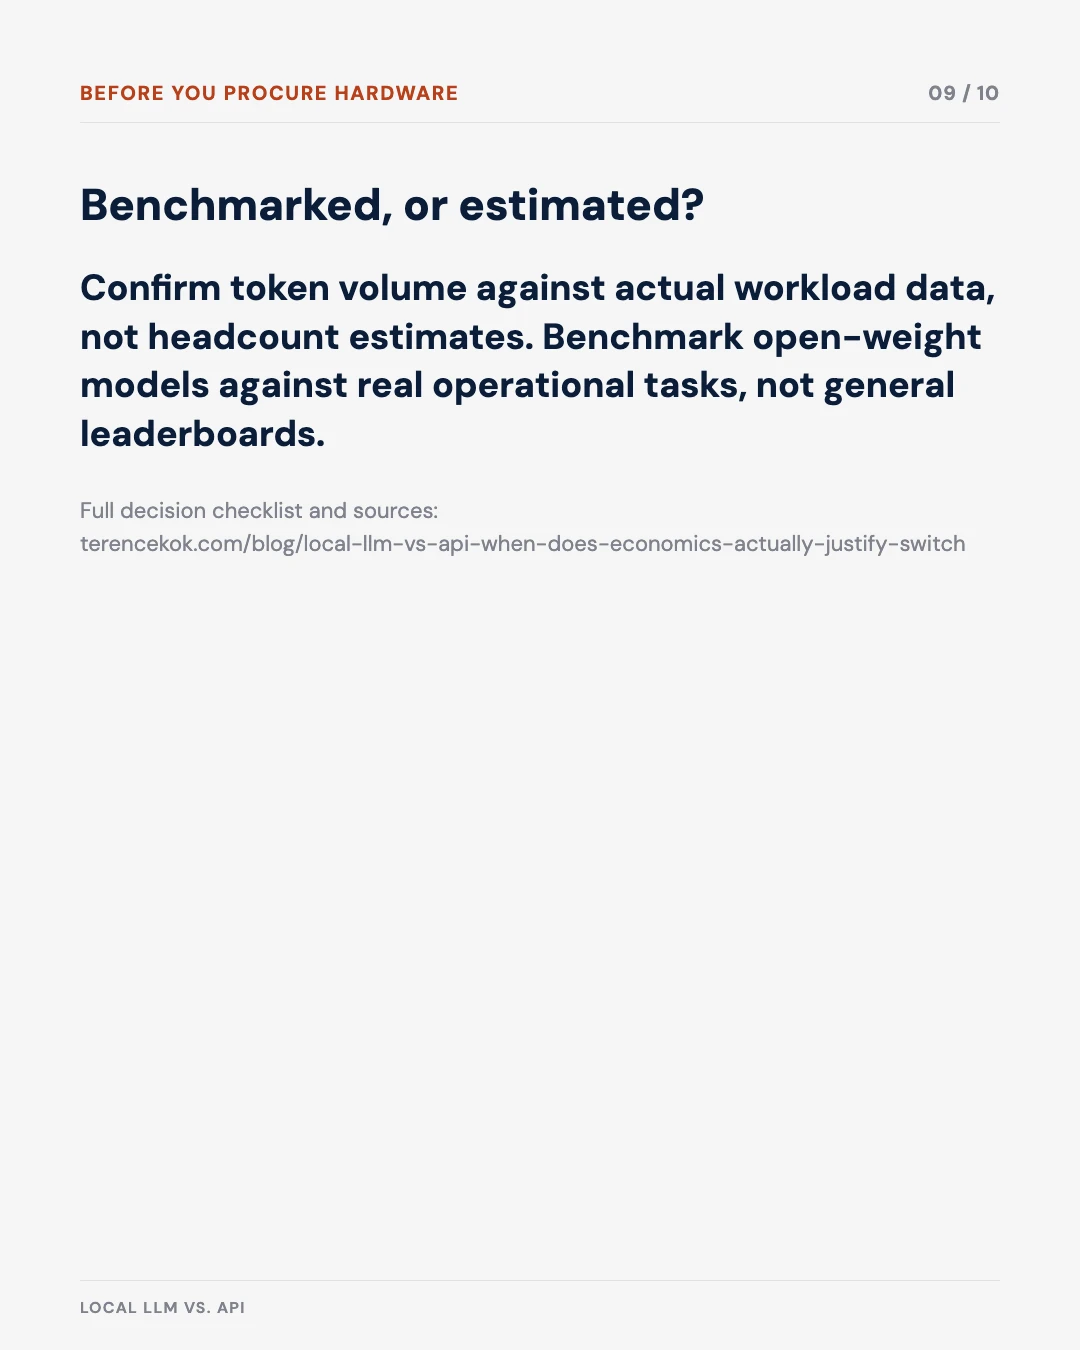
- Check your token volume forecasts against real or pilot workload data, not estimates based on headcount or the number of processes.
- Check whether regulations or data classification rules require local processing: if so, cost comes second.
- Test candidate open-weight models on typical samples of real operating tasks, at the accuracy you need.
- Work out the full TCO, including hardware write-down, MLOps staff, power and the upkeep of models over their life, not just the cost of the hardware.
- Design for tiers from the start. Going local-only gives up capability on tasks that need frontier models.
- Check the quantisation trade-off for each type of task before choosing how to serve the model.
- Set a performance baseline and a review schedule before go-live: unlike managed API services, local models need active governance.
The decision to invest in local LLM hardware is an infrastructure investment, not an AI strategy in itself. It is worth it at scale, under specific regulatory conditions, or where the cost of agent workflows makes relying on APIs unworkable.
For organisations below the volume threshold, managed API tiers (including the private deployment options most major providers now offer) give more capability per dollar spent.
Plan any move to local models around confirmed operating needs and model performance you have tested. Do not plan it around savings that only appear at volumes the programme has not yet reached.
The math, in ten slides
Save it before your next infrastructure procurement conversation.
Free tool
AI Build vs. Buy vs. Partner
The local-versus-API decision is a build-versus-buy decision in disguise: run it through seven criteria including data sensitivity and maintenance appetite before you procure hardware.
Free tool
AI ROI Calculator
Model the local-versus-API financial case against your own team size and tech stack before you commit to either path.